Some equipment failures at a cement plant genuinely come out of nowhere, but most do not. Look closely at a year of maintenance records and the same handful of assets tend to show up again and again, failing in the same general way each time, whether it is a bearing on the same conveyor section, a seal on the same pump, or a refractory section in the same kiln zone. The plants that keep replacing the same part on the same schedule are treating the symptom while the actual failure mode goes uninvestigated. Book a demo to see how failure mode analytics breaks that cycle.
Stop Fixing the Same Failure Twice a Year and Calling It Maintenance
iFactory analyzes your maintenance history to surface recurring failure patterns across cement plant equipment, so your team can address root causes instead of repeating the same repair on the same schedule indefinitely.
Repeated Repairs Feel Like Progress but Often Mask an Unsolved Problem
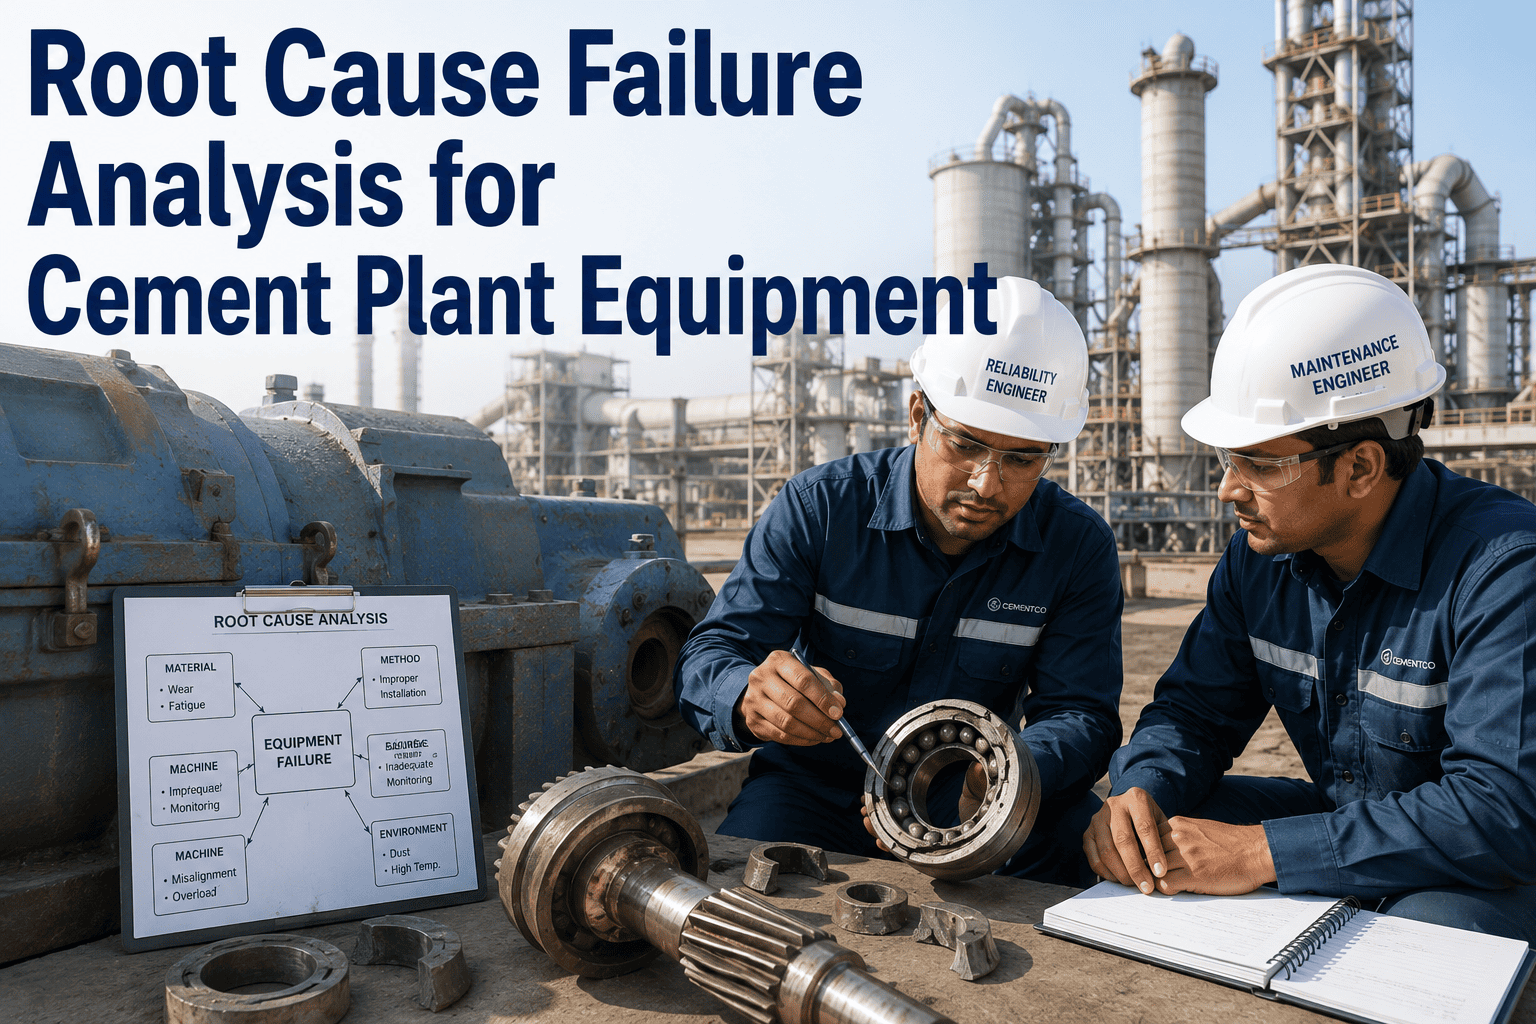
When the same bearing fails every four months, replacing it on schedule feels productive, the work order closes, the equipment runs again, and the maintenance team moves to the next job. But a recurring failure at a consistent interval is a signal, not a routine task. It usually means an underlying condition, misalignment, contamination, inadequate lubrication, or a design mismatch for the actual operating load, is causing the part to fail well before its expected service life. Treating each occurrence as an isolated repair rather than a pattern means the plant pays the labor and parts cost of the failure repeatedly while the root cause continues unaddressed indefinitely.
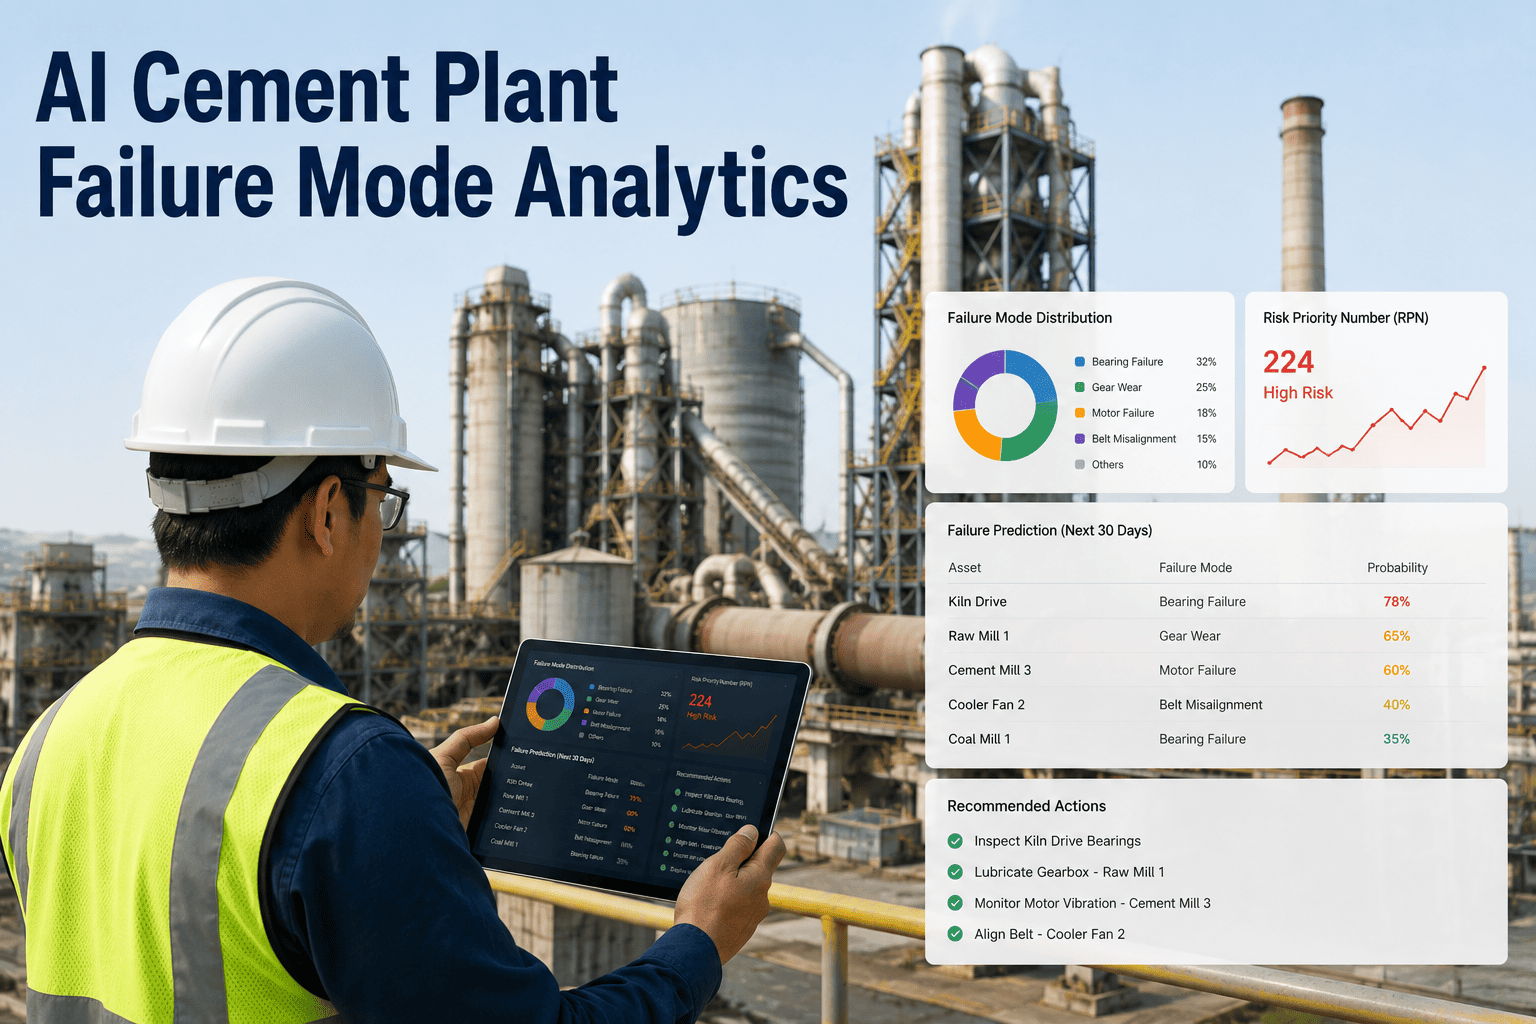
Failure mode analytics exists to catch this pattern automatically. By aggregating maintenance history across every asset and looking for repeated failure types, failure locations, and failure intervals, the analysis surfaces chronic issues that would otherwise stay buried inside years of individual work orders that nobody has time to review side by side.
The financial case for this shift is straightforward once the pattern is visible. A single recurring failure that costs a modest amount to repair each time seems minor in isolation, but multiplied across a dozen occurrences over several years it can represent a substantial cumulative spend, well beyond what a proper root cause investigation and permanent fix would have cost upfront. Maintenance teams rarely see this cumulative figure because it never appears in one place, each occurrence gets logged, closed, and forgotten as an individual event rather than tracked as part of an ongoing pattern that deserves a different kind of response.
Six Failure Categories That Account for Most Chronic Cement Plant Issues
From Scattered Work Orders to a Ranked List of Chronic Failures
iFactory ranks your chronic failure patterns by cumulative cost and downtime so your reliability team knows exactly where to focus root cause analysis first.
Repair-and-Repeat Versus Pattern-Driven Reliability
The distinction between these two approaches usually is not about how skilled the maintenance technicians are, most plants have technically capable teams perfectly able to diagnose and fix what is in front of them. The difference is whether the organization has a mechanism for connecting today's failure to last quarter's failure on the same asset, and whether anyone has the mandate and the time to ask why the pattern keeps recurring instead of simply logging the next work order and moving on.
| Approach | Repair-and-Repeat | Pattern-Driven Reliability |
|---|---|---|
| Response to failure | Fix and close the work order | Fix, log, and check against failure history |
| Recurring failures | Treated as routine maintenance | Flagged automatically for root cause review |
| Cost visibility | Seen per incident only | Seen as cumulative cost across the pattern |
| Spare parts strategy | Reordered after each failure | Adjusted based on true failure frequency |
| Long-term trend | Failure rate stays roughly flat | Failure rate declines as root causes get resolved |
Five Questions a Root Cause Review Should Answer Before Closing a Chronic Failure
Not every flagged pattern needs a lengthy formal investigation, but even a lightweight review should work through the same basic sequence of questions. Skipping straight to a fix without answering these in order is the most common reason a corrective action addresses the symptom rather than the actual cause, and the pattern quietly returns a few months later under a slightly different work order description.
What Resolving Chronic Failures Typically Changes
The shift is gradual rather than immediate. The first pattern resolved rarely feels significant on its own, but as a reliability team works through a ranked list of chronic issues over several quarters, the cumulative effect on unplanned downtime and repeat spending becomes clearly visible in the plant's overall maintenance metrics.
Common Questions About Failure Mode Analytics
How much maintenance history is needed before patterns become reliable?
Meaningful pattern detection typically needs at least twelve to eighteen months of consistent work order history, since seasonal production changes and planned shutdown cycles can otherwise be mistaken for failure trends. Plants with clean, consistently tagged work order data can sometimes surface reliable patterns sooner, while plants transitioning from paper-based or inconsistent digital records may need a data cleanup period first. Even with a shorter history, the analysis can flag candidate patterns for a maintenance team to validate manually, and confidence in those patterns improves automatically as more data accumulates over subsequent months. Book a demo to see what patterns emerge from your existing maintenance records.
Does this replace the need for a formal root cause analysis process?
No, failure mode analytics identifies which failures deserve a formal root cause analysis, it does not replace the analysis itself. Most reliability teams do not have time to run a full root cause investigation on every failure that occurs across a plant, so the analytics layer prioritizes the small number of chronic, high-cost patterns that justify that level of investigation. The structured root cause process, tracing the physical failure back through contributing conditions to an underlying cause, still requires human expertise and often cross-functional input from operations, maintenance, and engineering to complete properly.
Can this analysis catch a failure pattern before it becomes chronic?
Yes, one of the more valuable applications is catching a pattern in its early stages rather than waiting for three or four repeat failures to make it obvious. By tracking failure interval trends rather than just failure counts, the analysis can flag a component where time-to-failure is shortening across successive repairs, which often indicates an underlying condition worsening even before the failure frequency becomes clearly abnormal. Catching that trend early allows a corrective action to happen after the second occurrence instead of the fifth, meaningfully reducing the cumulative cost and downtime the pattern would otherwise generate.
How does chronic failure data connect to spare parts inventory decisions?
Chronic failure patterns often reveal that a plant is over-stocking or under-stocking specific spare parts relative to their true failure frequency. A part ordered based on manufacturer-recommended replacement intervals may actually fail far more often due to an unaddressed root cause, leaving the plant chronically short on that item and relying on expedited shipping. Once the root cause is resolved and failure frequency drops back toward design expectations, inventory levels and reorder points can be adjusted accordingly, reducing both stockout risk during the problem period and excess inventory carrying cost afterward. Contact support to discuss aligning inventory policy with failure analytics.
Who on the maintenance team should own reviewing flagged failure patterns?
Ownership works best when it sits with a reliability engineer or senior maintenance planner who has both the technical background to interpret failure mechanisms and the authority to schedule a root cause investigation outside routine work order flow. In smaller plants without a dedicated reliability role, this responsibility often falls to the maintenance manager, ideally with input from the technicians who actually perform the repairs, since they frequently have informal knowledge about a recurring issue that never made it into the formal work order notes. Building a short recurring review, even monthly, to walk through newly flagged patterns keeps chronic failures from sitting unaddressed for another full year. Book a demo to see how flagged patterns surface for review.
Turn Years of Work Order History Into a Ranked List of Real Problems
iFactory surfaces the chronic failure patterns hiding inside your maintenance records so your reliability team stops repairing the same failure and starts eliminating it.