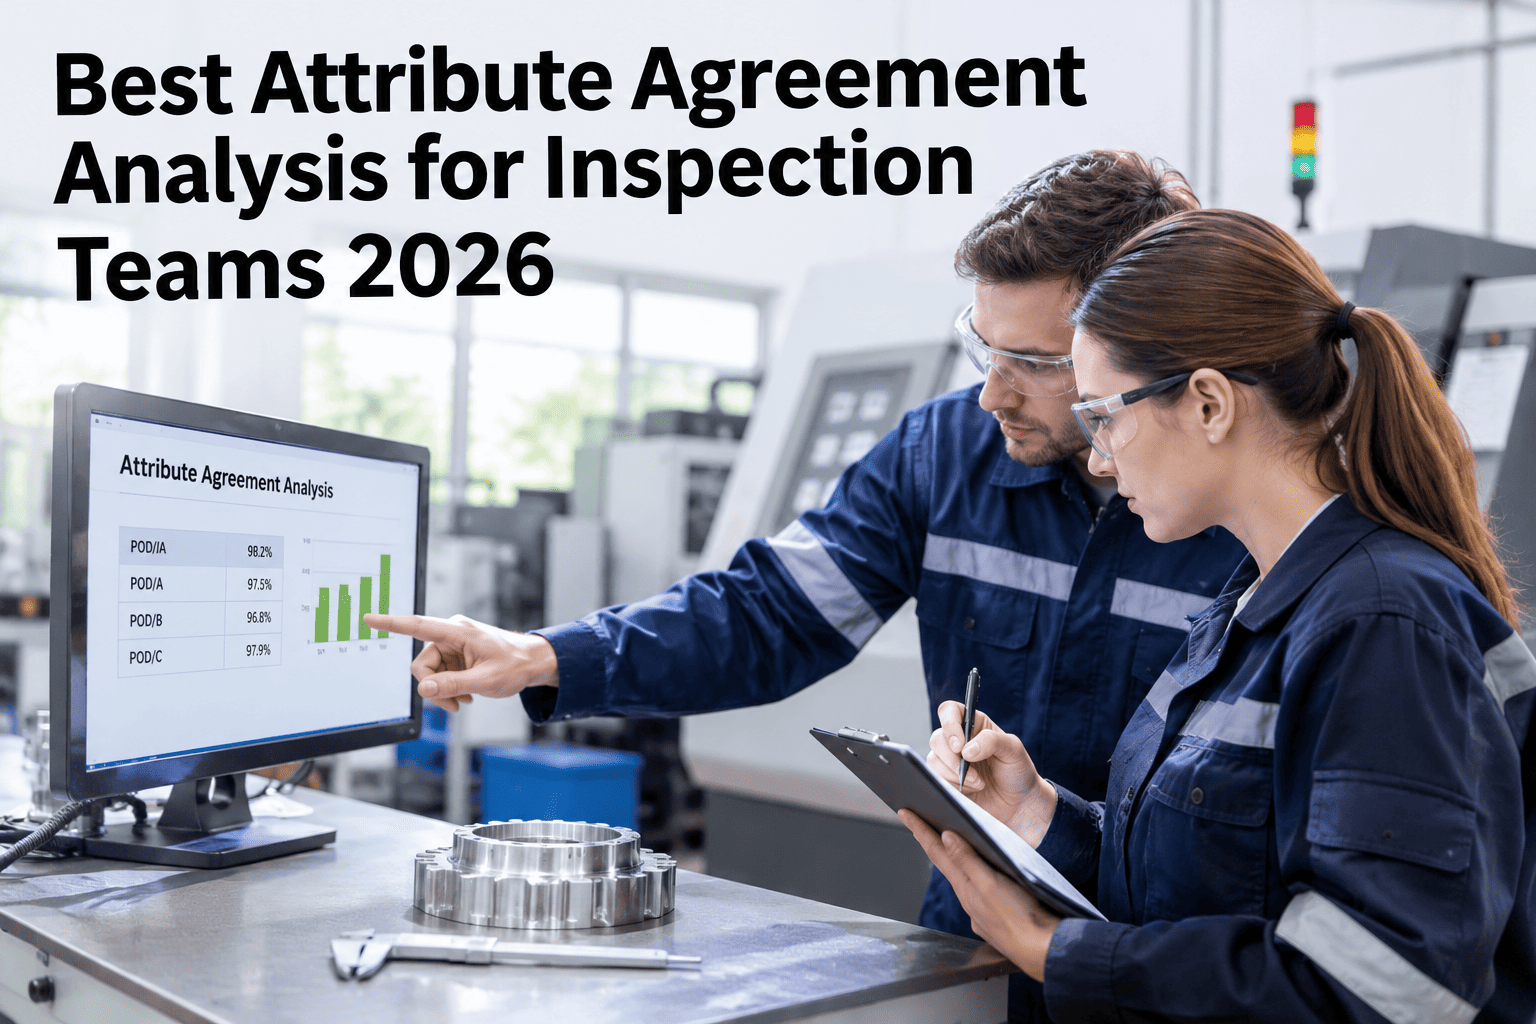
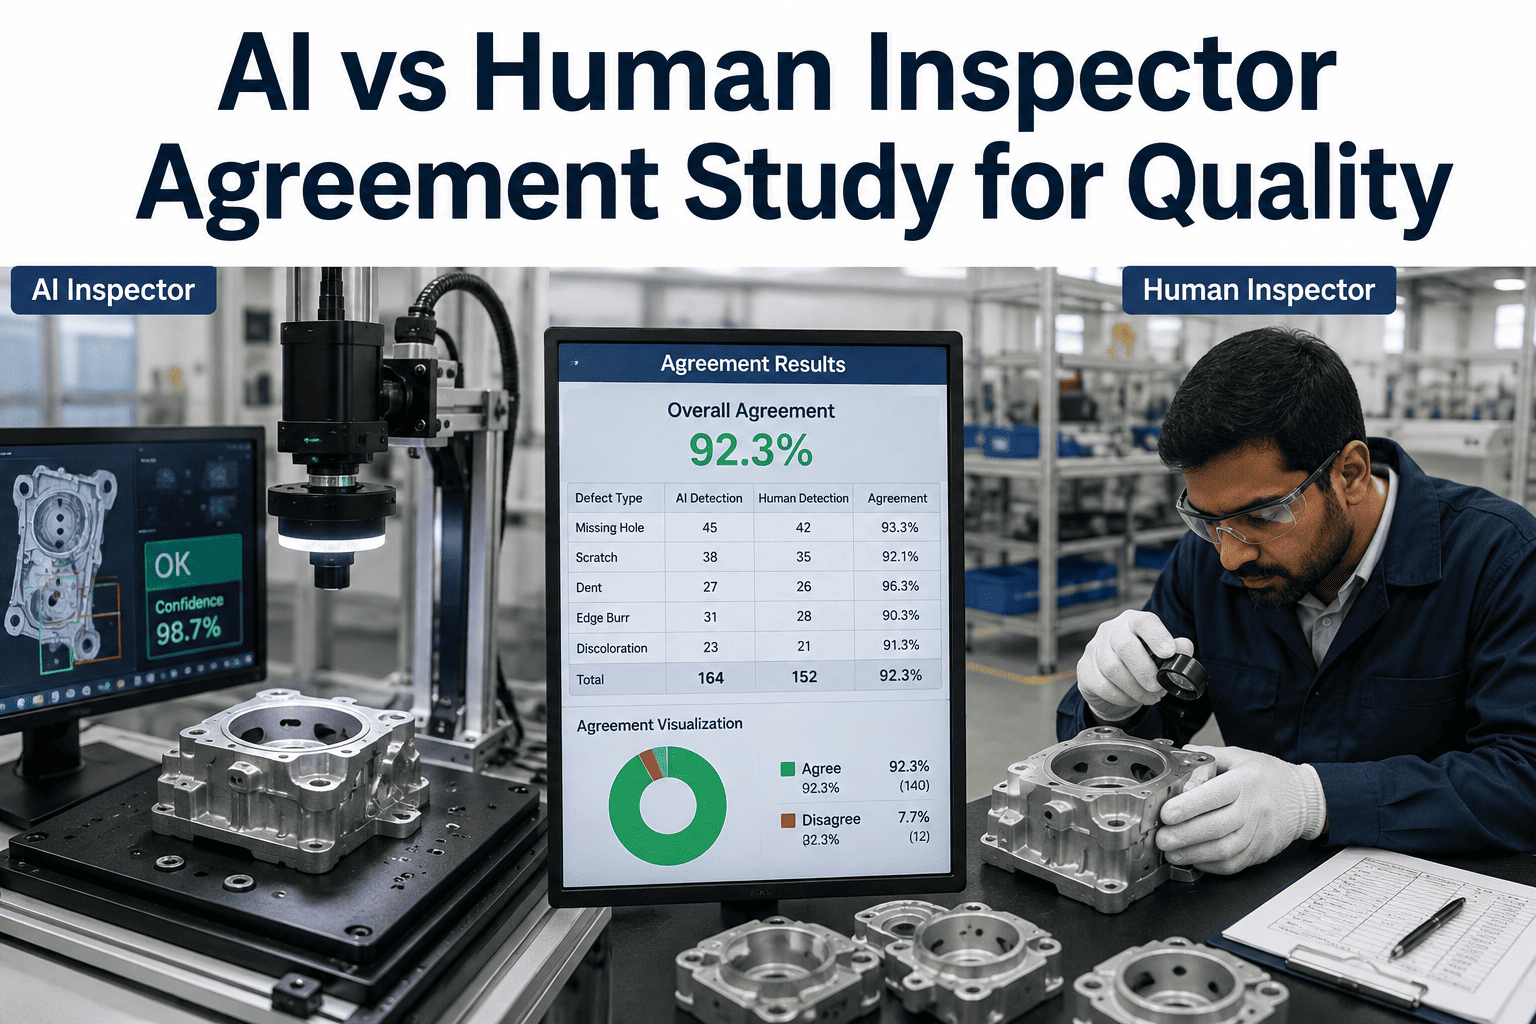
Two inspectors disagreeing on whether the same part is a pass or a fail is a data problem, not a personality problem, and treating it as the latter is how plants end up with a visual standard nobody can actually explain. Attribute agreement analysis quantifies that disagreement with a Kappa statistic and sets a usable target for how consistent pass/fail, go/no-go, or defect-category calls need to be before the inspection itself can be trusted. This is the parallel track within Measurement System Analysis built specifically for visual and attribute checks, where the standard variable Gage R&R math does not apply. You can review an attribute study against your own inspection data with our team.
Attribute Inspection, 2026
When Two Inspectors See the Same Part Differently
iFactory, an on-premise AI platform for quality control and inspection management, guides attribute agreement studies, calculates Kappa automatically and keeps every result traceable for audit.
Kappa ≥ 0.75 — Excellent agreement
Kappa 0.40–0.75 — Fair to good
Kappa < 0.40 — Poor, needs retraining
What it is
What Is Attribute Agreement Analysis?
Attribute agreement analysis measures how consistently inspectors classify the same parts — pass/fail, go/no-go, or defect category — against each other, against themselves on a repeat pass, and against a known reference standard where one exists.
Unlike variable Gage R&R, which measures numeric readings, attribute studies deal with judgment calls. The statistic that quantifies agreement here is Kappa, which corrects for the agreement that would happen by chance alone, not just raw percent agreement.
Three kinds of agreement
What an Attribute Study Actually Checks
Repeatability
Does the same inspector call the same part the same way on a second, blind pass?
Reproducibility
Do different inspectors agree with each other on the same set of parts?
Accuracy
Do inspector calls match a known reference standard, where one has been established?
Running the study
Five Steps to a Study You Can Defend
1
Select 30–50 parts covering clear passes, clear fails, and borderline cases near the decision boundary.
2
Have each inspector classify every part, with identifying marks hidden so they cannot tell which is which.
3
Repeat the full set in randomized order so each inspector also rates each part a second time, blind to their first call.
4
Compare against a known reference standard if one exists, not just inspector-to-inspector.
5
Calculate Kappa for repeatability, reproducibility and accuracy, and document the result against your target.
When it breaks down
Why Inspectors Disagree Even With the Same Training
Low Kappa scores rarely trace back to one inspector being careless. More often the visual standard itself is ambiguous — a borderline scratch depth, a color variation near the edge of acceptable — and different inspectors have quietly developed their own private threshold for it.
The fix is rarely more training on the existing standard. It is usually a clearer reference image or boundary sample for the specific borderline case the study exposed, since that is the part of the standard inspectors were actually guessing on.
Expert review
What a Quality Manager Would Check First
Holds up
Kappa-based attribute agreement analysis is a recognized, audit-accepted MSA approach for visual inspection under the AIAG framework.
Watch for
A study that only samples easy, obvious parts — Kappa looks artificially high when the sample skips the borderline cases where disagreement actually lives.
Do next
Run the study on the defect category with the highest customer complaint rate first, since that is where a hidden agreement gap costs the most.
FAQ
What Inspection Teams Ask About Attribute Agreement Analysis
What Kappa score counts as acceptable agreement?
A Kappa of 0.75 or higher generally indicates excellent agreement, 0.40 to 0.75 is fair to good and may warrant improvement, and below 0.40 signals the inspection cannot yet be trusted for pass/fail decisions.
Check your current Kappa with our team.
How many parts does an attribute study need?
Most studies use 30 to 50 parts, deliberately including borderline cases near the decision boundary rather than only clear passes and fails, since borderline parts are where disagreement actually surfaces.
Ask about sample selection for your defect types.
Why not just measure raw percent agreement instead of Kappa?
Raw percent agreement does not account for the agreement that would happen purely by chance, especially when most parts are easy passes. Kappa corrects for that, which is why it is the standard statistic for attribute MSA rather than a simple percentage.
What should be done when Kappa comes back low?
Look first at the specific parts where inspectors disagreed, since the pattern usually points to an ambiguous visual standard rather than inconsistent inspectors. Adding a boundary reference sample for that specific case is often more effective than general retraining.
Discuss a corrective approach with our team.
How often should attribute studies be repeated?
Annually at minimum, and after any change to the visual standard, new inspector onboarding, or a rise in customer complaints tied to a specific defect category.
Set a study schedule that fits your inspection team.