Missed Assembly Defect Detection AI for Auto Manufacturing

By James Smith on November 19, 2026

missed-assembly-defect-detection-ai-for-auto-manufacturing

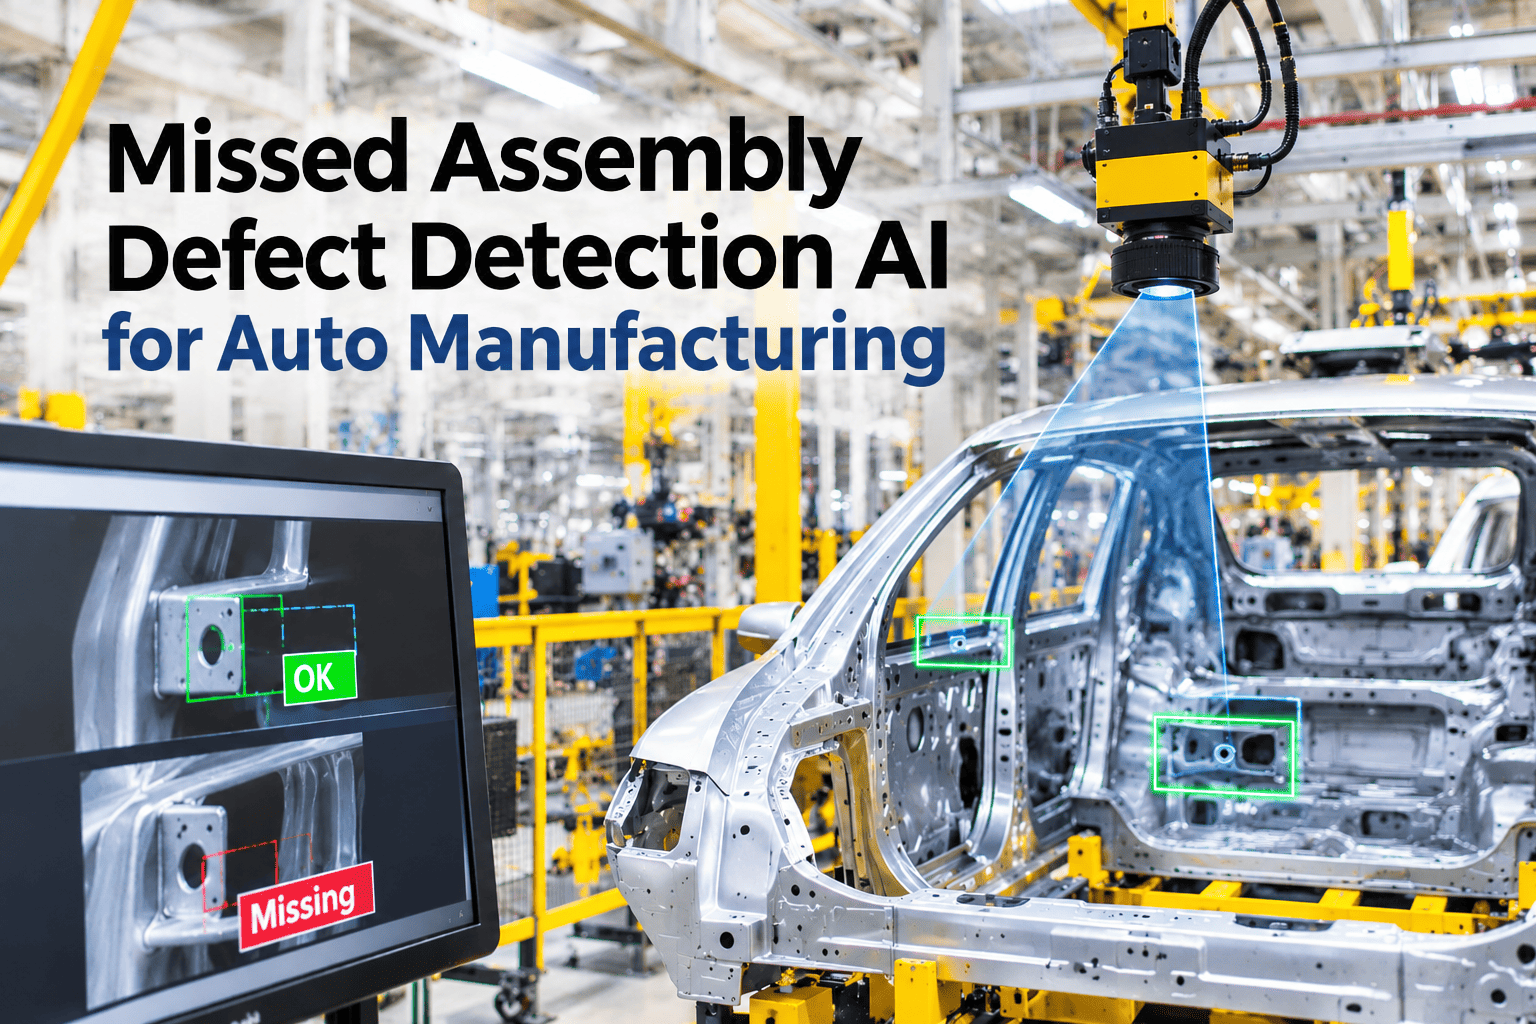
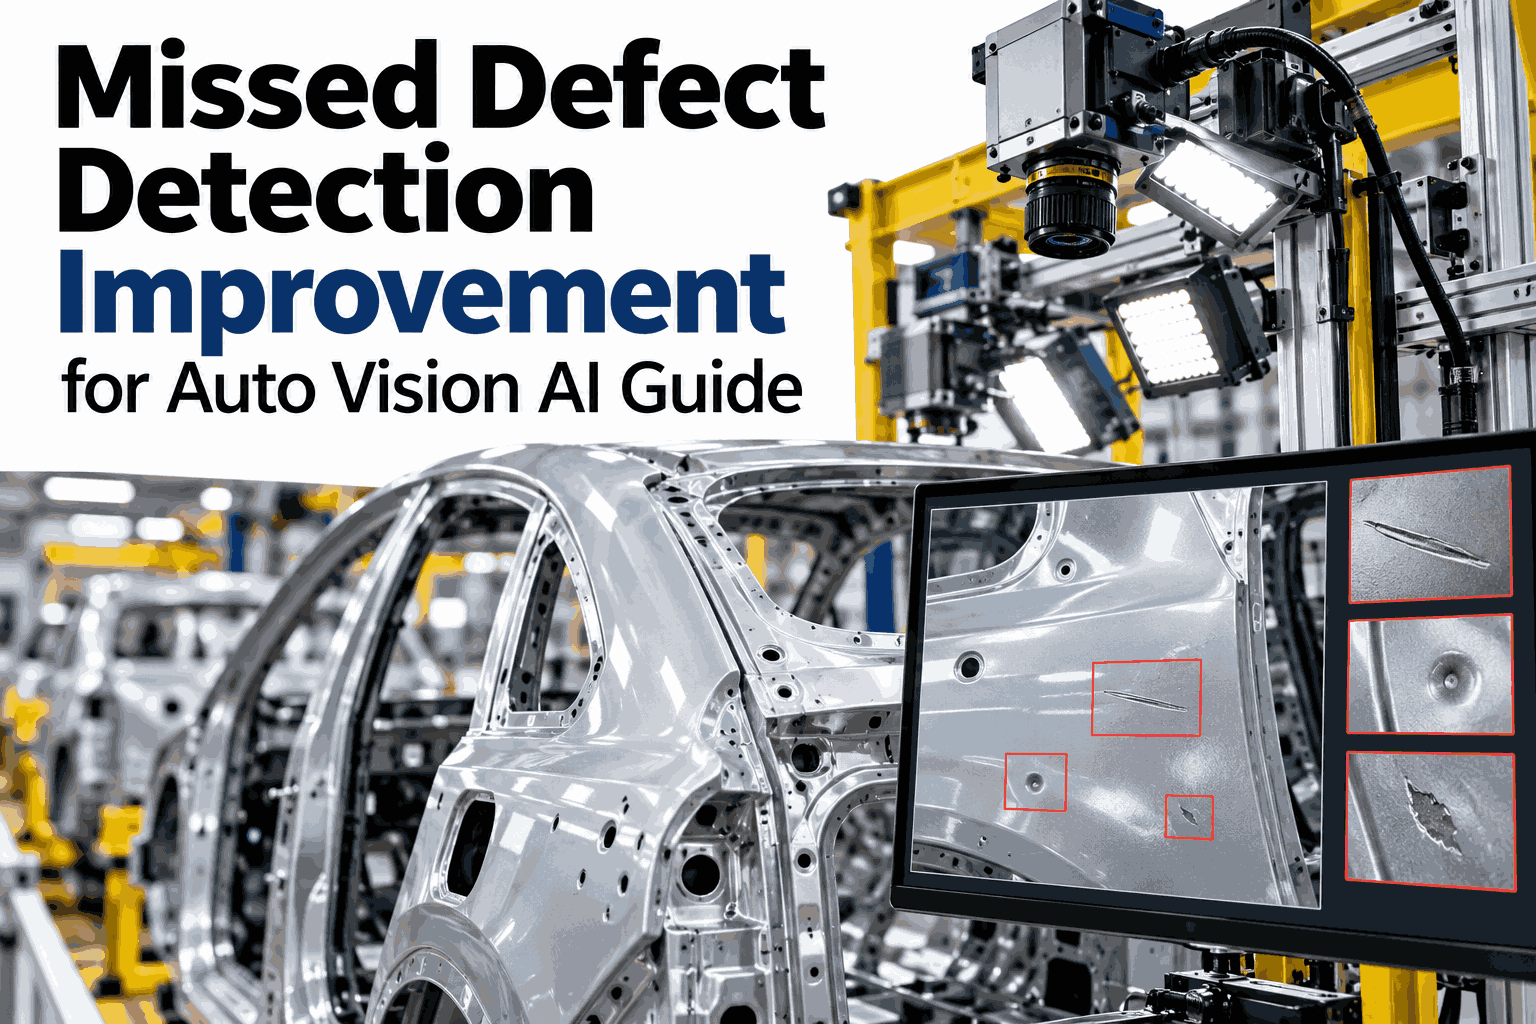
A vision system that reports high accuracy on its own test set can still miss the defects that actually matter in production, because accuracy measured against curated images is not the same as the miss rate against everything that really crosses the line. The defects that slip through tend to share traits — low contrast, partial occlusion, an unusual angle — that make them systematically harder for any model, not randomly unlucky misses. Auto manufacturing quality teams who want their own missed-defect rate measured can run a miss-rate audit against recent production with iFactory AI.

Auto Manufacturing · Missed Defect Detection

The Defects Your Vision System Misses Are Not Random — They're a Pattern

iFactory AI tunes models for higher recall on your hardest defect categories, builds a difficult-defect catalog from real misses, and closes the loop with a human-in-the-loop labeling cycle.

Precision Versus Recall: Why This Distinction Matters Here

A model can report excellent precision — almost everything it flags really is a defect — while still missing a meaningful share of actual defects it never flagged at all. Precision and recall answer two different questions, and a missed-defect problem is almost always a recall problem, not a precision one.

Correctly flagged
A real defect that the model catches — the headline number most dashboards show.
Missed defect
A real defect the model never flags — the number precision alone hides completely.
False alarm
A good part flagged as defective — annoying, but visible and self-correcting.
Correctly passed
A good part the model correctly lets through — the quiet majority of cases.
The missed-defect quadrant is the one that never shows up on a standard accuracy dashboard, because nothing flags that it happened until a complaint surfaces later.

Four Defect Types That Consistently Escape Detection

Low-contrast marks
Discoloration close to the surface tone, easy for a model to blend past.
Seam and edge defects
Flaws right at a panel seam, where confidence is naturally lower.
Rare defect types
Seen only a handful of times in training, with little pattern to learn from.
Occluded defects
Partly hidden by a fixture, part orientation or another component.

Find Out What Your Own Model Is Actually Missing

Run a sample audit against recent production to see your model's real recall, not just its reported accuracy.

Building a Difficult-Defect Catalog That Actually Improves Recall

1
Sample passed parts
Pull a statistically sound sample of units the model already passed.
2
Re-check with a second method
A trained inspector or higher-resolution camera confirms true misses.
3
Catalog by difficulty
Group confirmed misses by the trait that made them hard — contrast, occlusion, rarity.
4
Retrain on the catalog
Feed labeled misses back into training, weighted toward the hardest categories.

Why Human-in-the-Loop Review Still Matters

Raising recall by lowering a model's confidence threshold catches more real defects, but it also raises the false-alarm rate, which is why a human reviewer in the loop for borderline cases matters more as recall improves, not less. The goal is not to automate judgment away entirely — it is to make sure the model's attention goes to the cases that genuinely need a second look.

A Composite Scenario: The Accuracy Number That Hid a Real Gap

A plant's vision system reported accuracy in the high nineties for months, and leadership treated the quality program as mature. An outbound sampling audit against parts the system had already passed found a confirmed miss rate for one specific low-contrast defect type well above what the dashboard implied, because that defect category was underrepresented in the original training data. Building a difficult-defect catalog specifically for that category and retraining against it closed most of the gap within two labeling cycles — a process iFactory AI's team can help set up against your own vision system's output.

Frequently Asked Questions

How do we measure our true miss rate instead of relying on reported accuracy?
Pull a sample of units the model already passed, inspect that sample with a second method such as a trained reviewer, and calculate confirmed misses against the sample size. Run this audit on your own output in a short session.
Does improving recall always increase false alarms?
Generally yes to some degree, since lowering the confidence threshold to catch more real defects also catches more borderline good parts, which is why a human review step for borderline cases matters as recall improves. Ask support how this tradeoff is managed in practice.
How much data do we need to build a useful difficult-defect catalog?
Even a few dozen confirmed examples of a specific hard-to-catch defect type can meaningfully improve recall for that category once properly labeled and included in retraining. Discuss your current defect volume with our team.
How often should the model be retrained once misses are being labeled?
Most plants settle on a monthly or quarterly retraining cadence once a labeling queue builds up, rather than retraining after every single confirmed miss. Our team can help set a retraining schedule that fits your defect volume.
Can this work alongside our existing vision hardware?
Yes, recall tuning and a difficult-defect catalog typically work with your existing cameras and model pipeline rather than requiring new hardware to start. Review your current vision setup before scoping changes.

Stop Trusting a Number That Only Tells Half the Story

iFactory AI measures your true miss rate, builds a difficult-defect catalog, and improves recall where it actually matters. Book a walkthrough with your own data.
Share This Story, Choose Your Platform!