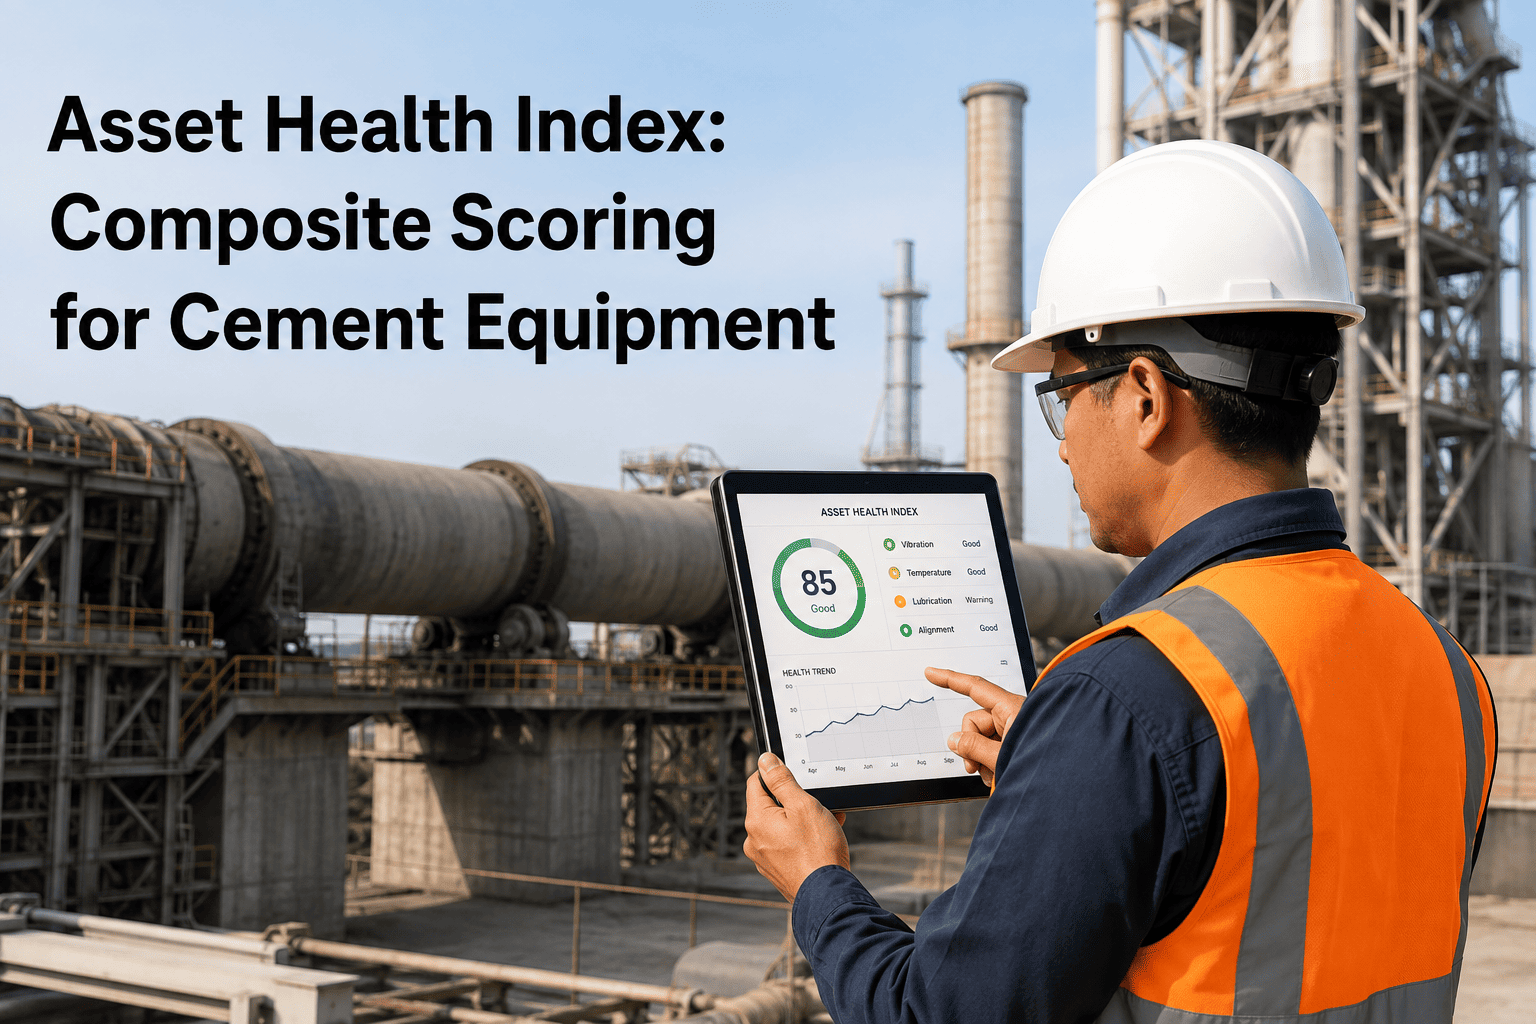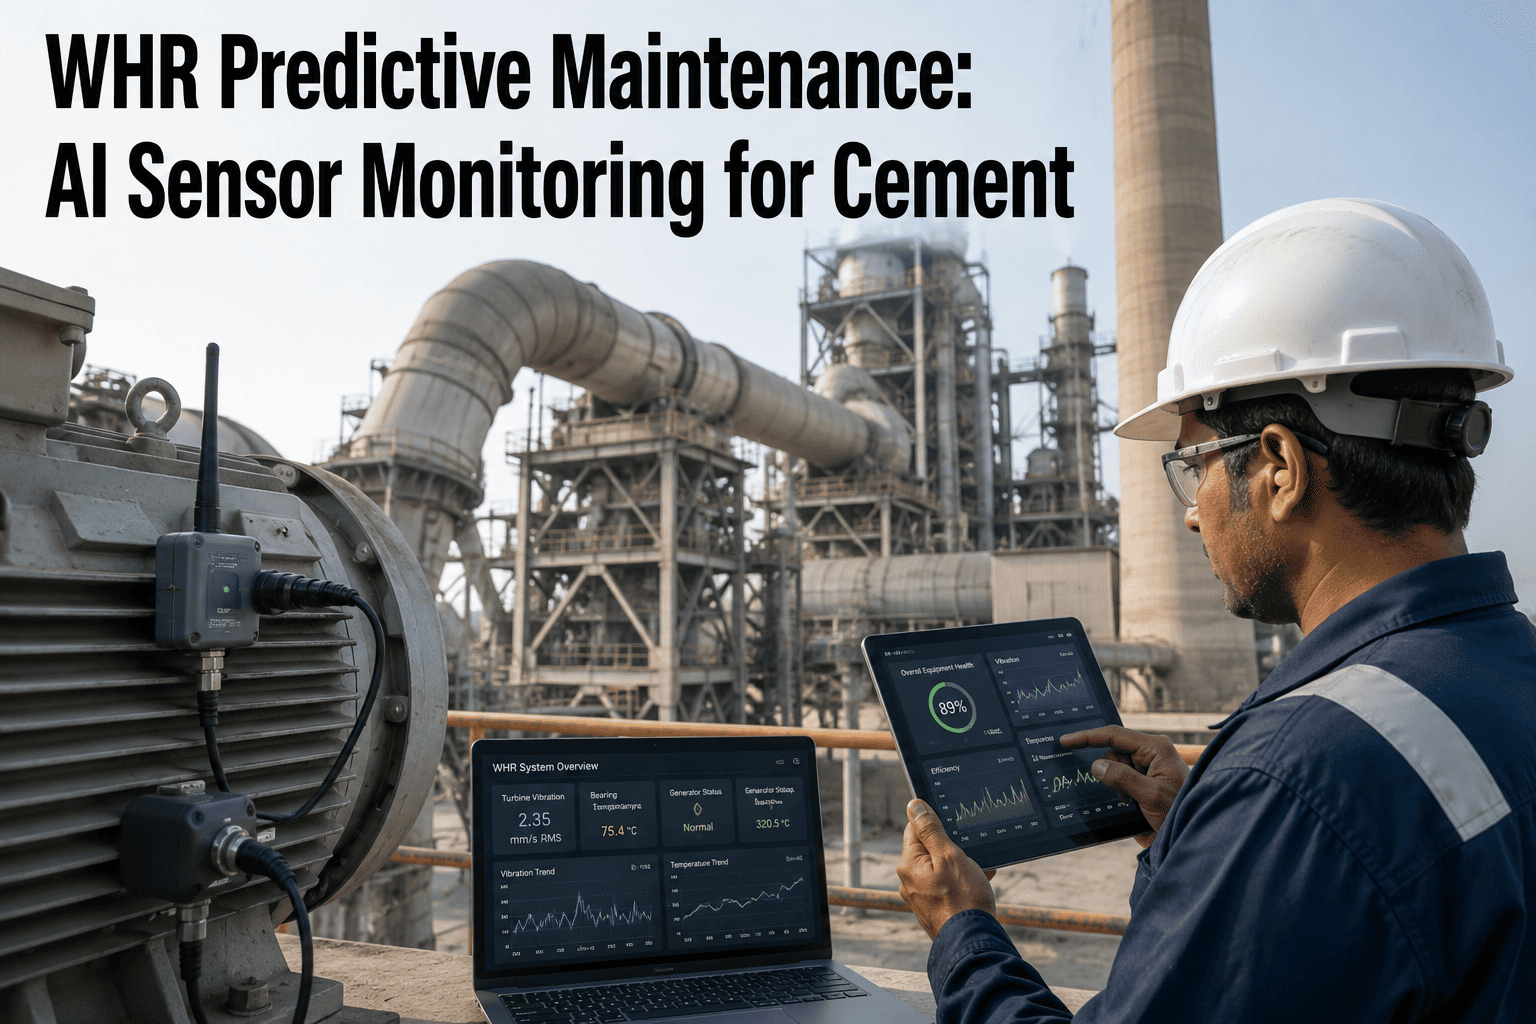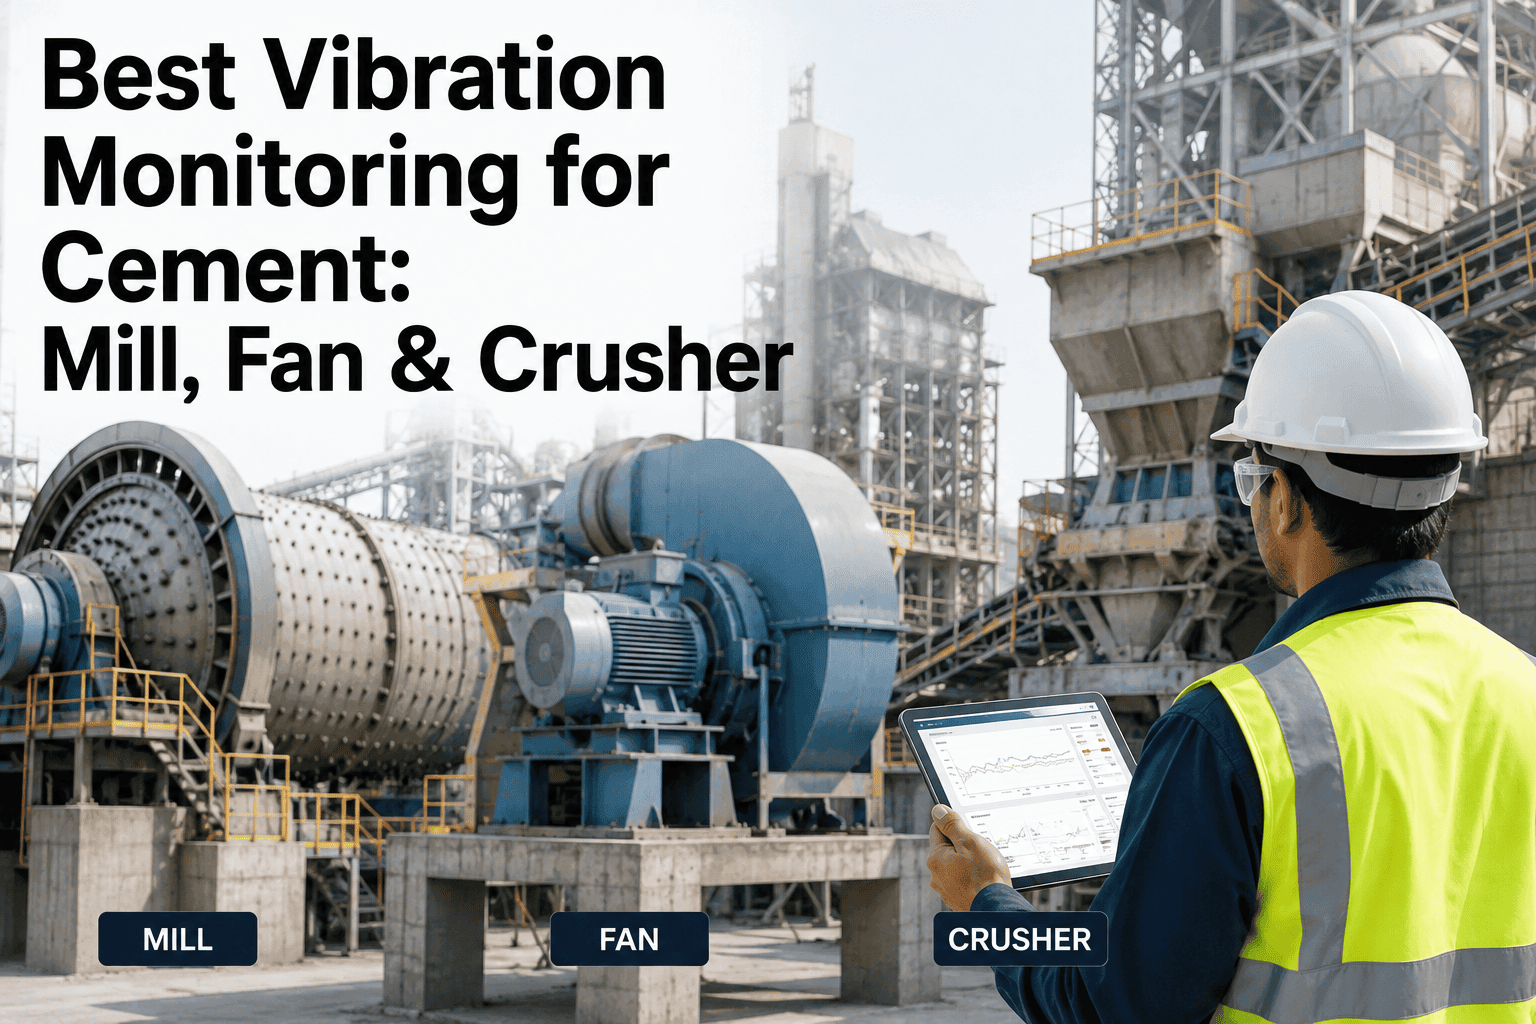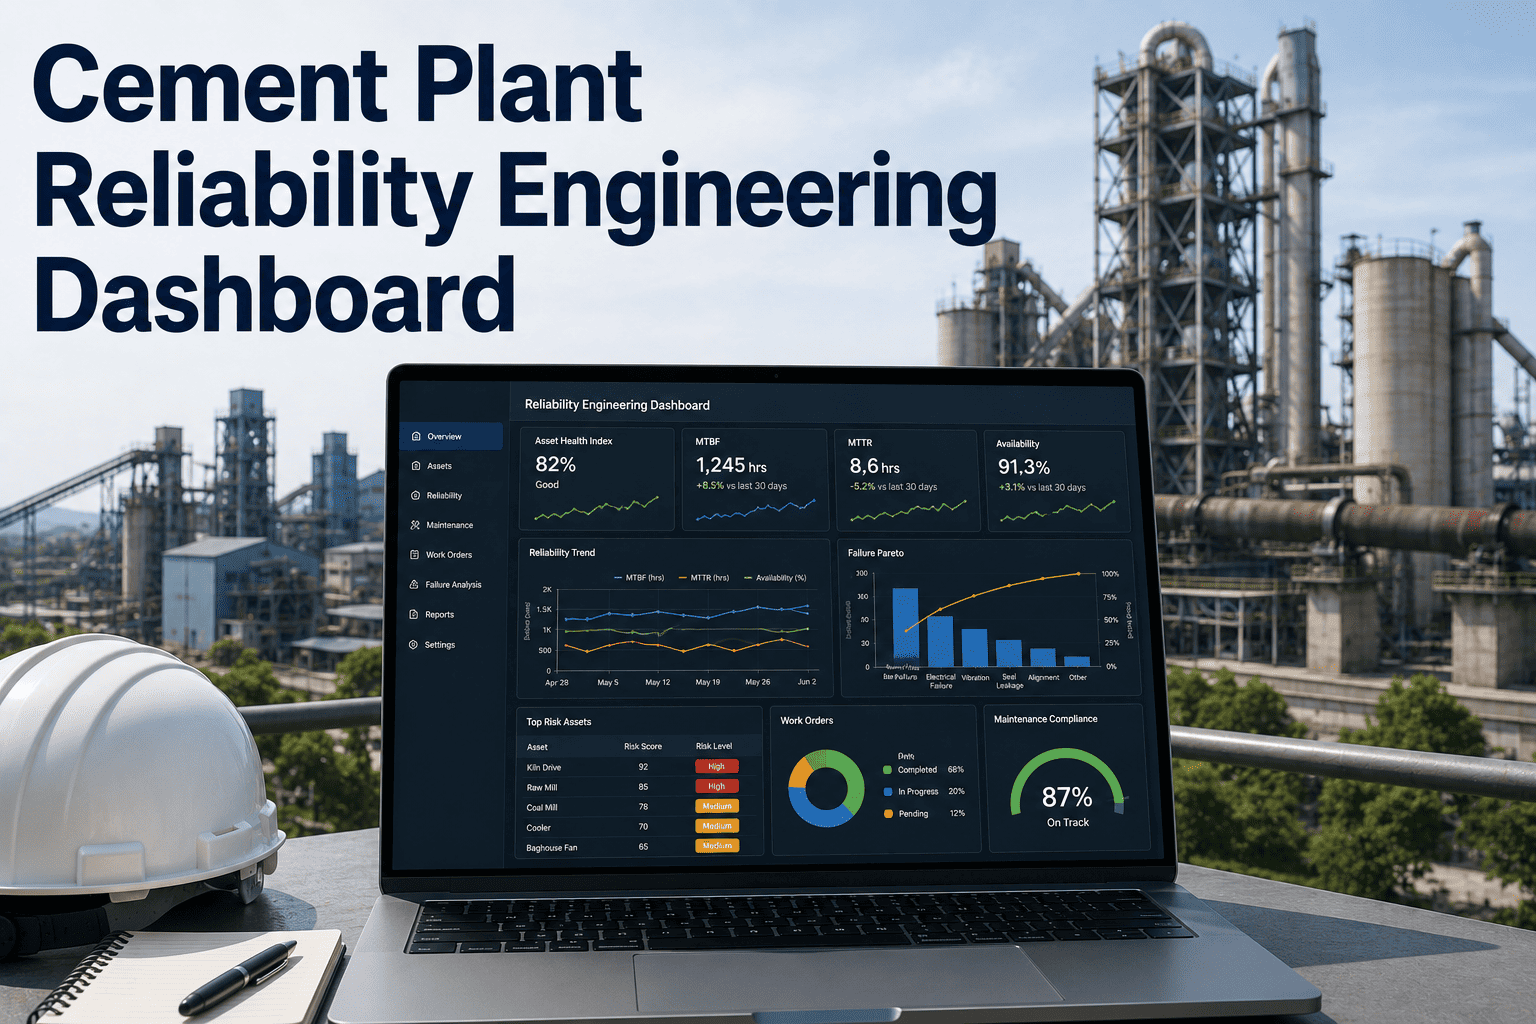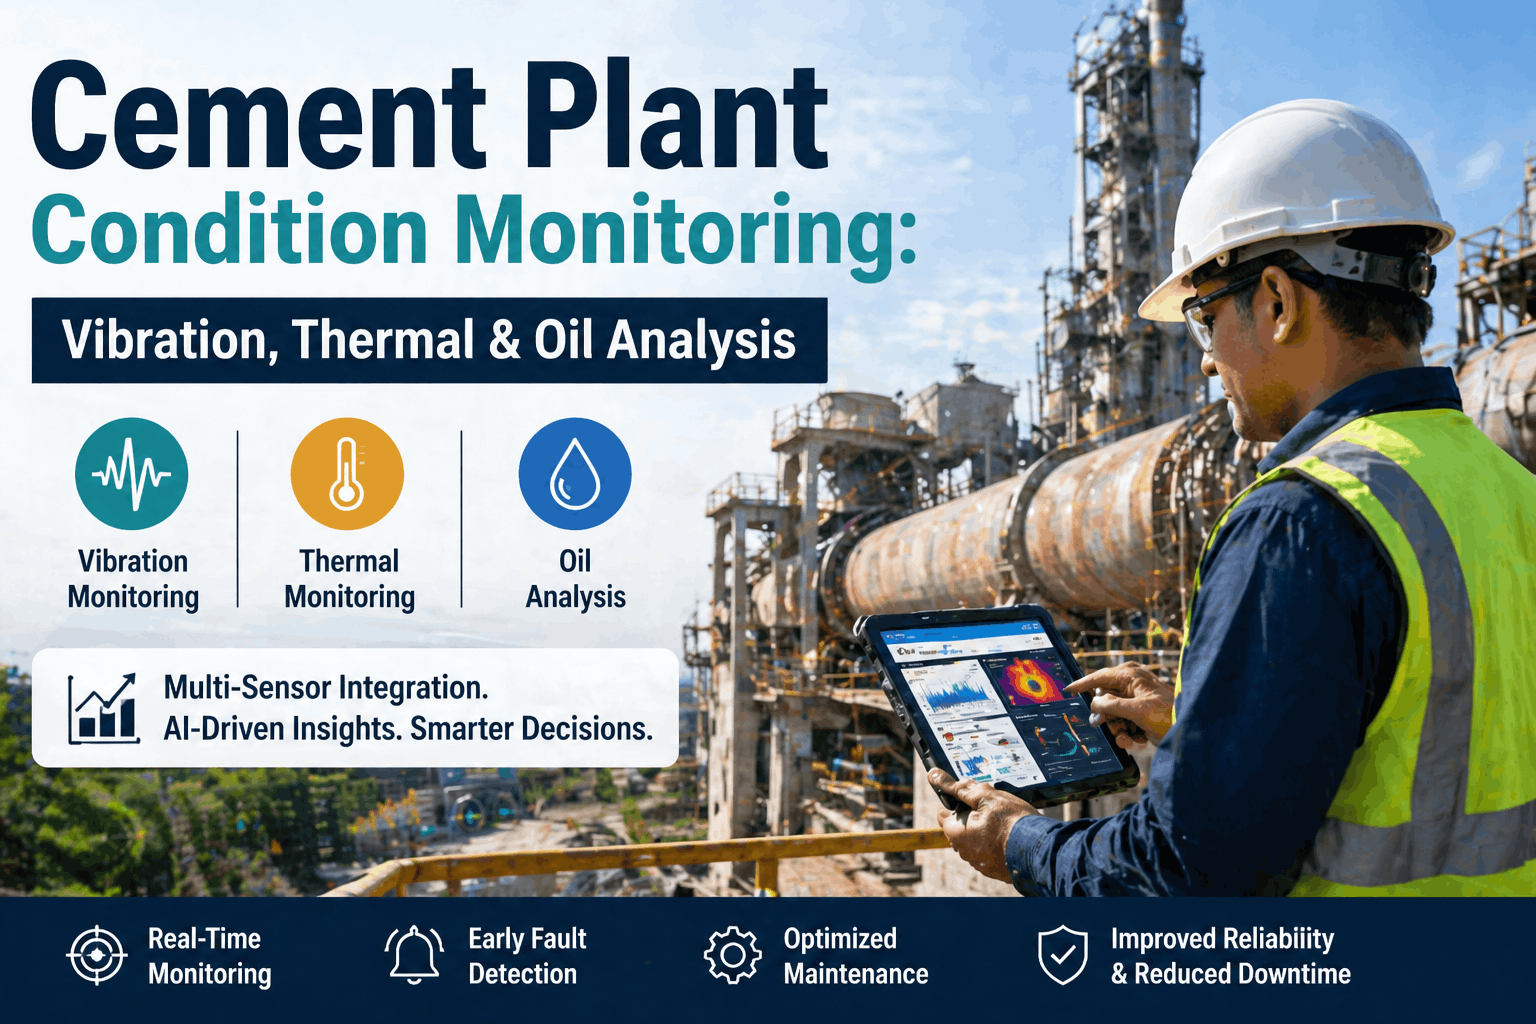
A cement plant runs on a small number of large rotating machines carrying the entire process on their shoulders — the kiln drive and its support rollers, the raw mill and cement mill gearboxes, the ID and preheater fans moving hot, dust-laden gas around the clock, and the roller press pushing material through under enormous load. When any one of these fails unexpectedly, the plant does not slow down gracefully; it stops, often for a full day or more, at a cost that can run into hundreds of thousands of dollars before production resumes. A mechanical reliability program is the structured discipline that keeps a plant from finding out about a failing bearing or a cracking girth gear the same way most plants still do — after it breaks. This piece lays out what that program actually consists of, and how iFactory's reliability team typically helps a plant build it.
Stop Losing Kiln Days to Failures You Could Have Seen Coming
Why Cement Rotating Equipment Fails Differently Than Most Industrial Assets
Cement equipment operates under conditions that are genuinely harsher than most other heavy industries. Kiln shells run near 350 degrees Celsius at the surface. Preheater fan bearings sit in housings routinely exposed to 90 to 120 degree gas temperatures loaded with abrasive dust. Ball mill and vertical roller mill drives absorb heavy shock loading with every rotation as grinding media impacts inside the mill. None of this is a design flaw — it is simply the nature of turning limestone into clinker at extreme temperature, twenty-four hours a day, for months at a stretch between planned stops. What it means for a reliability program is that failure modes develop faster and with less warning than they would on a lighter-duty asset, and a maintenance strategy built for a typical manufacturing plant will not hold up unchanged against a kiln circuit.
The other distinguishing factor is how concentrated the downtime risk is. A typical dry-process plant runs several hundred rotating assets, but the overwhelming majority of unplanned downtime hours trace back to a small handful of them — the kiln drive and support rollers, the raw and cement mill circuits, and the ID and preheater fan trains. A reliability program that spreads equal attention across every asset on the plant, rather than concentrating monitoring and analysis where the downtime risk actually concentrates, ends up under-protecting the assets that matter most while over-servicing the ones that do not.
Reactive Maintenance vs a Structured Reliability Program
| Aspect | Reactive Maintenance Model | Structured Reliability Program |
|---|---|---|
| Trigger for repair | Equipment has already failed or is failing visibly | Condition data trending toward a defined failure signature |
| Asset prioritization | Whichever machine is currently down gets attention | Criticality tier drives monitoring frequency and response time |
| Repair cost | Emergency labor, expedited parts, secondary damage | Planned parts staging, scheduled into existing outage windows |
| Failure history | Rediscovered from memory each time a similar failure recurs | Logged failure modes searchable against every recurrence |
| Typical unplanned downtime share | Majority of work orders triggered by failure events | Majority of work orders planned ahead of failure |
The Four Building Blocks of a Working Reliability Program
Want to see how your current asset list would sort into criticality tiers? Send us your equipment list and our team will map it out with you.
What Condition Monitoring Actually Catches on Each Critical Asset
Different assets fail in different ways, and a reliability program earns its value by matching the right monitoring technique to the failure mode that actually threatens each machine, rather than applying the same generic sensor package everywhere. The kiln support rollers and girth gear develop wear patterns that show up clearly in vibration frequency spectra well before they become audible or visible. The preheater and ID fans, running hot and dust-loaded around the clock, are especially prone to impeller unbalance as material builds up unevenly on the blades, which vibration trending on the fan bearings picks up long before the imbalance becomes severe enough to damage the fan housing. Mill gearboxes reveal early wear through metal particles in the lubricating oil well before a vibration signature changes noticeably.
None of these techniques are new — vibration analysis, thermography, and oil analysis have been standard reliability tools for decades. What has changed is how continuously they can now run and how quickly the resulting data turns into an actual work order. A quarterly manual vibration route on a kiln support roller catches a developing defect only if the defect happens to be far enough along at the moment of that particular check. Continuous monitoring with automated trend analysis catches the same defect the moment it starts deviating from the asset's own established baseline, often weeks before a quarterly check would have found it.
Where Reliability Programs Commonly Stall
How a Program Actually Gets Built, Month by Month
Why Vibration Data Alone Rarely Tells the Full Story
Vibration analysis gets most of the attention in reliability discussions because it is genuinely good at catching mechanical defects early, but relying on it as the only monitoring input leaves real gaps that other techniques are better suited to close. A gearbox tooth developing surface fatigue often shows up in oil analysis as elevated wear metal particles well before the vibration signature changes enough to be conclusive. An electrical connection loosening on a motor terminal box produces a thermal signature that vibration monitoring will not detect at all, since the failure mode has nothing to do with mechanical motion. Motor current signature analysis, meanwhile, can reveal rotor bar and coupling issues from the electrical waveform itself, catching problems that neither vibration nor thermal imaging is well positioned to see.
The plants getting the most value from condition monitoring are not the ones running the most sensors, but the ones that have matched each monitoring technique deliberately to the failure modes it is actually good at catching, layered together on the assets where the combined picture matters most. A kiln ID fan, for instance, benefits from vibration trending on the bearings for imbalance and misalignment, thermography on the motor and bearing housings for developing hot spots, and periodic inspection for the dust buildup that drives the imbalance in the first place — three different signals converging on the same asset rather than one technique asked to catch everything on its own.
Turning Condition Data Into a Decision, Not Just a Reading
A vibration trend or an oil analysis report is only useful the moment someone translates it into an actual maintenance decision — repair now, monitor for another cycle, or schedule into the next planned stop. In many plants, that translation step is where the reliability program actually breaks down, not in the data collection itself. A technician or reliability engineer manually reviewing dozens of trend reports each week, deciding case by case what warrants a work order, introduces exactly the kind of inconsistency and delay that a structured program is meant to eliminate.
Automating that translation, so that a reading crossing a defined threshold generates a work order directly in the CMMS rather than waiting for a person to notice it during a periodic review, is what separates a reliability program that consistently acts on its own data from one that collects data and hopes someone gets to it in time. This does not remove the reliability engineer from the loop — it moves their attention from routine trend review toward investigating the specific alerts the system has already flagged and deciding on the right corrective action, which is a better use of that expertise than manually scanning through reports that mostly show nothing unusual.
Getting Leadership Buy-In Behind a Reliability Program
The technical case for a reliability program is usually easy to make to a maintenance team already living with the consequences of reactive work. The harder conversation is often with plant leadership, who need to see the program in terms of run factor, cost avoidance, and capital planning rather than vibration spectra and failure modes. Translating the technical work into a run factor trend line and an avoided-downtime dollar figure, updated as the program matures, tends to be what keeps a reliability initiative funded past its first year rather than quietly losing budget priority once the initial enthusiasm fades.
Starting with a single high-risk asset as a pilot — the kiln ID fan or the clinker cooler drive are common choices given how directly they threaten kiln run factor — and measuring the actual downtime and cost impact over a defined period before expanding plant-wide tends to build the internal case more effectively than attempting a full plant rollout from day one. A clear, measured pilot result gives leadership something concrete to evaluate rather than asking them to commit to a plant-wide program on projected numbers alone.
Spare Parts Strategy Tied to Criticality, Not Guesswork
A reliability program that predicts an emerging bearing defect three weeks in advance still fails to prevent downtime if the correct replacement bearing is not on the shelf when the repair is scheduled. Spare parts stocking is often treated as a separate procurement function disconnected from the reliability program, but the two should be tightly linked — critical Tier A components with long lead times need dedicated stock on hand regardless of carrying cost, while Tier C components on redundant equipment can reasonably be sourced on demand without materially increasing risk. Getting this alignment right means a predicted failure translates into a scheduled repair rather than a scheduled repair that then waits on a part.
This is another area where the criticality ranking done early in a program pays dividends well beyond monitoring frequency. Once every asset carries a defined tier, procurement and reliability engineering can review the spares list together and make deliberate decisions about what genuinely needs safety stock versus what can be handled through a supplier relationship with reasonable lead time, rather than defaulting to stocking everything heavily out of general caution.