An AI pilot that runs forever is not really a pilot, it is a permanent experiment nobody has decided to fund or stop. Without exit criteria agreed before the pilot starts, teams default to extending it indefinitely, unsure whether the model is actually working or whether operators have simply stopped complaining. A scale-up scorecard fixes that by defining, in advance, what baseline, model performance, adoption and reliability have to show before the pilot earns a scale-up decision. Plants ready to build their own exit criteria can book a demo with the iFactory AI team.
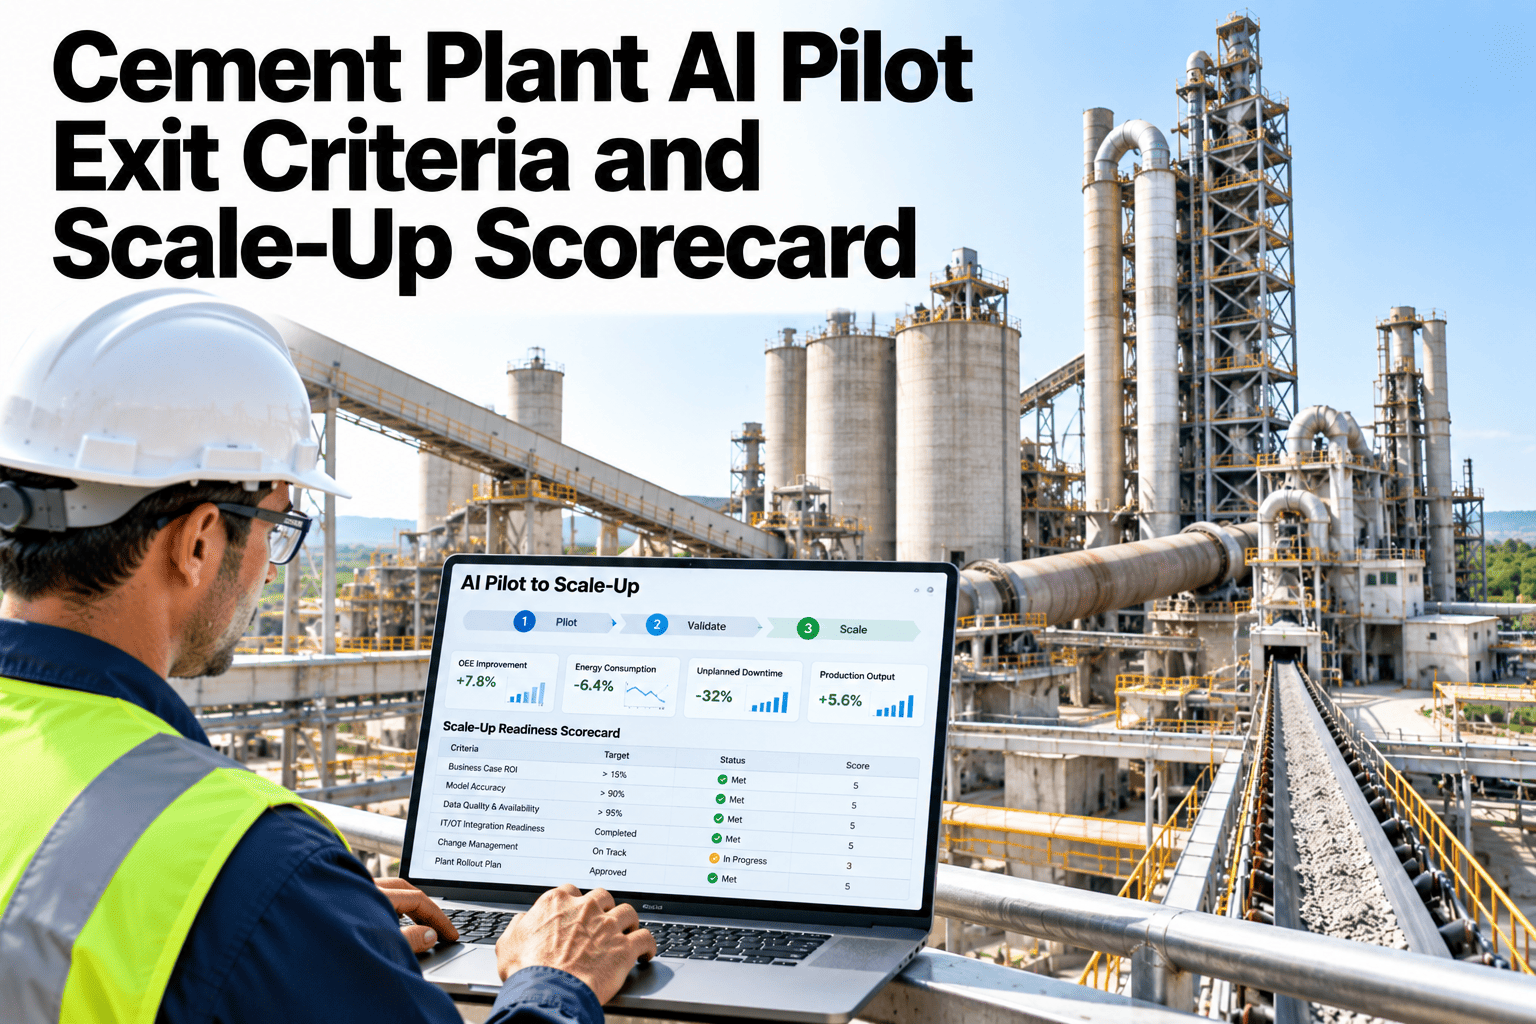
Cement Plant AI Pilot Exit Criteria and Scale-Up Scorecard
Define baseline, model performance, adoption and reliability targets a pilot must hit before it earns a scale-up decision.
Why Pilots Stall Without Exit Criteria
Without a defined finish line, a pilot has no natural end point, so it quietly continues running in parallel with normal operations, consuming attention without ever triggering a real scale-up decision.
Exit criteria agreed up front turn that open-ended state into a clear decision point: scale, adjust, or stop, based on evidence rather than momentum.
Baseline and Target
Every exit criterion needs a measurable baseline from before the pilot, so the pilot's effect can actually be isolated.
| Metric | Baseline Captured | Target to Exit Pilot |
|---|---|---|
| Model performance | Manual or legacy method accuracy | Defined improvement over baseline |
| Operator adoption | Current process compliance rate | Sustained usage above a minimum threshold |
| Reliability | System uptime expectation | Consistent performance across conditions |
| Benefit | Cost, quality or downtime baseline | Measured improvement validated independently |
From Pilot to Scale-Up Decision
The scorecard process runs through a short sequence that turns pilot data into a clear decision.
Give Your Next Pilot a Real Finish Line
Book a 30-minute walkthrough and set exit criteria and a scale-up scorecard for your own AI pilot.
A Sample Scorecard Result, Illustrative
The figures below are invented to show the shape of a scorecard result, not to benchmark your plant.
Common Scorecard Mistakes
The same gaps repeat across plants running their first scored AI pilot.
What a Scored Exit Enables
A pilot that exits with a clear scorecard result makes every conversation afterward easier.
A scale-up request to corporate comes with evidence attached, not just enthusiasm. A pilot that falls short can be adjusted and re-tested with a clear record of what specifically needs to improve, rather than restarting from scratch.
Frequently Asked Questions
How long should a pilot run before exit criteria are evaluated?
Most pilots need at least one full operating cycle, often ninety days or more, to generate enough data for a reliable scorecard result, though the exact length depends on the use case and how much seasonal variation matters. Book a demo to set a pilot length for your use case.
What happens if a pilot partially meets its criteria?
A partial result usually leads to a targeted adjustment and a short re-test period rather than an immediate scale-up or full stop, giving the team a chance to close the specific gap identified.
Who should sign off on the scale-up decision?
Typically plant leadership alongside whoever owns the corporate AI program, since the decision usually involves both operational confidence and budget for a broader rollout. Ask support how scale-up approvals are typically structured.
Can the same scorecard template be reused across different use cases?
Yes, the scorecard structure, baseline, performance, adoption, reliability and benefit, works across most AI use cases, with the specific metrics adjusted to fit each one.
Turn Every AI Pilot Into a Clear Decision
iFactory AI helps you define exit criteria and track every pilot against a real scorecard. Book a walkthrough built around your plant.