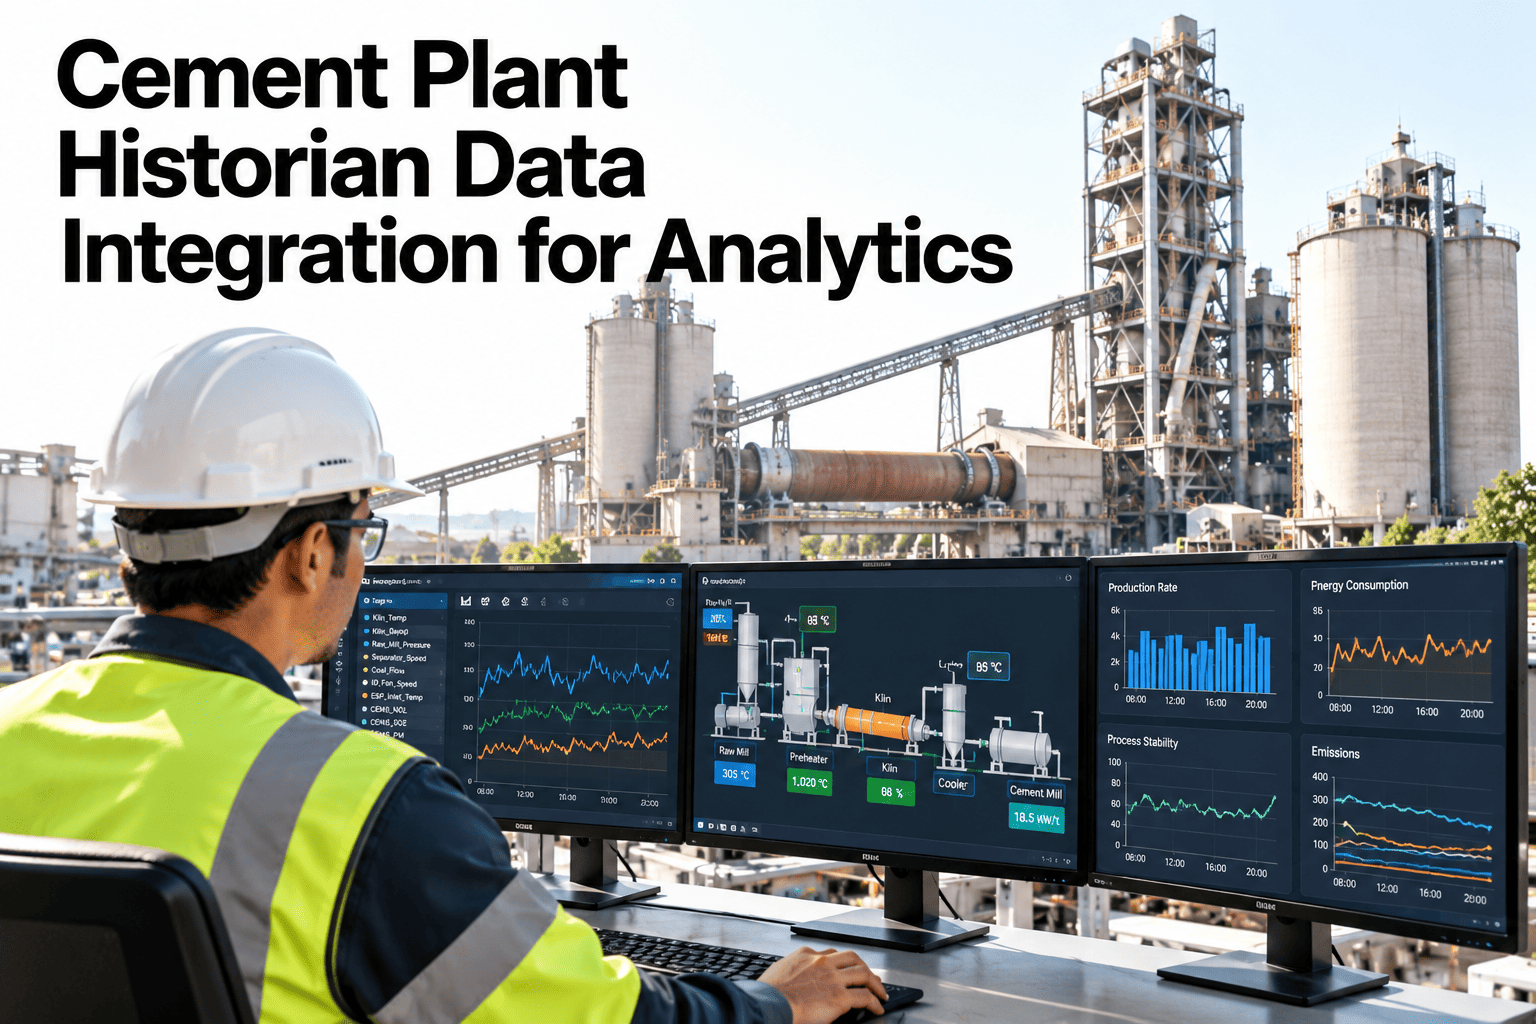
A historian holding years of PI or similar tag data looks like a ready-made analytics foundation, right up until someone tries to actually query it for a specific analysis and discovers half the tags were renamed in 2019, a third have gaps nobody explained, and the sampling rate changes partway through the archive. Historian data integration for analytics starts by treating the historian as a source to be inventoried and validated, not assumed clean. Plant data and reliability teams can run a historian data quality check on iFactory AI before building analytics on top of it.
A Historian Isn't Clean Just Because It's Old
iFactory AI inventories historian sources, checks sampling and gaps, and maps tags to assets before building analytics on top.
Historian Source Inventory: Start Here
PI, Wonderware, or another system, each with its own access methods.
Actual usable history, not just the stated retention policy.
Credentials, network access and any licensing constraints on querying.
A real tag list, not the one from the original commissioning document.
Common Data Quality Issues in a Working Historian
| Issue | What It Looks Like | Why It Matters for Analytics |
|---|---|---|
| Tag renaming | Same physical point, different tag name over time | Breaks a continuous trend without manual reconciliation |
| Sampling rate changes | Interval shifts from, say, 10 seconds to 1 minute | Skews statistics calculated across the full period |
| Data gaps | Missing periods with no clear cause logged | Can be mistaken for a real zero or steady-state value |
| Unit inconsistency | A tag's unit changes without a flag in the record | Silently corrupts any calculation using that value |
Check Your Own Historian Before You Build On It
Bring access to your historian to a 30-minute session and run a data quality pass on your key tags.
Asset Mapping: Connecting a Tag to What It Actually Measures
Pull the raw tag name as it exists in the historian.
Confirm which physical equipment or point it represents.
Document the mapping so it survives staff turnover.
Confirm the value matches what operators actually see.
Raw Historian Access vs Validated Analytics
A Composite Scenario: The Trend That Was Actually Two Different Tags
Picture an energy consumption analysis spanning three years that shows an unexplained step change halfway through. Investigation reveals the historian tag was renamed during a control system upgrade, and the "continuous" trend was actually two different tags stitched together by a querying tool that didn't know they were the same point.
A documented tag inventory, built before the analysis started, would have flagged the rename and let the analyst reconcile it, instead of publishing a conclusion based on an artifact of bad data hygiene.
Where iFactory AI Fits
Inventories the source
Catalogs what's actually in the historian, not the assumed tag list.
Checks sampling and gaps
Flags rate changes and missing periods before they skew an analysis.
Maps tags to assets
Documents the relationship so it survives staff turnover.
Validates before analysis
Confirms data quality once, so every later analysis builds on a clean base.
Expert Review
An industrial data engineering perspective, reviewed for accuracy before publication: historian data has a reputation for being the plant's single source of truth, and in practice it's usually the plant's single largest source of quietly inconsistent data. The inventory and validation step isn't optional overhead, it's the work that makes everything built on top of the historian trustworthy. Running a quality pass on your own key tags before committing to an analysis is time well spent.
Frequently Asked Questions
How do we find out if our historian tags have been renamed over time?
This typically requires reviewing change logs from control system upgrades alongside the historian's own tag history, where available, and cross-checking suspicious trend discontinuities against known project timelines. Not every historian retains a clean rename history, so this can involve some detective work for older systems. See a tag history review for your own historian in a short session.
What should we do about gaps in historian data?
Each gap should be investigated for cause, since a gap could mean a real outage, a network interruption, or a data collection failure, and these mean different things for an analysis. Treating all gaps the same, or worse, treating them as zero values, risks a materially wrong conclusion. Ask for a gap analysis on your own historian's key tags.
Can analytics tools connect directly to a PI historian?
Many analytics platforms support connecting to PI and similar historians through standard interfaces, though the specific connection method, access permissions and licensing considerations depend on your historian's version and configuration. This is worth confirming directly with your automation or IT team. Explore what connection method would work for your specific historian.
How often should tag mapping documentation be reviewed?
Reviewing it whenever equipment changes, a control system is upgraded, or staff turnover affects who holds the institutional knowledge is more reliable than a fixed schedule, since the documentation's value depends on staying current with actual plant changes. Try a review of how current your own tag mapping documentation is.
Does validating historian data mean replacing the historian itself?
No, validation is typically a layer built on top of the existing historian, confirming and documenting what's already there rather than requiring a system replacement. The historian stays the system of record; what changes is how reliably its data gets used downstream. Join a session on building a validation layer for your existing historian.
Build Analytics on a Historian You've Actually Checked
iFactory AI inventories, validates and maps your historian data before analytics gets built on top of it. Discuss your plant data with our team.