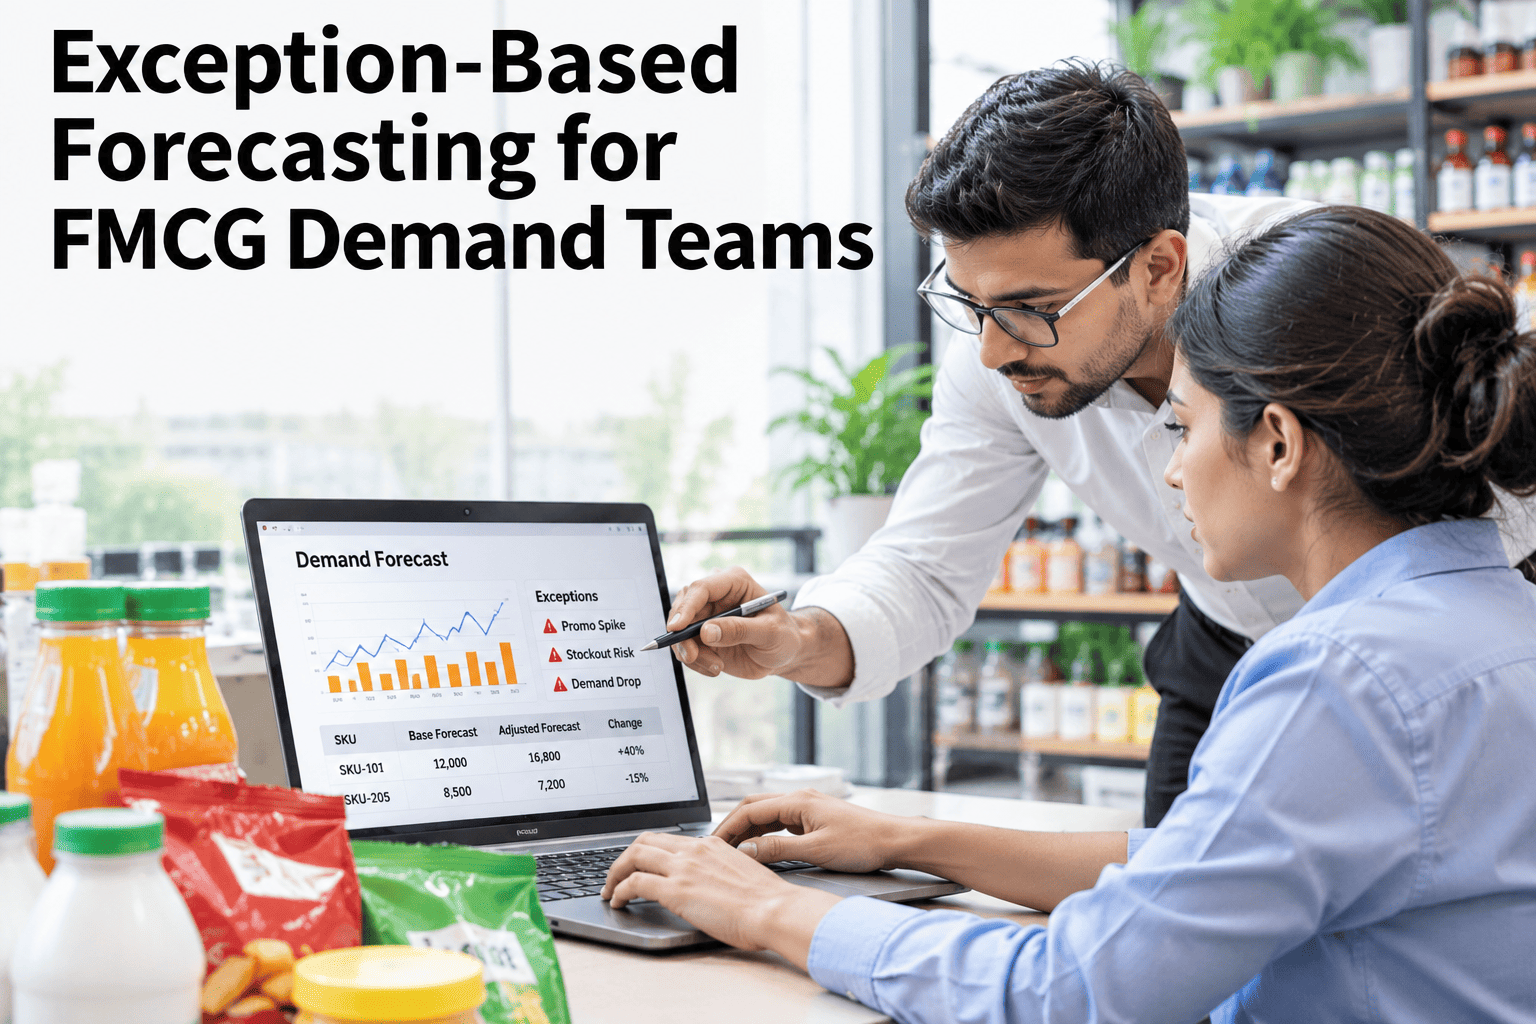
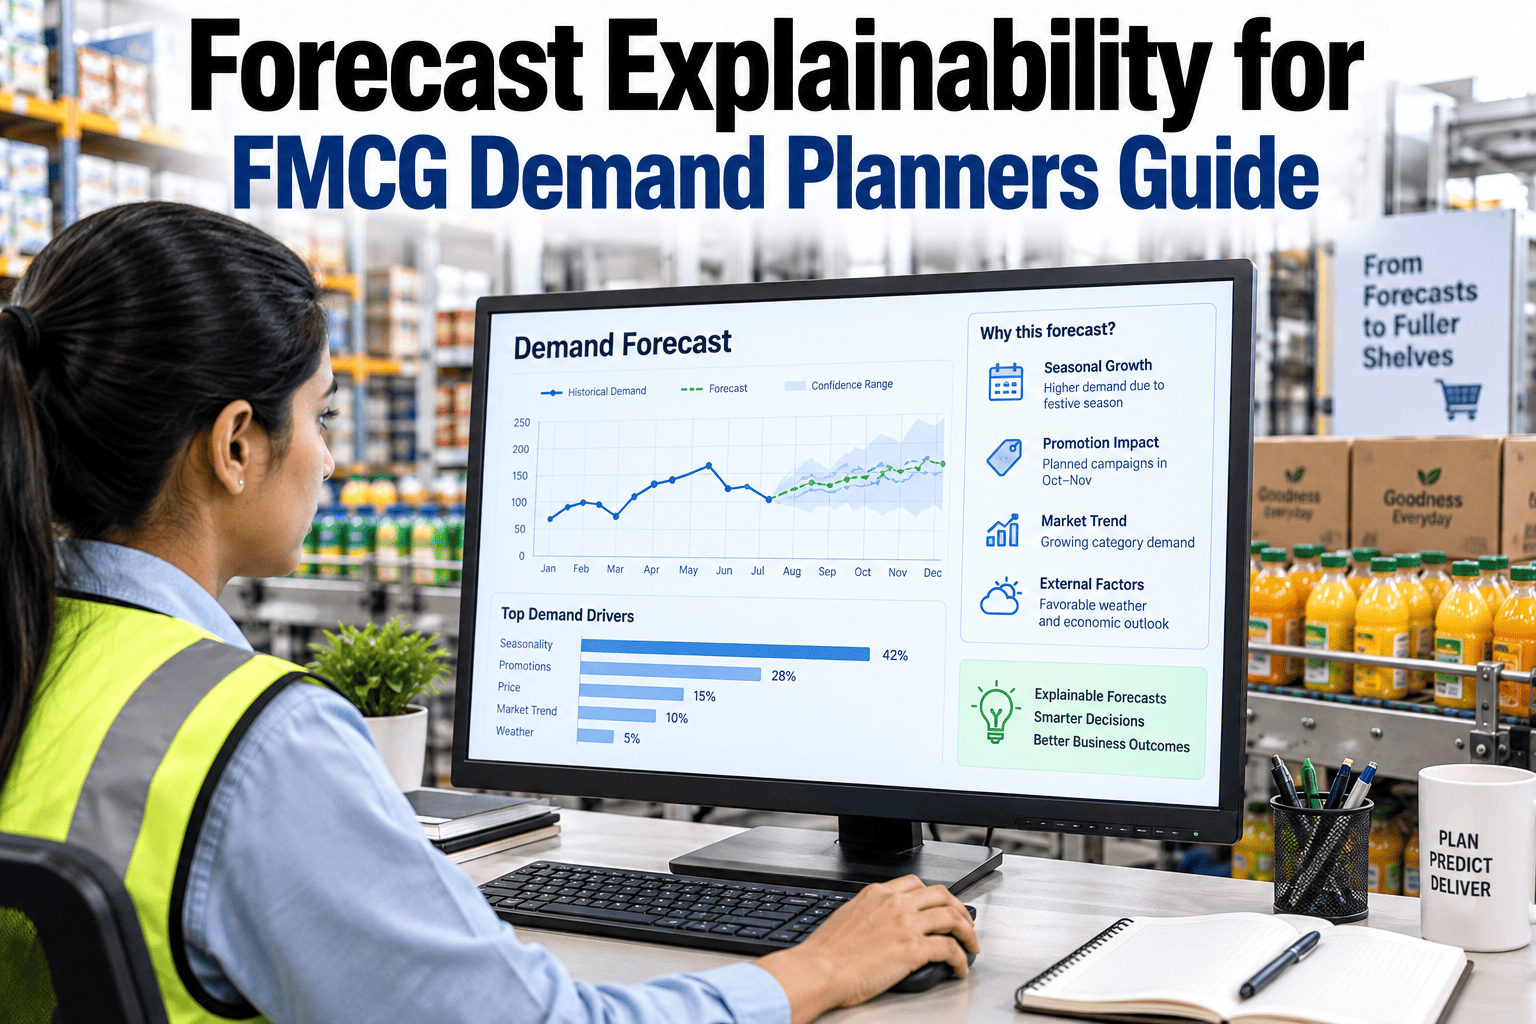
A demand planner reviewing every SKU every week spends most of that time confirming forecasts that were already going to be right. Exception-based forecasting flips the model: stable SKUs auto-approve against their statistical or ML forecast, and planner attention routes only to SKUs that are high-variance, high-value, or carrying high recent forecast error. The planner's calendar stops being a review queue and becomes a triage list. You can see which of your SKUs would auto-approve today on a short call with our team.
FMCG Demand Planning, 2026
Stop Reviewing Forecasts That Were Never Going to Be Wrong
iFactory Adaptive Forecasting auto-approves stable SKUs against their forecast and surfaces only the exceptions — high-variance, high-value, high-error — so planner time goes where it actually changes the outcome.
All SKUs
Auto-Approved (majority)
Exceptions Needing Review
What it is
What Is Exception-Based Forecasting?
Exception-based forecasting sets rules for which SKUs need a human planner's eyes before the forecast goes into the production and replenishment plan, and which can proceed automatically because the statistical or ML model has consistently been close to right.
The rules usually combine three factors: how volatile the SKU's demand has historically been, how much revenue or margin is at stake if the forecast is wrong, and how far recent forecasts have actually missed. A SKU that is low on all three auto-approves; a SKU that is high on any one gets flagged.
Three triggers
What Actually Flags a SKU as an Exception
High variance
Demand history swings widely, so a small forecast miss is more likely and more costly.
High value
A high-revenue or high-margin SKU where even a modest error moves real money.
High recent error
The forecast has missed by more than a set threshold in the last few cycles.
How it works
Four Steps to Setting Up Exception Rules
1
Score every SKU on volatility, value and recent forecast error using your historical data.
2
Set thresholds for each factor — where "high" starts — calibrated to your own planner capacity.
3
Auto-approve any SKU scoring low across all three, routing it straight into the plan.
4
Route flagged SKUs to a planner queue, ranked by how much is at stake, not just alphabetically.
Comparison
Review Everything vs Exception-Based Review
| Dimension | Review Everything | Exception-Based |
|---|
| Planner time per cycle | Spread evenly across every SKU | Concentrated on the SKUs that need it |
| Stable SKUs | Reviewed anyway, little added value | Auto-approved, freeing planner time |
| High-risk SKUs | Get the same attention as everything else | Get prioritized, ranked attention |
| Planner fatigue | High — same routine every cycle | Lower — attention matches actual risk |
Getting it right
What Makes Exception Rules Trustworthy
A planner who stops trusting the auto-approval rule will quietly start reviewing everything again anyway, which defeats the entire point. Trust is built by starting conservative and tightening gradually, not by setting aggressive thresholds on day one.
Track a confidence metric alongside the exception rate — how often an auto-approved SKU later needed a correction — and share it with planners regularly. A visibly low correction rate is what earns the team's trust in the system over time.
Expert review
What a Demand Planning Manager Would Check First
Holds up
Exception-based review is standard practice in mature demand planning organizations; FMCG's SKU count just makes the payoff larger than in smaller portfolios.
Watch for
Thresholds set once and never revisited — a SKU's volatility profile changes, and a rule calibrated a year ago may be auto-approving something it should not.
Do next
Start with conservative thresholds on your highest-value tier, and widen auto-approval gradually as the correction-rate data earns confidence.
FAQ
What Demand Teams Ask About Exception-Based Forecasting
What percentage of SKUs typically auto-approve in a mature setup?
This varies by portfolio, but most FMCG demand teams find a majority of SKUs — the stable, low-value, low-error ones — can safely auto-approve once rules are calibrated, leaving planner time for the smaller set that actually needs judgment.
Check your own split with our team.
How do we set the right threshold for "high variance" or "high value"?
Start with your historical data — look at the distribution of volatility and value across your SKU portfolio and set thresholds relative to your own distribution, not a generic industry benchmark.
Ask about threshold calibration for your portfolio.
What happens if an auto-approved SKU's forecast turns out wrong?
That miss should feed back into the correction-rate tracking that evaluates the rule's trustworthiness, and a pattern of misses in a specific SKU or category is a signal to tighten that SKU's thresholds, not evidence the whole system has failed.
Does exception-based forecasting work with both statistical and ML methods?
Yes — the exception logic sits above the forecasting method itself, so it applies whether the underlying forecast for a given SKU comes from a statistical model, an ML model, or a hybrid.
See how the two layers connect with our team.
How often should exception rules be reviewed?
Quarterly is a reasonable starting cadence, with an earlier check if the correction-rate metric for auto-approved SKUs starts climbing, since that is the clearest signal a threshold needs tightening.
Discuss a review schedule for your team.