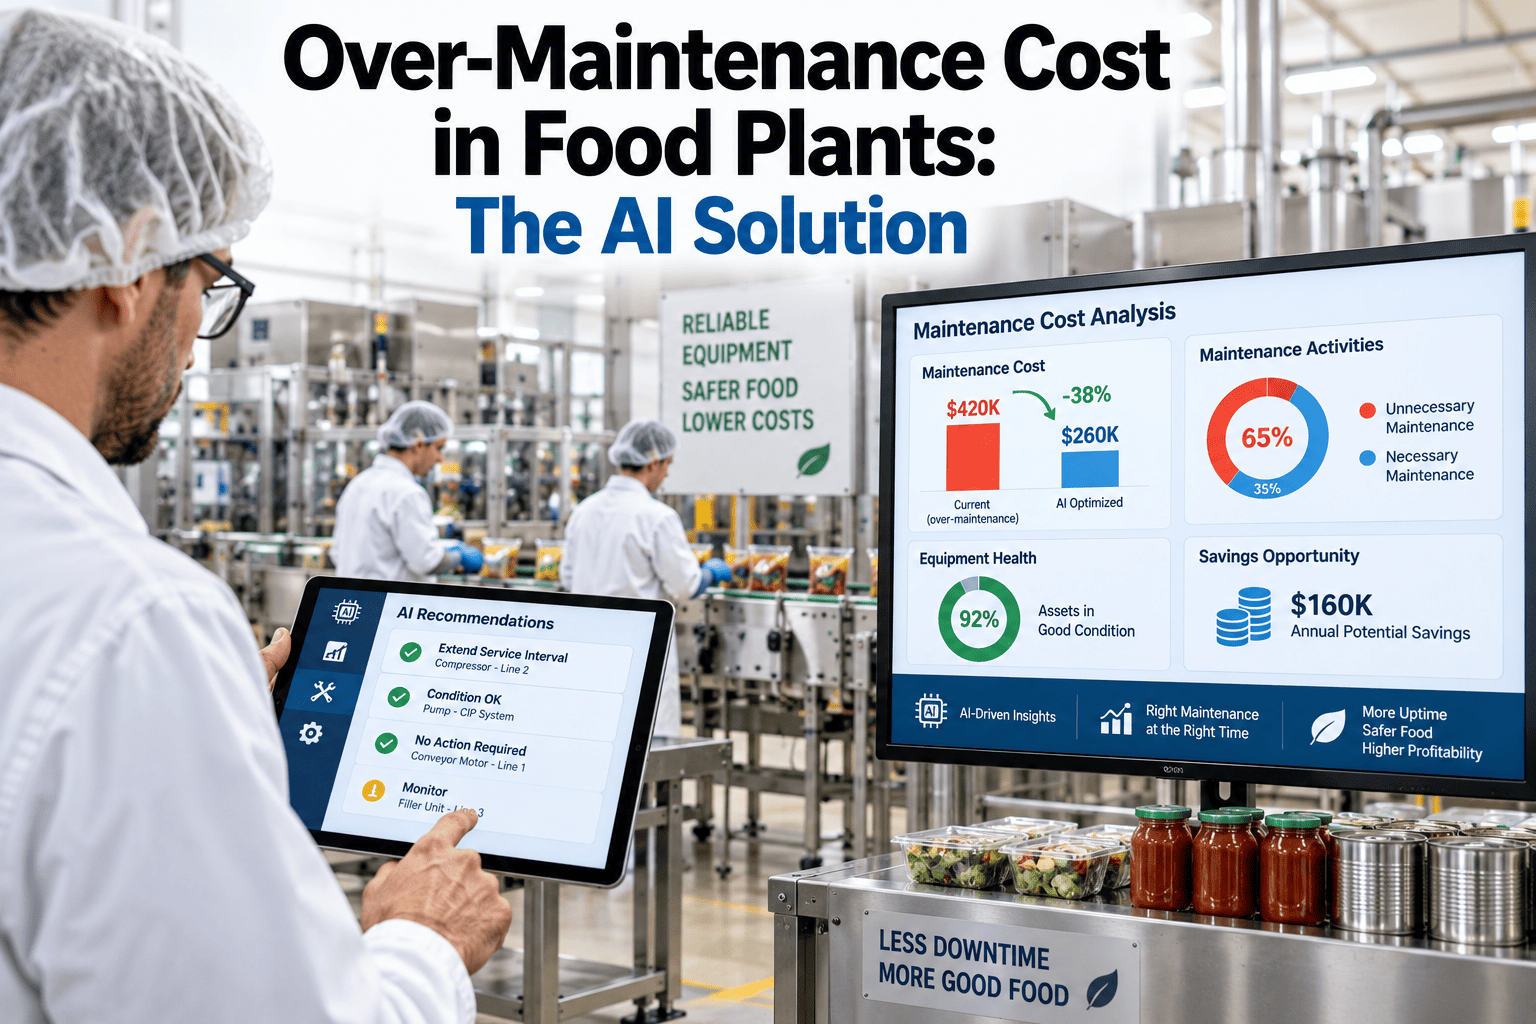
A 180-asset food plant spending forty-two thousand dollars a year on preventive maintenance labor sounds like a plant doing everything right, disciplined, scheduled, nothing left to chance. Then an audit looks at what's actually inside those work orders and finds that a large share of the thirty-day tasks could safely stretch to ninety days without moving the needle on uptime, and a smaller share should never have been scheduled at all because the asset shows no sign of degradation when the technician opens it up. Every one of those unnecessary teardowns costs labor and parts twice, once to perform the task and again in the failures it sometimes causes through reassembly errors, contamination, and misalignment that a healthy asset never needed in the first place. If your PM calendar hasn't been challenged against real degradation data in a while, book a demo to see exactly how much of it is buying you nothing.
FOOD & BEVERAGE · PREVENTIVE MAINTENANCE OPTIMIZATION
Your PM Calendar Is Probably Maintaining Assets That Don't Need It
Industry studies put unnecessary preventive maintenance at roughly a third of everything scheduled. iFactory's AI reviews your actual failure and condition data to right-size every PM interval, cutting wasted labor and parts without touching reliability.
SHARE OF SCHEDULED PM WITH NO DEGRADATION SIGNAL
37% of PM tasks performed on assets showing zero signs of wear at the time of service
FOUR WAYS THE WASTE ADDS UP
Over-Maintenance Doesn't Show Up as One Line Item
Nobody budgets a line called "wasted maintenance." Instead the cost hides inside categories that look completely normal on a monthly report: labor hours, parts consumption, downtime windows, and failure rates that all creep upward slightly, none of them alarming on their own, all of them traceable back to the same root habit of maintaining by the calendar instead of by actual condition.
Labor on Tasks That Add No Value
Technicians spend hours opening, inspecting, and reassembling equipment that was already running exactly the way it should have been left alone, time that could have gone to actual predictive or corrective work.
Unnecessary Parts Consumption
Gaskets, seals, filters, and bearings replaced on a fixed schedule regardless of remaining service life quietly drain inventory budget on components that had months of useful life left.
Induced Failures From Reassembly
Opening a healthy gearbox or motor introduces real risk: misalignment, contamination, and human error during reassembly cause a measurable share of failures that a left-alone asset would never have experienced.
Reduced Equipment Availability
Every PM window is production time the line isn't running, and a schedule padded with unnecessary tasks eats into availability that a right-sized program would have given back to output.
None of these four categories looks dramatic in isolation, which is exactly why over-maintenance survives budget reviews year after year while a comparable amount of avoidable spend in almost any other department would have been caught and cut long ago.
SIGNS TO WATCH FOR
Five Signals Your Program Is Over-Maintaining
Most maintenance leaders can't say with confidence which of their PM tasks are earning their keep, because the question has never been asked in a structured way. These five patterns are the clearest indicators that a program has drifted toward maintaining by habit rather than by evidence.
✓PM intervals copied directly from OEM manuals without adjustment for your actual operating conditions, load profile, or environment, since manufacturer intervals are conservative by design and often shorter than what your specific equipment actually needs.
✓Technicians routinely report "nothing found" on inspection tasks, a pattern that, if it repeats across multiple cycles on the same asset, is a strong signal the interval is tighter than the actual degradation rate requires.
✓Post-PM failure rates that don't visibly improve compared to a control group of similar assets on a longer interval, suggesting the extra frequency isn't buying additional reliability.
✓Parts replaced on schedule that test as still within spec when pulled, meaning the replacement interval is shorter than the component's actual useful life.
✓No condition-based triggers anywhere in the program, with every single task driven purely by a calendar date regardless of how the asset is actually running.
Find out how much of your PM program is unnecessary
iFactory can run a task-level audit against your existing PM library and show you exactly which intervals are safe to extend.
WHERE A TYPICAL BUDGET ACTUALLY GOES
Breaking Down a Maintenance Dollar
Plants that run a cost analysis at the work-order level, rather than just tracking a total maintenance budget, consistently find the same rough split, and the two largest segments are exactly the ones AI-driven optimization is built to target directly.
Reactive / Emergency — 38%
Scheduled PM (Calendar) — 31%
Parts & Materials — 18%
Labor Overhead — 13%
Reducing the reactive segment happens by catching failures earlier through condition data; reducing the scheduled PM segment happens by removing tasks that a healthy asset never needed. Together these two segments represent roughly seventy cents of every maintenance dollar, which is why a program that only ever optimizes parts procurement or labor overhead is chasing the smaller half of the actual opportunity.
CALENDAR VS AI-ADAPTIVE
What Changes When Intervals Follow the Asset Instead of the Date
| Factor |
Fixed Calendar PM |
AI-Adaptive PM |
| Interval basis |
Fixed date regardless of actual condition |
Condition, runtime, and failure-probability data |
| Healthy-asset servicing |
Serviced on schedule even with no degradation |
Deferred until real degradation signals appear |
| Induced failure risk |
Higher, from unnecessary teardown and reassembly |
Lower, fewer unneeded interventions overall |
| Labor allocation |
Spent on tasks regardless of actual need |
Freed up for predictive and corrective priorities |
| Typical labor savings |
Baseline, no adjustment applied |
15–25% reduction without reliability impact |
HOW THE RIGHT-SIZING ACTUALLY HAPPENS
From Fixed Calendar to Evidence-Based Interval
01
Task-Level Review
Every existing PM task is reviewed against the actual failure mode it's meant to prevent, not just whether it's currently scheduled.
02
Age Exploration
Historical data reveals the real age at which each asset class begins showing degradation, rather than relying on a manufacturer's conservative default.
03
Condition Monitoring Layer
Where available, vibration, thermal, and runtime data replace the calendar as the actual trigger for when a task should fire.
04
Continuous Recalibration
Intervals aren't set once and forgotten, they adjust automatically as new failure and condition data accumulates over time.
A 180-asset food processing plant running exactly this process found forty percent of its thirty-day tasks could safely extend to ninety days, another fifteen percent could be eliminated entirely in favor of condition-based monitoring, and the result was over ten thousand dollars in direct labor savings alongside a meaningful drop in post-PM failure events within the first six months. That's the shape of the opportunity sitting inside most PM programs that have never been challenged against real data.
ASSET CLASS BY ASSET CLASS
Not Every Machine Wastes the Same Way
A blanket rule like "extend every interval by fifty percent" is almost as dangerous as never questioning the calendar at all, because different asset classes carry very different consequences of failure and very different actual wear patterns. The right approach treats each class on its own terms.
Fillers & Packaging Lines
High duty cycle, moderate failure consequence. Usually the biggest single source of over-maintenance waste because fixed intervals rarely track actual seal, belt, and sensor wear.
Mixers & Blenders
Seal and bearing wear varies heavily with product viscosity and batch frequency, making these strong candidates for condition-based triggers over a fixed calendar.
Ovens & Thermal Processing
Higher consequence of failure and food safety exposure means these assets are usually poor candidates for aggressive interval extension without strong condition data backing it.
Conveyors & Material Handling
Low consequence, high volume of individual units, and often the easiest place to prove out extended intervals safely before touching more critical equipment.
Refrigeration & Cold Chain
Regulatory and product-safety stakes are high enough that most plants keep these on tight, sometimes even tighter than current, condition-based schedules rather than extending them.
Pumps & Motors
Well-documented failure signatures in vibration and thermal data make these some of the most reliable candidates for shifting fully off the calendar entirely.
Sorting your own equipment fleet this way, rather than applying one policy plant-wide, is what separates a genuine right-sizing program from a blunt cost-cutting exercise that a reliability team would be right to resist.
MYTH VS REALITY
What Maintenance Teams Usually Get Wrong About PM Frequency
MYTH
"More frequent maintenance is always safer than less frequent maintenance."
REALITY
Invasive tasks carry their own failure risk through reassembly errors and contamination, so frequency past the point of actual need can measurably increase failures rather than prevent them.
MYTH
"OEM-recommended intervals are the safest default to follow."
REALITY
Manufacturer intervals are set conservatively across a wide range of operating conditions and are frequently thirty to fifty percent shorter than what your specific environment actually requires.
MYTH
"If we can't measure vibration or temperature, we can't optimize PM."
REALITY
Work order history alone, especially technician notes on inspection findings, already contains most of the signal needed to identify the clearest cases of over-maintenance.
MYTH
"Reducing PM frequency is really just a cost-cutting move in disguise."
REALITY
The labor and parts freed up don't disappear from the maintenance budget, they get redirected to the predictive and corrective work that actually prevents unplanned downtime.
FREQUENTLY ASKED QUESTIONS
What Maintenance Leaders Ask Before Right-Sizing PM
How do we know an extended interval won't cause more failures?
This is the right question to ask before changing anything, and it's answered with data rather than assumption. The process starts by identifying assets where technicians have repeatedly reported no degradation at inspection, then extends the interval in controlled steps while tracking failure rates against a comparable baseline group, rather than making a blanket change across an entire asset class at once. If a post-PM failure rate begins climbing on an extended asset, the interval tightens back immediately, so the approach is self-correcting rather than a one-time bet on untested assumptions.
Book a demo to see how this staged approach would apply to your specific asset classes.
Won't extending intervals just shift risk from planned to unplanned failures?
That's exactly the failure mode this process is designed to avoid, which is why it never extends an interval blindly based on labor savings alone. The extension only happens on assets and tasks where historical data shows no correlation between the current frequency and actual reliability outcomes, meaning the maintenance was buying nothing beyond peace of mind. Assets that do show a meaningful reliability benefit from their current frequency, or that carry a higher consequence of failure, are explicitly excluded from interval extension and can even move to a tighter, condition-based trigger instead if the data supports it.
Contact our support team to review which of your assets would and wouldn't qualify.
Do we need vibration sensors or other condition monitoring hardware to start this?
No, and this is one of the more common misconceptions that delays plants from starting. A meaningful first pass of PM optimization can run entirely on your existing work order history, technician inspection notes, and failure records, since a large share of over-maintenance is visible simply from how often "nothing found" appears on a completed PM task. Condition monitoring hardware adds real value as a second phase, particularly for critical or high-consequence assets, but it isn't a prerequisite for identifying and correcting the most obvious sources of PM waste already sitting inside your existing data.
Book a demo to see what a first-pass audit could find using only your current CMMS data.
How long does it take before we see measurable savings?
Most plants see the first concrete labor and parts savings within the first PM cycle after intervals are adjusted, since the savings come directly from tasks no longer being performed rather than from a slower-building efficiency gain elsewhere. The full reliability picture, confirming that extended intervals haven't introduced any new failure pattern, typically takes two to three completed cycles to validate with confidence, which is why the rollout is staged rather than applied across the entire plant on day one. Plants running this process consistently report a meaningful drop in post-PM failure events alongside the direct labor savings within the first six months.
Contact our support team to map a realistic savings timeline against your specific asset count.
Will our technicians resist a program that changes schedules they're used to?
Some initial skepticism is normal, particularly from technicians who've spent years following a fixed calendar and have learned to trust it, but this generally fades quickly once the data is put in front of them directly rather than presented as a top-down mandate. Showing a technician their own repeated "nothing found" entries on a specific asset is usually more persuasive than any general argument about efficiency, because it validates something they already suspected but had no formal channel to act on. Framing the change as freeing up their time for higher-value predictive and corrective work, rather than simply doing less, tends to land far better than framing it purely around cost reduction.
Book a demo to discuss a rollout approach for your specific team.
MAINTAIN WHAT NEEDS IT, NOT WHAT'S ON THE CALENDAR
Stop Paying Twice for Maintenance Your Assets Don't Need
iFactory reviews your actual failure and condition data to right-size every PM interval, cutting wasted labor, parts, and induced-failure risk without touching the reliability you already depend on.