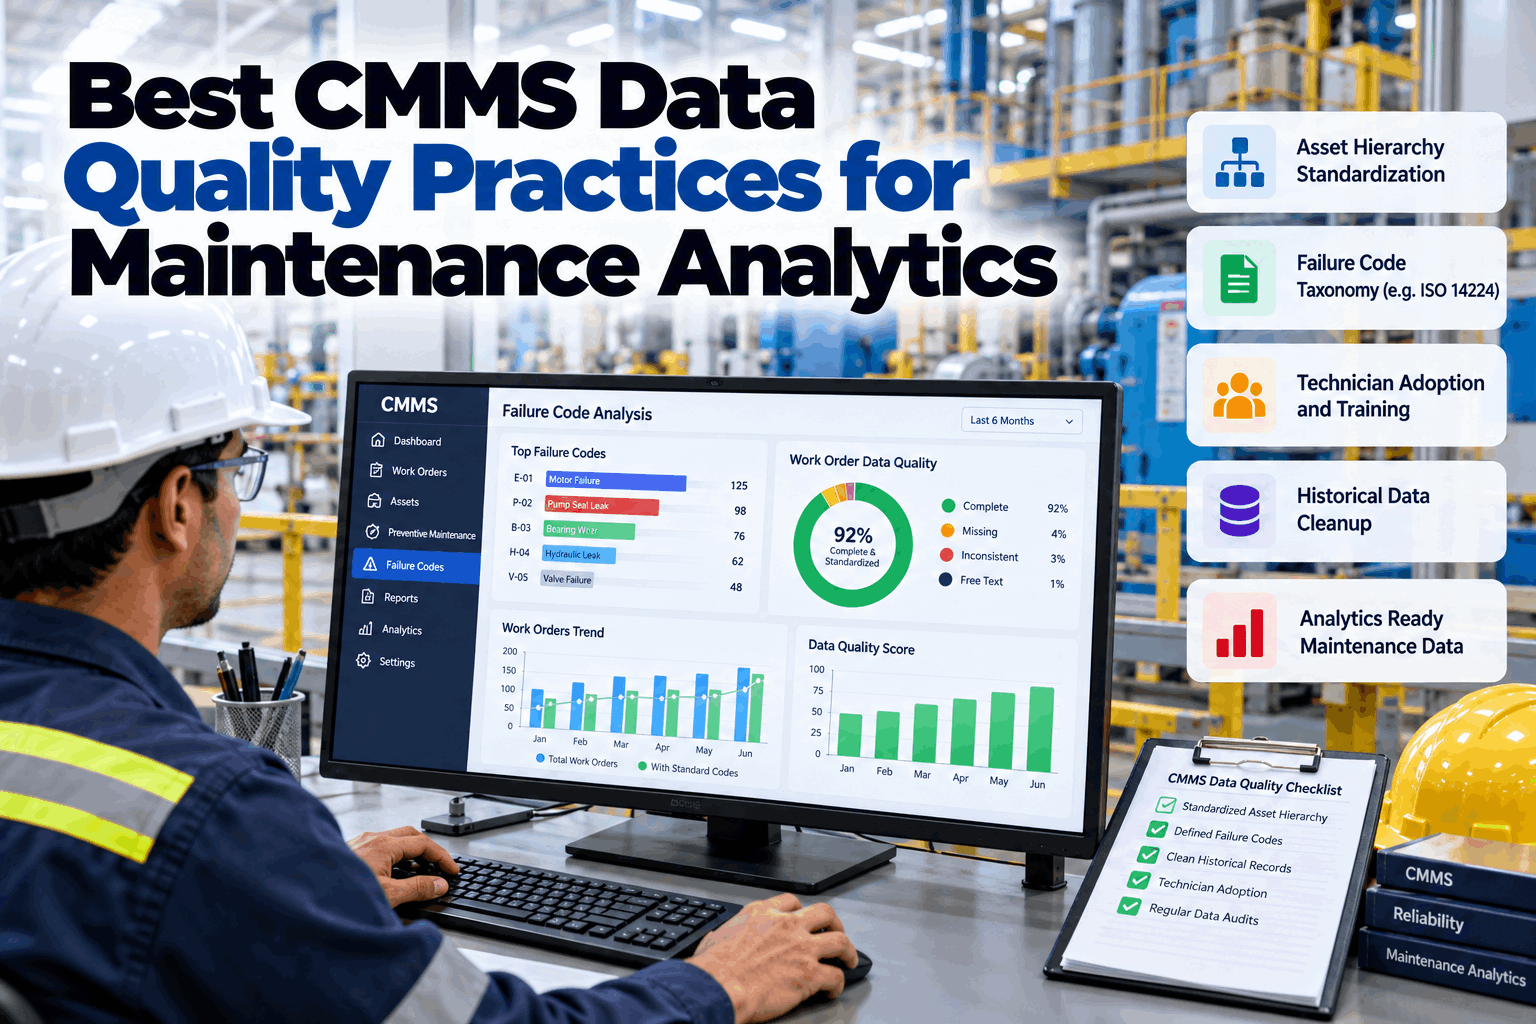
A typical mid-size plant logs 8,000 to 14,000 work orders a year — and in most CMMS databases, a large share of them close with a failure described however the technician felt like typing it: "pump broken," "fixed it," logged against a generic "Misc. Equipment" placeholder instead of the specific asset. None of that is queryable. A reliability manager can't run a failure-code Pareto, can't calculate MTBF, can't build a bad-actor list — the data to answer those questions exists somewhere in the database, but it's locked inside free text that no report can parse. Once a plant does get its codes standardized, the pattern is usually stark: four to six failure codes typically explain 80% of events, and a small handful of assets — in one real example, just 18 out of 180 — account for well over half of all corrective work. That signal was always there. iFactory's CMMS Data Quality practice is built around getting it out: taxonomy design, technician adoption, and cleaning up the years of historical records sitting unused.
iFactory CMMS Data Quality
Best CMMS Data Quality Practices for Maintenance Analytics
Taxonomy design, technician adoption, and historical record cleanup — the three things standing between a CMMS full of free text and one that actually supports reliability analytics.
8,000-14,000
work orders logged per year, mid-size plant
4-6 codes
typically explain 80% of failures
95%+
target fault code coverage rate
18-24 mo
of clean data for reliable analytics
The Four Pillars — What a Data Quality Program Should Say
CMMS data quality isn't one initiative, it's four — a taxonomy, an adoption discipline, a cleanup of what already exists, and ongoing visibility into all three. This is what that view looks like mid-program.
Failure Code Taxonomy
ISO 14224-aligned
Defined
Codes standardized14from 47 raw variants
StructureProblem/Cause/Remedyper ISO 14224
Coverage target95%+of closed WOs
StatusLivein CMMS dropdowns
Technician Adoption
Point-of-capture discipline
Gap
Fault code compliance68%below 95% target
Free-text overrides142this month
Mobile dropdown usePartialrollout in progress
Spot-check coverage5-10%of closed WOs
Historical Cleanup
NLP-assisted remap
In progress
WOs needing remap11,400of 14,000 total
Mapped so far6,200via NLP
Manual review queue1,850low-confidence matches
Cleanup time saved~80%vs fully manual
Bad Actor Visibility
Unlocked by clean data
Unlocked
Corrective WOs traced61%to 18 of 180 assets
MTBF calculableYespost-cleanup
Pareto codes5 codes= 80% of events
Reliability backlogPrioritizedby dollar impact
Data Quality Maturity — Where Most Plants Actually Sit
CMMS data quality isn't binary — it's a maturity curve, and most plants sit somewhere in the middle without realizing how close "good enough for reporting" is to "unusable for analytics."
Governed, ISO 14224-aligned
95%+ coverage
Analytics-ready
Structured, partial adoption
70-85% coverage
Good, gaps remain
Mixed free-text + codes
40-60% coverage
Typical mid-maturity
Mostly free-text
15-30% coverage
Reports unreliable
No structure, "fixed it" notes
<10% coverage
Unusable for analytics
Most plants discover they're closer to the bottom of this scale than they expect — half the work orders logged against a generic placeholder asset, failure codes left blank, and resolution notes that amount to "fixed it" are a common starting point, not an outlier.
The Failure Modes of Poor CMMS Data
The same handful of data problems repeat across almost every plant that hasn't formalized its taxonomy and enforcement — each one individually small, collectively enough to make reporting unreliable.
Generic placeholder assets
Common
Work orders logged against a broad location instead of the specific asset that failed.
Missing failure codes
Common
Closed without Problem, Cause, or Remedy codes, ruling out root-cause analysis.
Free-text resolution notes
Common
"Fixed it" style entries that can't be queried, categorized, or trended.
Inconsistent asset hierarchy
Moderate
The same equipment coded differently across sites, shifts, or technicians.
No historical backfill
Moderate
New taxonomy adopted going forward, but years of past records stay unusable.
Want to see how your own CMMS data actually scores? Book a demo — bring 90 days of closed work orders and we'll run a baseline audit.
Free-Text Culture vs Governed CMMS — Same Work Order, Two Outcomes
Both approaches capture the same event: a technician fixed something. Only one of them leaves behind data anyone else can actually use.
Free-Text Culture
"Can we tell which asset fails most, and why?"
Failure described in whatever words the technician typed
The same failure mode logged a dozen different ways across the plant
No way to query, Pareto, or trend without manually re-reading every entry
MTBF and bad-actor analysis effectively impossible
Governed CMMS
"Can we tell which asset fails most, and why?"
Failure selected from a standardized, ISO 14224-aligned code list
The same failure mode logged the same way, every technician, every shift
Queryable Pareto, MTBF, and bad-actor lists built automatically
Reliability backlog prioritized by data, not instinct
How to Build CMMS Data Quality, Step by Step
The sequence matters — a taxonomy nobody enforces is as useless as enforcement with no taxonomy to enforce.
01
Design the Taxonomy
Build a 12-15 code failure taxonomy aligned to ISO 14224, mapped to Problem, Cause, and Remedy.
02
Enforce at the Point of Capture
Replace free-text fields with mandatory structured dropdowns on mobile and web.
03
Backfill Historical Records
Map existing free-text work orders to the new taxonomy using NLP-assisted classification.
04
Monitor Adoption by Team
Track fault code coverage rate by technician and asset class, not just plant-wide.
05
Unlock the Analytics
Run failure-code Pareto, bad-actor lists, and MTBF once coverage crosses the usability threshold.
What Clean CMMS Data Delivers
These are the outcomes reliability teams typically see once coverage crosses from "mostly free text" into "governed and queryable."
95%+
Target fault code coverage
from taxonomy + enforcement
4-6 codes
Usually explain 80%
of failure events, once coded
~80%
Faster cleanup
NLP-assisted vs fully manual
18-24 mo
Of history needed
for reliable MTBF and Pareto
Curious how close your own CMMS data is to analytics-ready? Talk to our team — we'll score your fault code coverage against the maturity scale.
Frequently Asked Questions
What's a realistic failure code taxonomy size — how many codes is too many?
Most plants land well with 12-15 top-level failure codes (leak, overload, vibration, contamination, calibration drift, wear, electrical, software, and similar categories), each paired with a cause and remedy code for more granular detail. Taxonomies with 50+ codes tend to fail in practice — technicians can't reliably choose between near-duplicate options under time pressure, so they default back to the closest-sounding free-text description anyway.
Do we need ISO 14224 specifically, or is a simpler internal taxonomy enough?
ISO 14224 is most valuable when you need to benchmark against industry failure data or roll up data across multiple sites with different histories — it gives you a common language. A simpler internal taxonomy, built the same way but without external alignment, works fine for single-site analytics. The discipline of having a controlled list matters more than which standard it's based on; ISO 14224 alignment is a nice-to-have that pays off most at scale.
What do we do with years of free-text historical work orders?
NLP-assisted classification can map the majority of historical free-text descriptions to a new standardized taxonomy automatically, typically cutting manual cleanup time by around 80% compared to a fully manual remap. The remainder — low-confidence matches and ambiguous entries — go into a manual review queue rather than being auto-classified, since forcing a bad match is worse than leaving a record flagged as unmapped.
How do we get technicians to actually use the structured fields?
Enforcement at the point of capture matters more than training alone — mandatory dropdowns that block work order closure without a failure code, rather than an optional field technicians can skip, is what actually moves adoption. Weekly spot checks on a sample of closed work orders (5-10% is a common starting cadence) catch drift before it becomes a habit, and tying coverage rate to team-level visibility tends to work better than individual call-outs.
How long before CMMS data is actually reliable enough for predictive analytics?
Most reliability programs want at least 18-24 months of consistently coded corrective work orders before MTBF and failure-pattern models are trustworthy — less than that and seasonal or campaign-specific effects can masquerade as trends. That said, failure-code Pareto and bad-actor lists are useful almost immediately once coverage crosses roughly 80-90%, since those don't require the same historical depth as a full predictive model.
Stop reporting on data you can't trust.
Get Your CMMS Data Analytics-Ready
Bring 90 days of closed work orders. We'll score your current fault code coverage, show what a standardized taxonomy would look like for your asset base, and estimate how much historical cleanup is realistic with NLP-assisted mapping.
Taxonomy
designed & mapped