A voice entry is only useful if it is right. Food plants make that hard. Fillers, compressors and freezer fans push noise past the level where hearing protection is required, while gloves, hoods and cold work against the headset. This guide covers how accuracy is measured, which mics hold up, why speech should run on site, and how read-back stops a mishear from becoming a record. Hear it in your own noise in a voice accuracy demo.
Voice Entries That Stay Accurate in Loud Rooms and Freezers
The iFactory Edge Voice Engine runs on-premises speech models tuned to your plant noise and food terms. It works with gloves and hoods, and reads back every entry before saving.
How Loud Food Processing Rooms Get
Noise is the first enemy of accuracy. A NIOSH health hazard evaluation at an egg products plant measured levels from 85 dBA in the pick and prewash area up to 98 dBA in the sifter and powder room. Under OSHA 1910.95, a hearing conservation program is required at an 8-hour average of 85 dBA. So the speaker often wears hearing protection, and the mic hears the room too. Check your rooms with our support team.
In loud rooms people raise their voice and change how they speak, known as the Lombard effect. A model trained on calm office speech hears this as a different voice, so always test at shift noise.
Word Error Rate, the One Number to Ask For
Word error rate (WER) is the standard accuracy measure for speech recognition. It counts the swapped words (S), missed words (M) and extra words (E) in what the system heard, then divides by the number of words actually said (N). Lower is better. The example uses illustrative words. Ask for WER measured in your own rooms in a site voice test.
The missing word "loose" is one error in ten, but it changes what the record means. Track errors on key fields too: asset IDs, numbers, allergens and pass or fail words.
Mics That Keep Speech Above the Noise
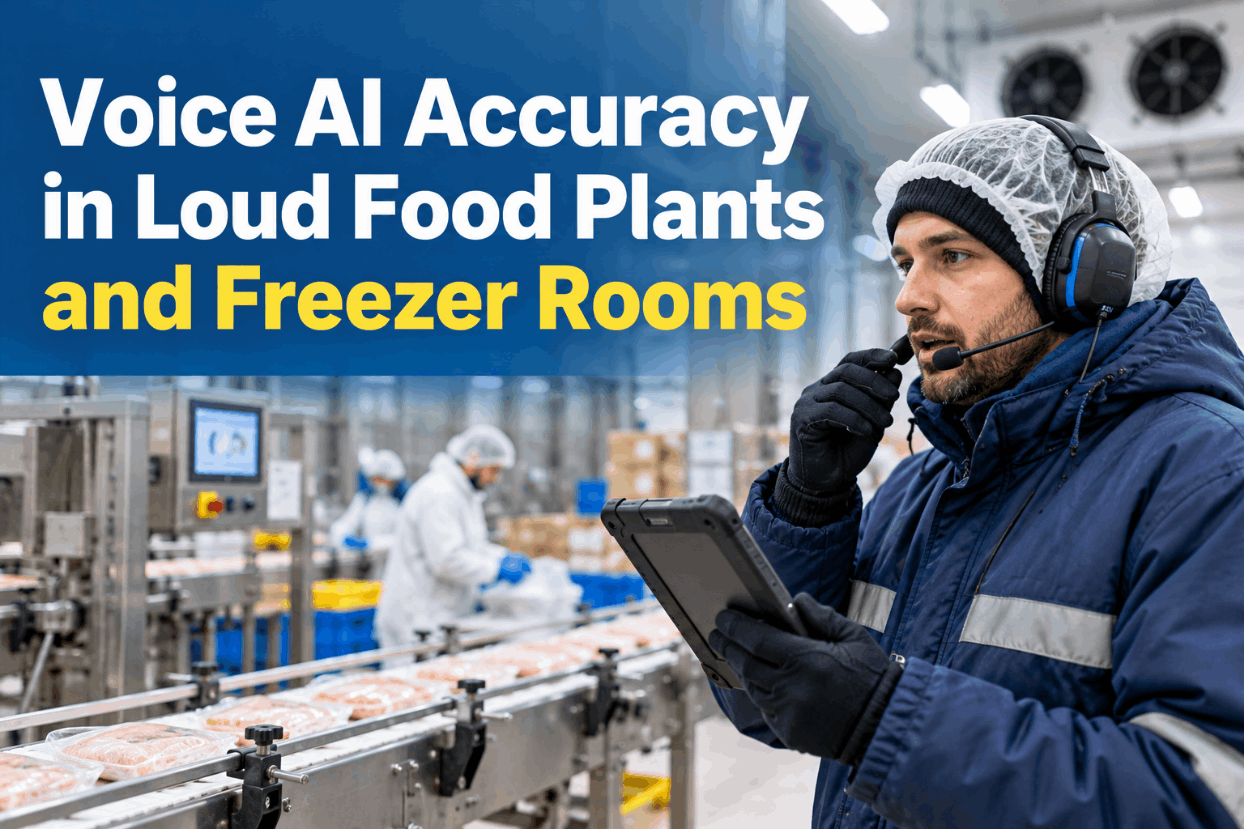
The microphone decides most of the accuracy before any model runs. A close boom mic with noise cancelling picks up the voice and rejects the room. Bone-conduction mics pick up far less room noise but carry a narrower, muffled band of speech. Zebra's HS3100 spec sheet, for example, lists a sealed noise-cancelling mic with more than 10 dB of noise immunity. Compare options with our headset team.
Freezer Rooms: Ratings, Hoods and Gloves
Cold brings its own errors. Batteries lose runtime, cables stiffen and hoods push the mic away from the mouth. Check the operating temperature on the spec sheet. Zebra lists the HS3100 at −30°C to +50°C, and Honeywell lists its wired SR-30 at −40°C to 50°C, with no headset battery to fail. Plan freezer kit with our voice engineers.
Hear the Read-Back Before You Trust It
Every entry is read back in plain words and saved only after the worker says confirm. Numbers, allergens and asset IDs follow a fixed format, so a mishear is caught at the asset, not in the audit.
On-Site Speech or Cloud Speech
Where the model runs changes speed, privacy and uptime. Cloud speech sends audio across the plant network and the internet before an answer comes back, so delay depends on the link, and freezer rooms often have weak Wi-Fi. On-site speech keeps audio inside the plant and keeps working if the internet link fails. Review your network with our support team.
- Audio leaves the site for every entry
- Delay depends on Wi-Fi and the internet link
- Entries stop when the link is down
- General models, with limited tuning to your rooms
- Audio processed on the plant's own server
- Short, steady response on the local network
- Keeps working if the internet link is down
- Models tuned to your noise and your terms
Teach the Model Your Plant's Words
General speech models stumble on plant words: product codes, asset tags and allergens spoken fast in noise. A custom vocabulary tells the model which words to expect and how your crews say them. Allergens deserve special care. Since 1 January 2023, US law lists nine major food allergens, with sesame the newest. Load your list with our setup team.
Fifteen and fifty, "line four" and "line for", "can" and "can't". Pair risky words with a field check, so a reading of fifty in a freezer field is queried rather than saved.
How Read-Back Stops a Mishear Becoming a Record
No speech model is right every time, so the design must catch what slips through. The Edge Voice Engine checks each field against its expected range, reads the entry back in a fixed order and saves nothing until the worker confirms. Walk through the flow with our support team.
Say Numbers One Way, Every Time
The most costly mishears are numbers. Aviation solved this long ago: FAA phraseology reads frequencies digit by digit and says "point" where the decimal falls. The same idea works on a food plant floor. Build these rules into the read-back voice and into crew training. Get a rules sheet from our voice team.
Push-to-Talk, Wake Word or Open Mic
An open mic in a loud room hears everything, including the next person's shout. Push-to-talk marks exactly when an entry starts and ends, which cuts false starts and keeps noise between entries away from the model. For most food plant rooms it is the safer default. Choose per room with our support team.
A Room Test Sheet for Go-Live
Test every room type before go-live with real crews at real shift noise. One sheet per room keeps results comparable. Ask for a blank copy in a test planning call.
Three Mishears and How They Were Caught
These are illustrations, not case studies. They show where errors usually come from and which safeguard catches each one. Review your own risky phrases with our support team.
What Accuracy Is Worth in Correction Time
Accuracy shows up as time spent fixing entries at read-back. This worksheet uses assumed inputs only, to show how the error rate changes that time. Swap in entry counts from your own pilot and build it with our voice team.
The bigger value is harder to price: wrong records that never reach the system. Leave it out of the sum unless your audit history supports a figure.
Edge Voice Engine and Server in One Package
iFactory delivers the Edge Voice Engine turnkey. A pre-configured NVIDIA AI server ships racked and ready with speech models loaded, then tuned on site to your noise and vocabulary. You rack it, plug in power and Ethernet, and the AI is live. Get a scoped quote from our support team.
- Pre-configured NVIDIA AI server, racked and ready
- On-premises speech models, with no audio sent to the cloud
- Custom vocabulary for products, assets and allergens
- Headset guidance for loud rooms and freezers
- Read-back and number rules set per field
- Room-by-room accuracy tests with your crews
- 24x7 remote monitoring of models and server
Server racked, rooms measured, vocabulary loaded, sample speech recorded at shift noise.
Models tuned to your rooms, test sheets run, WER checked against the pass mark.
Voice entry live, crews trained on push-to-talk and read-back, monitoring running.
Industrial Voice AI Software Built for Noise and Cold
iFactory is built for the rooms where voice is hardest, so accuracy holds where crews need it most. See it in your own noise in a short demo.
What Plant Managers Ask About Voice AI Accuracy
Make Every Spoken Entry One You Can Trust
Run speech on site, tuned to your noise and food terms, with push-to-talk and read-back on every entry. Delivered turnkey and live in 6 to 12 weeks.