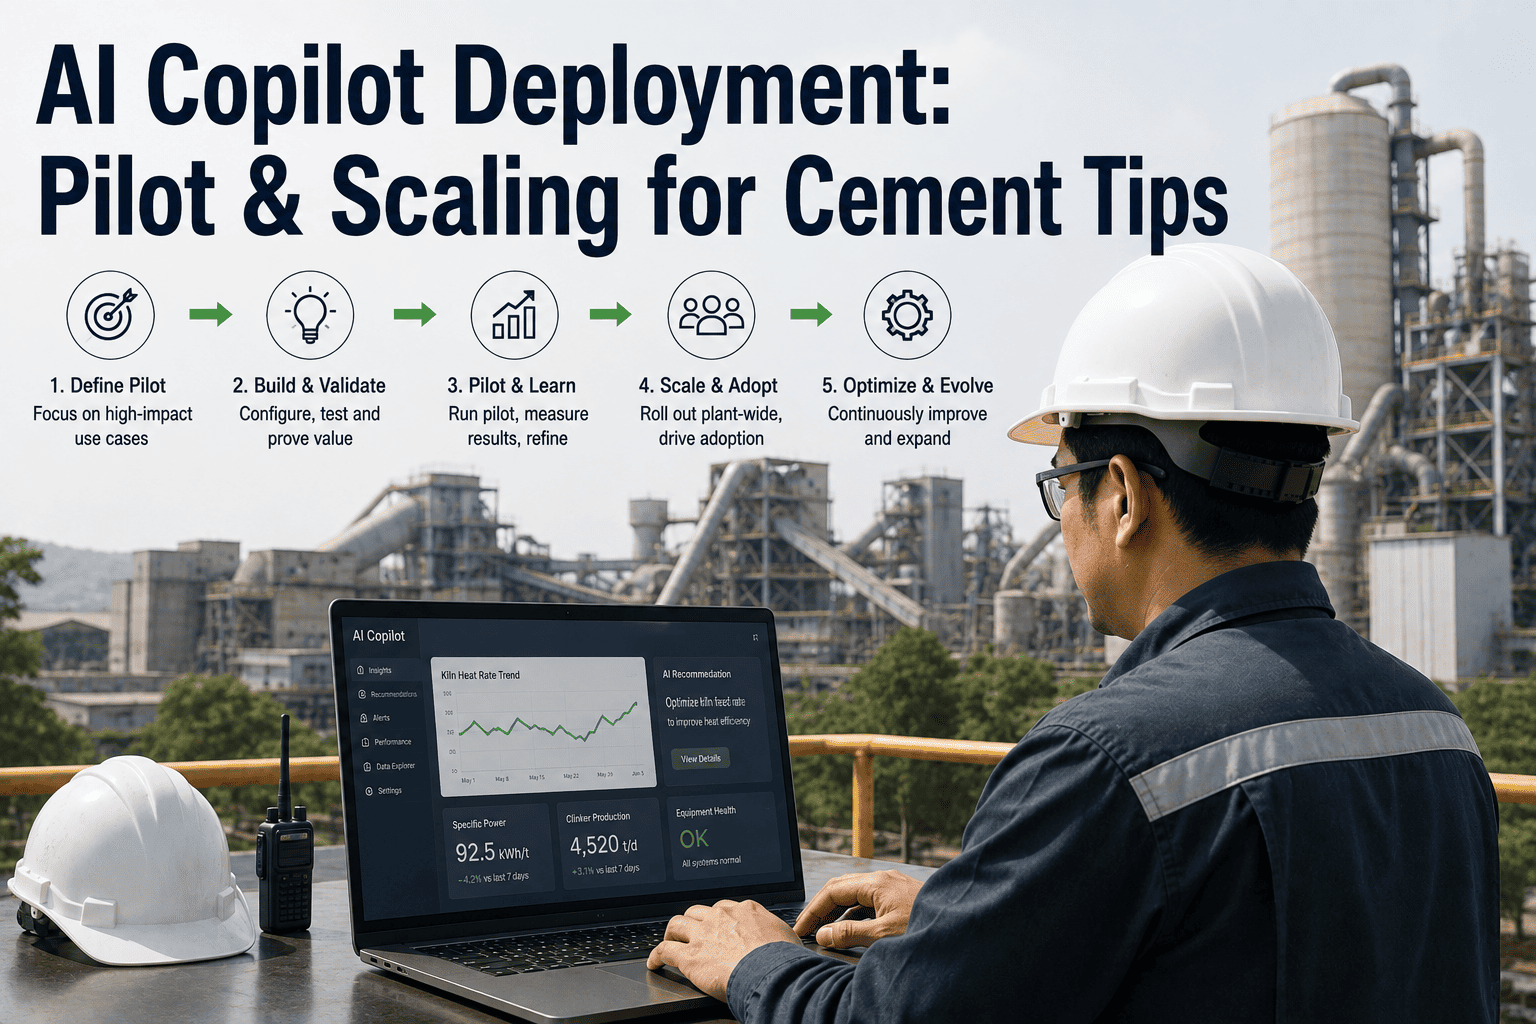
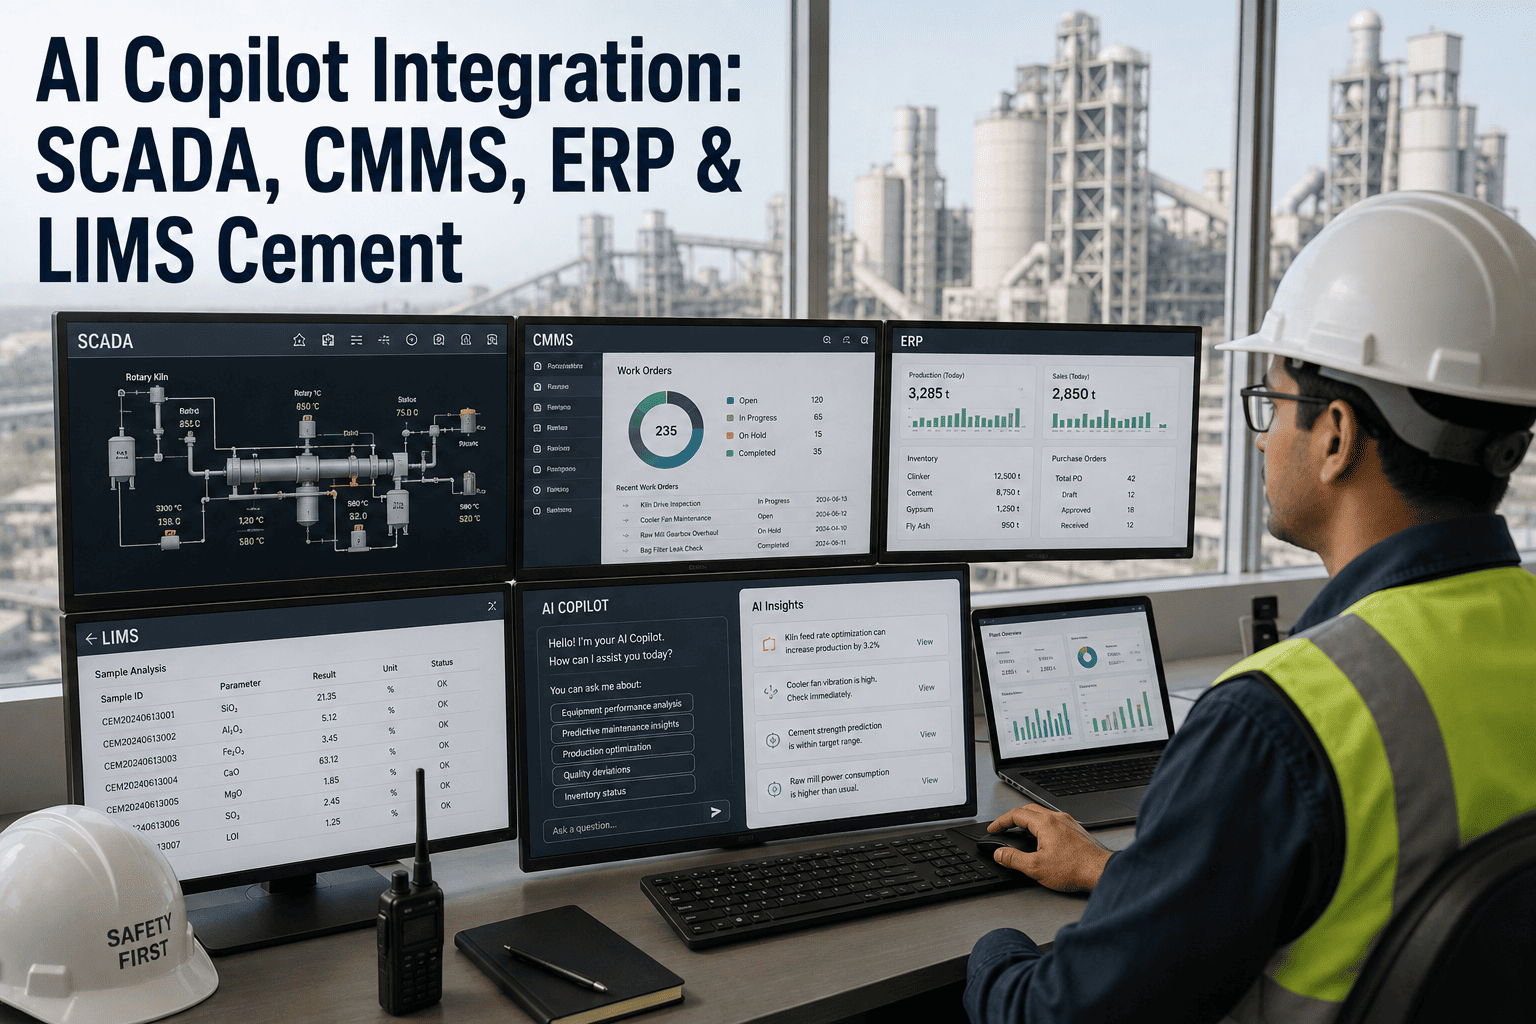
AI Copilot Deployment: Pilot & Scaling for Cement Tips
By Johnson on August 8, 2026
Most AI copilot pilots at cement plants technically work and still never scale past the one line or one shift where they launched. The model performs fine in testing, a handful of operators like it, and then eighteen months later it's still running on that one kiln with nobody else in the network using it. The problem usually isn't the model — it's that the pilot was never designed with a path to scale in mind, and the plant has no defined criteria for when to expand it versus when to kill it. Getting from a single successful pilot to a network-wide rollout takes a deliberate deployment path. See how iFactory structures a pilot-to-scale rollout for cement operations specifically.
AI Copilot · Deployment Strategy
AI Copilot Deployment: Pilot and Scaling for Cement Operations
A phased path from a single-line pilot to a network-wide copilot rollout — use case selection, success metrics defined up front, and the scaling decisions that separate a proven deployment from a permanent pilot.
The Gap Between a Working Pilot and a Rolled-Out Program
A pilot that performs well technically and a program that actually spreads across a plant network are two different achievements, and the second one depends on decisions made well before the first pilot even launches. Plants that treat a pilot as a standalone experiment, without defined success criteria or a plan for what expansion looks like, tend to end up with exactly what they started: one successful pilot, permanently.
No Defined Success Criteria Up Front
When "success" isn't quantified before the pilot starts, it's nearly impossible to make an objective case for expanding it afterward — the copilot either quietly keeps running in its original corner or quietly gets abandoned, with no clear decision ever actually made, and no one able to say confidently whether it worked.
Use Case Chosen for Novelty, Not Value
A pilot built around the most technically interesting problem rather than the one with the clearest operational value and the lowest execution risk tends to impress in a demo and struggle to justify the investment needed to scale it further once the initial excitement fades.
Nothing Built to Be Reusable
A pilot built as a one-off, without reusable data pipelines, evaluation frameworks, or configuration templates, means the second and third deployments start from scratch instead of building on what the first one already proved, multiplying the effort required at every subsequent site.
Adoption Never Actually Measured
Tracking whether the model performed well in testing is not the same as tracking whether operators actually kept using it after the novelty wore off — a copilot with strong technical accuracy and weak adoption is a cost with no return, no matter how good the underlying model is.
Building for Reuse
What Makes the Second and Third Deployment Faster Than the First
Vendor-led AI implementations succeed roughly twice as often as internal builds according to recent industry research, and a large part of that gap comes down to whether the underlying infrastructure was built with reuse in mind from the start. A pilot built as a one-off forces every future line to start from zero; a pilot built with scale in mind turns each new deployment into a configuration exercise rather than a fresh build, which is the difference between a program that compounds and one that plateaus at a single successful site.
Shared Data Pipelines
Connecting the copilot to plant data through a pipeline designed to extend across lines, rather than a bespoke connection built for one kiln, means the second deployment reuses the plumbing instead of rebuilding it from scratch, which is often the single biggest source of delay in a rushed rollout.
Configuration Templates, Not Custom Builds
A copilot configured against a template of common cement plant SOPs, equipment types, and compliance requirements can be adapted to a new line in days rather than the weeks a fully custom build requires, freeing up the project team to focus on the genuine local differences instead of rebuilding the basics.
Consistent Evaluation Framework
Using the same success metrics and evaluation approach across every deployment means performance can genuinely be compared line to line and plant to plant, instead of every rollout inventing its own definition of what "working well" means and making cross-site comparison effectively meaningless.
Documented Vendor or Internal Playbook
A written playbook capturing what worked and what didn't during the pilot phase — configuration choices, integration gotchas, adoption tactics — turns tribal knowledge from the first deployment into something the next site doesn't have to rediscover the hard way, saving weeks of avoidable trial and error.
Choosing the Right First Use Case
What Makes a Cement Copilot Pilot Worth Running
The single highest-leverage decision in the entire deployment path happens before any model is configured: picking the first use case. A pilot chosen well makes the case for scaling almost automatically; a pilot chosen poorly can sink appetite for the whole program regardless of how well the technology itself performs.
Clear, Measurable Value
A strong first use case ties directly to something the plant already tracks — troubleshooting time on kiln upsets, MSHA compliance response time, or maintenance work order turnaround — so the value of the pilot doesn't need to be argued for after the fact, since the baseline and the improvement are both already measurable.
Repeatable Across Lines or Plants
A use case with genuine operational similarity across multiple kilns or plants — not one tied to a single machine's unique quirks — has a real path to scale once proven, rather than staying permanently local to where it started because nowhere else looks quite the same.
Low Integration Risk
A first pilot that doesn't require deep SCADA integration or major IT infrastructure change reduces the number of ways the project can stall on something unrelated to whether the copilot itself actually works, keeping the pilot's timeline realistic and its scope contained.
Visible to the People Who Approve the Next Phase
A use case that operations leadership, plant managers, and the digital team all recognize as valuable — using the same definition of value — builds the alignment a scaling decision needs, rather than leaving the case to be made retroactively to people who weren't part of choosing it.
Stop Running Pilots That Never Go Anywhere
Build a Deployment Path With Scale Criteria Defined From Day One
iFactory helps cement plants pick a first use case with a real path to network rollout, not just a demo that impresses once.
What Actually Changes Once a Copilot Moves Past a Single Line
The jump from pilot to network rollout isn't just "do the same thing on more lines" — the operational demands, the ownership model, and even how success gets measured shift meaningfully once a copilot moves from proving itself in a controlled setting to being relied on across a plant network where every line has its own quirks and personalities.
Dimension
Pilot Phase
Scale Phase
Scope
Single kiln line or shift crew
Multiple lines, potentially multiple plants
Configuration
Manually tuned to one line's SOPs
Templated configuration reused across sites
Success Metric
Does the copilot perform and get used
Does usage and value hold as scope grows
Ownership
Project team running the pilot
Defined operational owner per plant
Data Foundation
Line-specific historical data
Shared data pipeline across the network
Plants that plan for this shift from the start — building the data pipeline and configuration approach with reuse in mind even during the pilot — reach scale meaningfully faster than plants that only start thinking about templating and shared ownership after the pilot has already proven itself.
Kill or Scale
Making the Expansion Decision Explicit
Every pilot should end at a defined decision point, not fade into an indefinite holding pattern. These are the questions a plant should be able to answer clearly before deciding whether a copilot pilot earns a network rollout.
01
Did the Pilot Hit the KPI Threshold Set Before It Started
Whatever metric was defined during Discovery — troubleshooting time, compliance response time, work order turnaround — needs an honest comparison against the pre-agreed threshold, not a retroactively softened target that makes a mediocre result look sufficient just because the project has already invested time and budget in it.
02
Did Operators Keep Using It Once the Novelty Wore Off
Usage in week one tells you almost nothing; usage in week ten tells you whether the copilot earned a permanent place in the operator's workflow or was only interesting as a novelty during the pilot period, before the pattern settled into whatever it will actually be long term.
03
Does the Use Case Actually Transfer to Other Lines
A use case tied to one line's unique quirks may have succeeded there without having a genuine path to scale — confirming operational similarity across candidate lines before committing to rollout avoids building a program around an exception that won't repeat itself anywhere else in the network.
04
Is There a Named Owner for the Scaled Version
A pilot can run informally under a project team; a scaled deployment needs a defined operational owner responsible for monitoring performance and adoption across the network, or accountability quietly disappears as scope grows.
Field Perspective
The plants that actually scale AI copilots are rarely the ones that ran the flashiest pilot — they're the ones that treated the pilot as a decision-making exercise from the start. They picked a use case with a real, quantifiable payoff, they agreed on what success looked like before anyone touched a keyboard, and they were honest with themselves about adoption numbers instead of only reporting the technical accuracy that looked good in a slide deck. The plants still stuck with a single pilot two years later are almost always the ones that skipped that discipline and hoped the technology would sell itself — and by the time they realize that hope isn't a strategy, they've usually already burned through the organizational patience it takes to try again properly.
Renata Ashworth-Okafor
Digital Transformation Lead · 14 years deploying AI and automation programs across cement and heavy industry plant networks
Common Scale-Up Mistakes
Where Plants Trip Up Between Validate and Scale
Even a well-run pilot with clear, positive results can stumble once the actual scale-up begins. These are the mistakes that show up most often in the transition from a validated single-line success to a functioning network deployment, and each one is avoidable with a bit of planning before rollout starts, rather than being discovered mid-scale-up when the cost of correcting course is considerably higher.
Rolling Out to Every Line at Once
Expanding from one line to the entire network in a single step multiplies the number of things that can go wrong simultaneously — a staged rollout across a handful of lines first surfaces integration or adoption issues while they're still manageable, rather than everywhere at once when there's no time left to react.
Assuming the Pilot's Configuration Transfers Unchanged
Even lines with genuine operational similarity usually have some local differences in SOPs, equipment vintage, or shift structure, and assuming the pilot's exact configuration will work everywhere without adjustment tends to produce a worse experience at the next site than the pilot itself delivered, undermining confidence in the whole program.
Losing Executive Sponsorship Mid-Rollout
A program that had strong leadership backing during the pilot can lose momentum during the less exciting scale-up phase if nobody keeps reporting results back to the sponsors — regular, honest updates on adoption and value keep the program from quietly losing priority against other initiatives competing for the same budget.
Not Budgeting for Ongoing Support
A pilot's success often depends on hands-on support that isn't sustainable at network scale — planning for how each new line gets trained, supported, and troubleshot after go-live is what keeps adoption from quietly declining once the original project team moves on to the next thing on their list.
Common Questions
Frequently Asked Questions
How long should a cement AI copilot pilot run before making a scale decision?
Long enough to see usage past the initial novelty period, which typically means several weeks to a couple of months depending on how frequently the use case comes up in daily operations — a pilot judged only on its first two weeks tends to overstate adoption, since almost anything gets tried out of curiosity at first. Book a demo to set a realistic pilot timeline for your specific use case.
What's the most common reason a technically successful pilot fails to scale?
Missing success criteria defined up front is the most common cause — without a pre-agreed threshold, there's no objective basis for deciding to expand, so the pilot simply continues running in its original corner indefinitely while nobody makes a formal call either way, and momentum quietly drains out of the project. Talk to Solutions Engineering about defining KPIs before your next pilot launches.
Should every cement plant in a network run its own separate pilot?
Not necessarily — if the use case has genuine operational similarity across plants, a single well-validated pilot with a templated configuration approach can often scale directly rather than requiring a fresh pilot phase at every site, which saves considerable time and repeated setup effort across the network. Book a demo to see how configuration templates transfer across plants.
Who should own an AI copilot program once it moves past the pilot stage?
A named operational owner, distinct from whoever ran the original pilot project, should be responsible for monitoring adoption and performance across the network — without that ownership, scaled deployments tend to drift without anyone accountable for whether they're still delivering the value the pilot originally promised. Talk to Solutions Engineering about defining ownership before scaling.
What kind of use case is the safest first pilot for a cement plant new to AI copilots?
A use case with a clearly measurable operational metric, low integration complexity, and genuine similarity across other lines tends to be the safest starting point, since it can prove value quickly without requiring major infrastructure change or a lengthy setup period that delays seeing any real result. Book a demo to identify the right first use case for your plant.
Turn a Successful Pilot Into a Network Rollout
A Deployment Path With Scale Criteria Defined Before You Start
iFactory helps cement plants choose the right first use case, define success up front, and build a path from a single-line pilot to a network-wide copilot rollout.