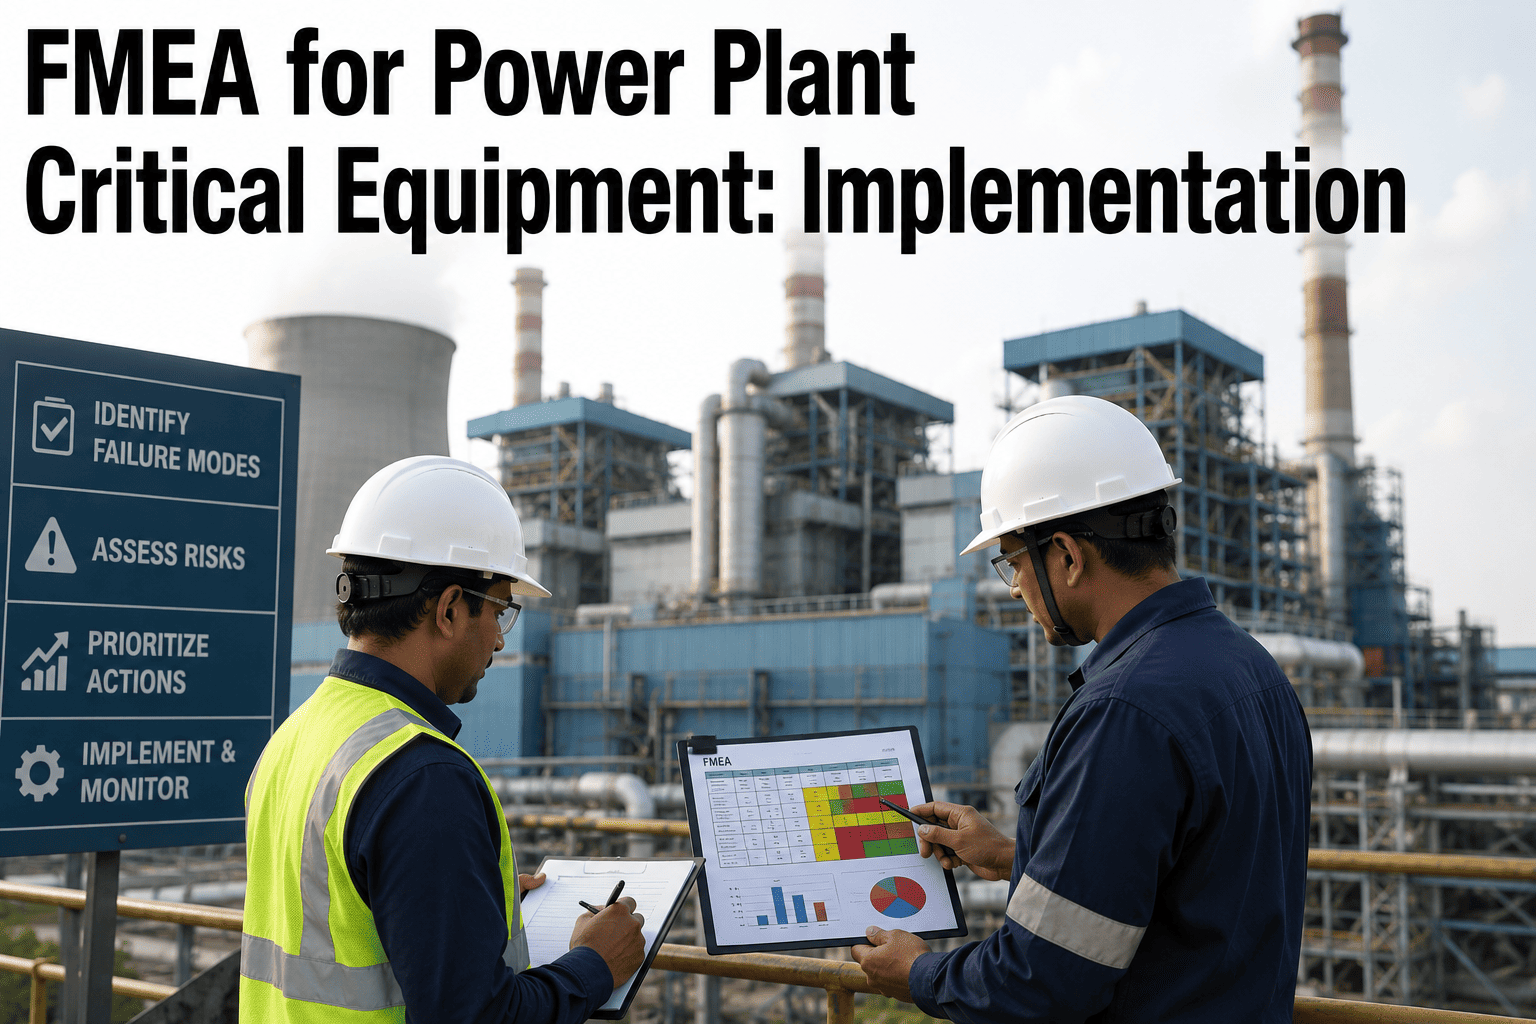
A power plant boiler tube failure is rarely a surprise event in the sense of "nothing indicated it was coming." It is almost always a surprise in the different sense of "the indicators were there, but nobody had scored them, ranked them, or assigned an owner to address them before the failure closed the window." Failure Mode and Effects Analysis (FMEA) is the discipline that closes that gap by forcing a structured examination of every way a critical asset can fail, every downstream effect that failure would cause, and every control the plant currently has (or does not have) to detect it in time. When implemented properly on power-plant critical equipment, FMEA turns unplanned outages from statistically inevitable events into a ranked backlog of risk items being actively worked, and turns reactive maintenance culture into proactive reliability culture. Plants building or refreshing their FMEA program can Book a Demo to see how iFactory tracks failure modes, RPN scores, and action closure across every critical asset in one system.
FMEA · POWER PLANT CRITICAL EQUIPMENT · RPN CALCULATION
FMEA for Power Plant Critical Equipment: Implementation Guide
A working guide to Failure Mode and Effects Analysis for boilers, turbines, transformers, feed pumps, and control systems — how to identify failure modes, calculate Risk Priority Numbers, and convert the analysis into a maintenance strategy the plant actually executes.
What FMEA Actually Is (And What It Is Not)
FMEA is a structured, inductive analysis: for each critical asset, the team enumerates every way that asset can fail, describes what happens downstream when it does, identifies what would cause each failure mode, and scores three separate dimensions of risk — how bad the effect is, how likely the cause is, and how reliably existing controls would detect the failure before it propagates. Multiplied together, those three scores produce a Risk Priority Number that lets the plant rank thousands of potential failures against each other and prioritize where mitigation effort actually goes. RPN values range from 1 as the theoretical minimum to 1000 as the theoretical maximum, with higher values indicating higher relative risk.
What FMEA is not: it is not a probabilistic reliability calculation, it is not a substitute for root-cause analysis after a failure has already happened, and it is not — despite how it is sometimes presented — a document that gets written once and filed. The most common failure mode of the FMEA program itself is treating the analysis as a one-time deliverable rather than a living record that updates every time a failure event provides new occurrence data, every time a new control is implemented that changes detection scoring, and every time equipment is modified in a way that changes severity of potential effects. Modern FMEA standards (AIAG-VDA and IEC 60812) increasingly favor Action Priority (AP) tables over raw RPN scoring precisely because RPN alone can mask high-severity, low-frequency risks that need attention regardless of their multiplied score. The value of FMEA is in the disciplined thinking process it forces on the cross-functional team; the RPN spreadsheet is a byproduct, not the point. A plant that goes through the FMEA workshop rigorously and never opens the spreadsheet again still captures most of the reliability benefit; a plant that produces a beautifully formatted spreadsheet without doing the workshop discipline captures almost none.
The Three Dimensions: How S, O, and D Actually Get Scored
The credibility of every RPN in an FMEA depends entirely on how consistently the team scores Severity, Occurrence, and Detection. Every score is on a 1-to-10 scale, but the calibration of that scale matters more than the number itself. A team that scores every severity as 8 and every occurrence as 6 will produce a spreadsheet full of RPNs that all look the same and prioritize nothing. The scales below are the reference calibration most power-plant FMEA programs converge on, drawing from AIAG-VDA, IEC 60812, and industry-specific reliability standards adapted for power generation contexts.
SEVERITY (S)
Impact of the failure effect
9-10
Catastrophic — safety hazard, plant-wide outage, regulatory violation
7-8
Major — unit outage, extended derate, significant repair cost
4-6
Moderate — partial function loss, planned repair required
1-3
Minor — noticeable but no operational impact
OCCURRENCE (O)
Likelihood of the cause happening
9-10
Very high — failure is nearly inevitable within the interval
7-8
High — repeated failures common on similar assets
4-6
Moderate — occasional failures documented in history
1-3
Low — rare failures, mature design and process
DETECTION (D)
Ability of controls to catch it
9-10
Very low — failure reaches the customer or effect undetected
7-8
Low — detection only through downstream consequence
4-6
Moderate — detected through periodic inspection or condition monitoring
1-3
High — automated real-time detection with immediate alarm
The most common calibration error in power-plant FMEA is inverting the Detection scale — assigning high numbers to strong detection controls because "10 sounds better than 1." The convention is the opposite: a Detection score of 10 means the plant has no reliable way to catch the failure before its effect occurs, which is exactly why that score inflates the RPN and pushes the item up the mitigation queue. Getting the scoring convention right on the first workshop is worth the extra half-hour of team calibration. Two related traps show up on almost every first-time FMEA. The first is scoring severity based on the current control environment rather than on the effect itself — severity is defined by what happens if the failure occurs, independent of any control that might prevent it; controls belong in the Detection column, not the Severity column. The second is scoring occurrence based on how frequently the effect has been observed rather than how frequently the cause could occur — occurrence tracks the cause frequency, not the historical incident count that already reflects existing detection and prevention.
FMEA TRACKING · RPN CALCULATION · ACTION CLOSURE
Stop Managing FMEAs in Spreadsheets That Nobody Updates
iFactory holds every failure mode, cause, effect, control, and RPN score in one live record — updated when history changes, when controls improve, when equipment is modified — and drives the mitigation actions the analysis produces directly into your work-order backlog.
The Seven-Step Implementation Workflow
FMEA implementation on power-plant critical equipment follows a specific sequence. Skipping steps — especially the criticality selection at the front and the action-closure loop at the back — is the single most common reason FMEA programs stall out and produce spreadsheets that never drive maintenance strategy change. The seven-step workflow below reflects what production FMEA programs actually run, and the sequence matters: each step generates inputs the next one depends on, and shortcuts taken early compound into unusable outputs at the end.
01
Select Critical Equipment Scope
Not every asset warrants an FMEA. Start with equipment whose failure would cause safety hazard, environmental release, plant-wide outage, or major repair cost — boilers, main turbines, main transformers, feedwater pumps, main control systems. Non-critical items get abbreviated analysis or none at all.
02
Assemble the Cross-Functional Team
Operations, maintenance, engineering, and reliability disciplines all bring failure knowledge the others do not have. A team missing operations misses "how it actually gets run"; missing maintenance misses "what fails when it runs that way"; missing engineering misses design intent.
03
Enumerate Failure Modes for Each Function
Break each asset into functions (delivering feedwater at pressure X, transferring load at ratio Y), then list every way each function can fail. Draw on plant failure history, industry databases, OEM documentation, and team experience. Miss failure modes here and no downstream analysis recovers them.
04
Identify Causes, Effects, and Existing Controls
For each failure mode, document what could cause it (mechanism), what happens if it occurs (effect on system, plant, safety, environment), and what controls currently exist to prevent it or detect it before the effect propagates. Existing-control identification directly drives the Detection score.
05
Score Severity, Occurrence, and Detection
Apply the calibrated 1-10 scales consistently across the entire analysis. Score by team consensus with a facilitator who challenges outliers. Multiply the three scores to produce the RPN for each row. Document the reasoning behind each score to support later review.
06
Prioritize and Assign Actions
Sort the analysis by RPN and by severity independently. High-severity items get action regardless of RPN; high-RPN items get action even when severity alone would not have triggered it. Actions target either reducing occurrence (design change, upgrade, replacement) or improving detection (condition monitoring, alarm addition).
07
Close Actions and Recalculate RPN
Every assigned action gets an owner, a due date, and a verification step. When the action closes, the affected S/O/D scores update and the revised RPN records the risk reduction. A 40 percent RPN reduction on the top-10 high-priority items is the typical target after the first improvement cycle.
Power Plant Critical Equipment: Where FMEA Delivers Most
Not every FMEA delivers equal value. On thermal, nuclear, and renewable power plants, five equipment categories account for the majority of both the analysis effort and the risk reduction FMEA produces. Understanding what typical failure modes look like on each — and what makes them high-RPN candidates — is what sequences the FMEA program for maximum early impact. The published research base on power-plant FMEA is particularly deep for boilers and transformers, giving new programs a reference library of failure modes that other plants in the same equipment class have already documented, scored, and mitigated. Sequencing FMEA implementation to start with equipment categories where this reference base is strongest is typically the fastest path to demonstrable risk reduction and program credibility with plant leadership.
CATEGORY 01
Boilers & Steam Generators
Water-tube boilers are the historically dominant subject of power-plant FMEA studies. Critical failure modes include short-term overheating, localized flue-gas flow disruption, tube corrosion and erosion, and drum-level control system faults. Failures propagate to unit outage and, in worst cases, catastrophic tube rupture — driving severity scores of 8-10 for many boiler failure modes.
CATEGORY 02
Steam & Gas Turbines
Turbine FMEA covers blade fatigue, bearing degradation, lube-oil system contamination, governor and control-valve failures, and vibration-induced damage. Nuclear-plant steam turbine FMEA has driven hybrid analysis models incorporating multi-criteria decision-making to handle the interdependencies between failure modes that raw S×O×D scoring can flatten.
CATEGORY 03
Power Transformers
Studies across large transformer populations consistently identify three failure-prone subsystems: windings, on-load tap changers (OLTC), and bushings. Failure modes include insulation degradation, dielectric breakdown, cooling system failure, and OLTC contact wear. RPN scoring guides between run-to-failure, condition monitoring, and preemptive replacement strategies for each identified mode.
CATEGORY 04
Feedwater & Coolant Pumps
High-pressure feedwater and coolant pumps are single-point-of-failure assets on many plants. Failure modes include seal failure, bearing wear, cavitation damage, motor winding degradation, and coupling misalignment. Detection scoring is often the biggest opportunity here — many pump failures are detectable through vibration monitoring long before they force an outage.
CATEGORY 05
Control & Protection Systems
DCS, protection relays, and safety-instrumented systems have failure modes that combine hardware, software, and human-factor causes. FMEA on these systems often produces the highest-severity findings on the plant — a protection system that fails to trip on a genuine fault has effects that dwarf most mechanical failures — driving mitigation to redundancy, testing frequency, and diagnostic coverage.
CATEGORY 06
Fuel Handling & Auxiliary Systems
Coal handling, ash disposal, cooling towers, and auxiliary steam systems produce failure modes that often are lower severity individually but higher occurrence — coal dust self-ignition risk, ash-handling erosion, cooling-tower fill degradation. High-occurrence, moderate-severity items still generate meaningful RPNs and drive real reliability improvement.
The RPN Action Ladder: What Score Triggers What Response
RPN is a ranking tool, not an absolute risk measure — but every FMEA program needs practical thresholds that convert scores into actions. The ladder below represents the response tiers most mature power-plant FMEA programs use, with the important caveat that any failure mode scoring 9 or 10 on Severity alone requires action regardless of where its RPN lands. The exact threshold values are less important than the discipline of having thresholds documented, agreed by the reliability leadership team, and consistently applied across every FMEA in the plant's portfolio.
RPN 200-1000
Critical Priority — Immediate Action Required
Executive-level ownership, tracked to weekly closure. Mitigation strategy typically combines design change, procedural change, and detection enhancement. Reassessment scheduled within 30 days of action closure to verify RPN reduction.
RPN 100-199
High Priority — Mitigation Plan Required
Engineered mitigation plan with defined budget and schedule. Actions typically target reducing occurrence through design improvement or improving detection through added condition monitoring. Reassessment within the current fiscal year.
RPN 50-99
Moderate Priority — Planned Improvement
Included in planned maintenance strategy updates. Actions typically procedural — added inspection frequency, updated PM task lists, revised operator procedures. Reassessed at next scheduled FMEA review cycle.
RPN 1-49
Low Priority — Monitor
No dedicated mitigation action required at current scoring. Documented in the FMEA record and reviewed at the next full cycle for any change in occurrence history or detection capability that would elevate the item.
SEV 9-10
Severity Override — Always Actionable
Any failure mode with Severity rated 9 or 10 requires mitigation action regardless of RPN. High severity combined with low occurrence and good detection still produces a low RPN — but a catastrophic event that only happens rarely is still a catastrophic event when it happens.
The severity override at the bottom of the ladder is the single most important guardrail in FMEA practice. A protection-system failure that would cause a catastrophic effect but has strong existing detection and low historical occurrence can produce an RPN below 100 while remaining exactly the kind of risk the plant cannot tolerate. The AIAG-VDA FMEA Handbook now advocates Action Priority tables that consider Severity, Occurrence, and Detection combinations directly rather than relying solely on multiplied RPN — reflecting exactly this concern. Regulators and insurers reviewing an FMEA program will look specifically at whether high-severity items are being managed independently of their RPN score, and a program that lets severity-9 items slip below action threshold because their multiplied RPN is low will not survive that review. Building the severity override into the process from day one, and documenting the reasoning behind action decisions on each high-severity item, is what turns the FMEA into a defensible risk management record rather than an internal exercise.
Frequently Asked Questions: FMEA Implementation for Power Plants
How long does an initial FMEA on a critical asset like a boiler actually take?
A full FMEA on a water-tube boiler with a competent cross-functional team typically consumes 40 to 80 hours of team time spread across four to eight working sessions, depending on boiler complexity and how much prior failure history is documented. The first FMEA a plant runs is always the slowest because the team is also calibrating on scoring conventions; subsequent FMEAs on similar assets close faster because the scoring reference is already established. Plants building a program can
Book a Demo to see how iFactory templates accelerate that first analysis.
Should we use RPN or the newer Action Priority (AP) methodology?
Both are defensible if used correctly. RPN is simpler to explain and calculate, works well for early-stage risk ranking, and remains the most commonly cited FMEA output in power-industry literature. Action Priority — introduced in the AIAG-VDA handbook — handles high-severity, low-occurrence items more robustly by considering S, O, and D combinations directly rather than multiplying them. Most mature programs use both: RPN for ranking and communicating the analysis, and severity thresholds or AP tables as the actual action trigger. The critical rule is that severity alone must always be able to override a low RPN.
How often should FMEAs be reviewed and updated?
The formal review cycle for power-plant FMEAs is typically annual, with mid-cycle updates triggered by specific events: a documented failure event that adds new occurrence data, an equipment modification that changes potential severity, a new control implementation that improves detection, or a regulatory or standards change affecting the analysis. FMEAs that only get touched at the annual review inevitably drift out of alignment with plant reality — the event-triggered mid-cycle update is what keeps the record living rather than historical.
What is the connection between FMEA and root-cause analysis after an actual failure?
FMEA is proactive — done before failures happen to prevent them; RCA is reactive — done after failures happen to explain them. But the two disciplines are tightly linked in practice. Every RCA output should feed back into the relevant FMEA: the failure mode that actually occurred should appear on the FMEA (if it does not, the FMEA missed it), its occurrence score should update to reflect that it did in fact happen, and the detection score should be reassessed against what actually caught it or failed to. RCAs that do not close back into FMEA updates leave the analysis stale.
Can FMEA output actually drive maintenance strategy, or is it a compliance document?
This is exactly the distinction between FMEA programs that produce value and FMEA programs that produce paperwork. A properly implemented FMEA output drives specific maintenance strategy decisions: which items get condition-based monitoring versus time-based PM versus run-to-failure, which items get redundancy added, which items get inspection frequency increased, and which items get design modification proposed. When those decisions are being made off the FMEA rather than off historical convention, the program is working. When they are being made independently of the FMEA, the analysis is a compliance artifact. Plants building the connection between FMEA output and executed maintenance strategy can contact
iFactory Support for integration guidance.
FMEA IMPLEMENTATION · RPN TRACKING · MAINTENANCE STRATEGY
Turn FMEA From a Binder on a Shelf Into a Live Risk-Reduction Program
iFactory holds every failure mode, cause, effect, and control in one connected record — updates S/O/D scores as history and controls change, drives assigned actions into the work-order backlog, and shows RPN reduction over time as evidence the program is actually shrinking risk.