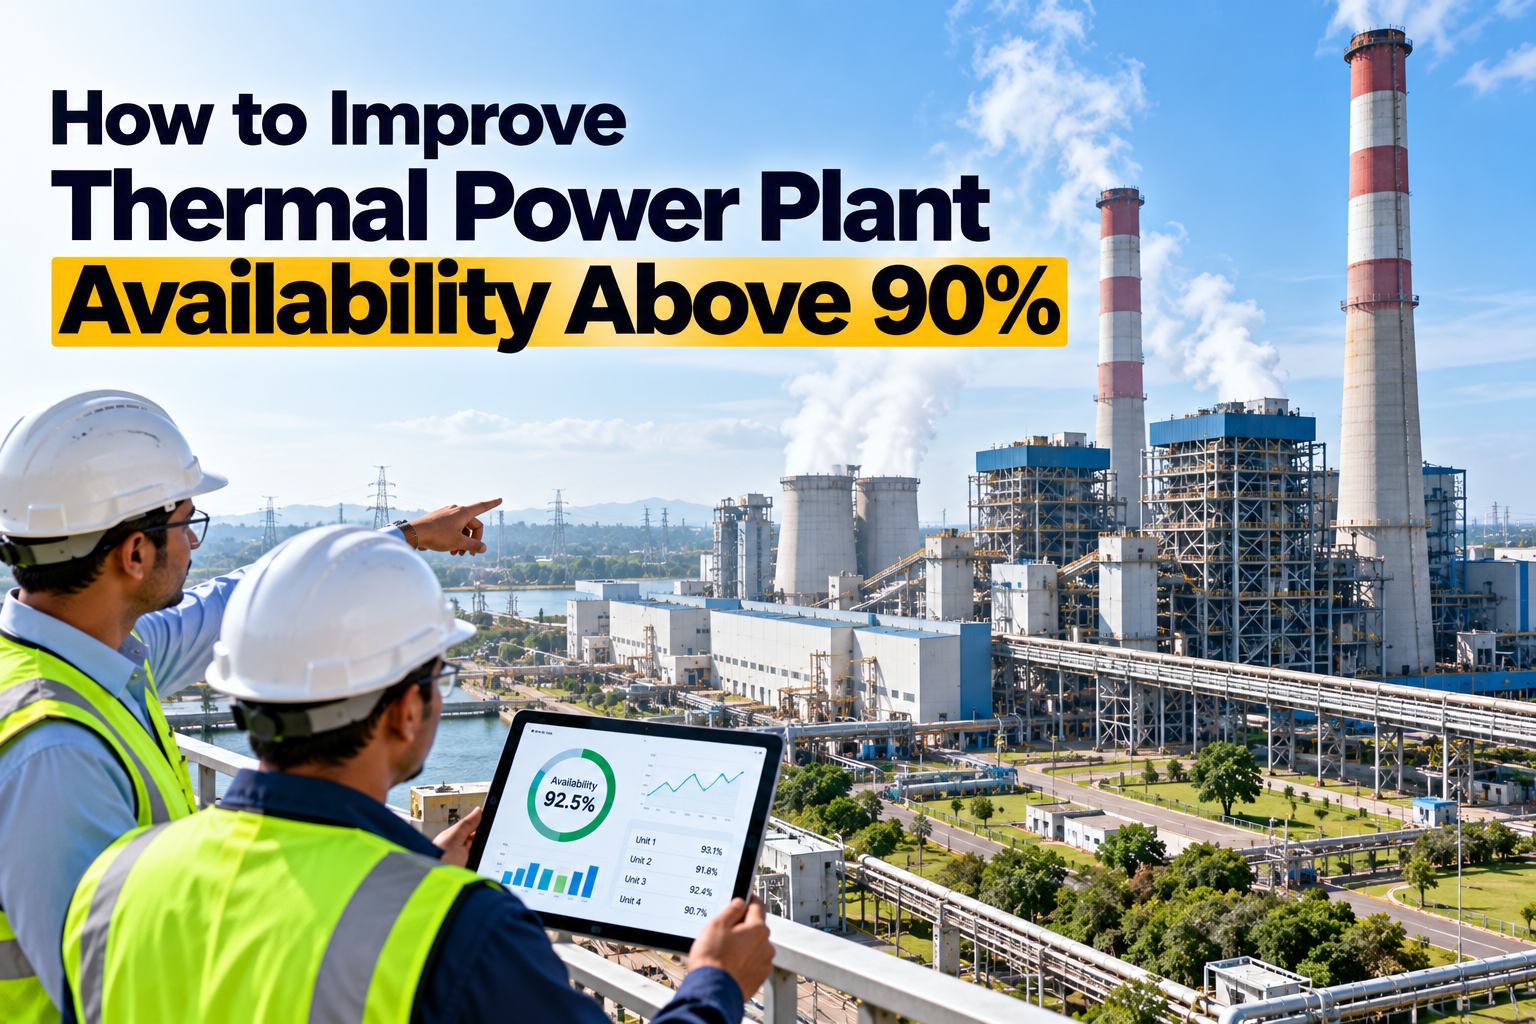
Availability is the one headline number a thermal plant controls. Load factor depends on dispatch, coal and demand; availability depends on how many hours the unit is ready, and at what capacity. Many stations sit four or five points below what the best-run units achieve, and the gap is rarely one big failure — it is boiler tube leaks, auxiliary trips, partial load restrictions and outages that overrun. This guide sets out a structured way to recover those hours without major capital spend, and shows where iFactory's on-site AI fits. To apply it to your own unit data, book an availability review.
From 85% to Above 90% Availability — by Recovering Hours You Already Own
The path above 90% is an accounting exercise before it is an engineering one: code every lost hour, rank the causes, and work the few that repeat. iFactory adds early warning from your DCS and historian data, so that forced outages become planned work.
- Every lost hour coded to a cause
- Early warning on tubes, fans, mills and pumps
- Planned outages that finish on time
Availability Is the Number the Plant Controls
Three numbers get quoted as if they were the same thing. Plant load factor measures energy sent out against capacity, and falls when the grid does not schedule the unit. Availability measures whether the unit was ready. Equivalent availability goes further and counts partial restrictions — a unit running at 420 MW of 500 is available, but not fully. In India, tariff recovery is tied to the plant availability factor, with a normative level of 85% for thermal stations, which is why the last few points matter commercially as well as operationally. The definitions here follow IEEE 762, the standard behind most reporting schemes. Our power specialists can align them with the way your station reports today.
Where the Hours Go: an Illustrative 500 MW Unit
Take a 500 MW unit over a year of 8,760 hours. It spends 500 hours on planned outage and 480 on forced outage, and loses the equivalent of 280 full-load hours to partial restrictions. Its availability factor is 88.8%, its equivalent availability 85.6% and its forced outage rate 5.8%. The first step is not a project. It is making sure every one of those 1,260 hours carries a cause code that an engineer would agree with. Stations that do this usually find a handful of causes repeating — the boiler tube literature makes the same point, describing the failures as typically repetitive. To build this loss tree from your own outage log, book a data session.
Build the Loss Tree for One Unit in Six Weeks
Choose one unit. We connect its DCS and historian data, code two years of outage and restriction hours with your engineers, rank the causes, and switch on early warning for the equipment at the top of the list.
Six Levers That Do Not Need Major Capital
None of these is new, and none needs a turbine retrofit or a new boiler. What they need is data that is trusted, attention that is sustained, and warning early enough to choose the timing. The hours shown are the same illustrative unit, and they add up to the 420 that move it from 85.6% to 90.4%. Some causes do need capital — a pressure-part section at end of life, for one — and the loss tree is what shows which. Our reliability engineers can go through each lever against your unit.
Boiler Tube Leaks: the First Place to Look
Boiler and HRSG tube failures have been described as the primary availability problem for fossil plants, with availability loss averaging around 3% for coal units above 200 MW. The reason the number stays high is habit: the priority after a leak is to get back on load, so the tube is repaired and the mechanism is never named. The same zone fails again a few months later. A tube leak programme breaks that cycle with four steps. To review your tube failure history with us, book a boiler review.
Map every failure
Record each leak by elevation, wall, tube number, date and operating hours. A map of ten years of failures shows the zones at a glance.
Name the mechanism
Erosion from fly ash or soot blowers, long-term overheating, corrosion fatigue and weld defects each need a different remedy. A sample goes to the laboratory.
Treat the zone
Shields, soot blower pressure and sequence, combustion tuning, cycle chemistry, or replacement of a panel at the next planned stop.
Watch between outages
Metal temperatures, make-up water consumption, furnace draft and acoustic signals are tracked for the first signs of a leak.
Why early detection matters: a small leak found early can be taken out in a planned weekend shutdown. Left to grow, the steam jet cuts neighbouring tubes, the repair is larger, and the unit picks its own time to come off.
Turning Forced Outages Into Planned Ones
Most auxiliary failures give notice. A bearing warms over days, a mill draws more current for the same coal flow, an air preheater's differential pressure creeps up. The signs are in the DCS, but nobody can watch several thousand tags against load and ambient conditions by eye. Condition monitoring does that watching, and what it buys is the choice of timing: a repair in a low-demand window or the next planned stop, instead of a trip at peak.
Shorter, Cleaner Planned Outages
A planned outage hour counts against availability exactly as a forced one does. In the illustrative unit, 60 of the 500 planned hours were overrun: work discovered after the unit was opened, and a start-up that took two attempts. Neither is solved by working faster. Both are solved before the outage begins. Our outage planners can review your last overhaul against its plan.
Scope frozen early
Work lists closed weeks ahead, with late additions needing a named approval. Late scope is the commonest cause of overrun.
Condition data sets the scope
What the monitoring has shown since the last outage decides what is opened, so fewer surprises are found on day three.
Critical path owned daily
One person answers for the critical path each day, and a slip is raised the day it happens, not at the weekly meeting.
Start-up is part of the outage
Commissioning checks, protection tests and the light-up sequence are planned and resourced like any other outage job.
What the AI Adds in the Control Room
A power station already records far more data than its engineers can read. iFactory's models run on a GPU server inside the plant, learn the normal behaviour of each machine across load, ambient and coal conditions, and raise an alert when behaviour departs from it — with the evidence, and with similar past events from the same station.
- Early warning in context. A bearing temperature is judged against load and ambient, not against a fixed alarm limit that only trips when it is too late.
- Precedents from your own history. Each alert is matched with earlier events that looked the same and what they led to.
- Trip analysis. The sequence of events before a trip is assembled automatically, so the root-cause meeting starts with facts.
- Questions in plain language. Shift engineers ask about a machine, a trend or an outage and get the data behind the answer.
Reactive, Calendar-Based and Condition-Based Operation Compared
The difference between a unit at 85% and one above 90% is rarely the hardware. It is how early problems are seen and who chooses when the unit comes off.
Delivered as a Turnkey AI System — Hardware and Software Together
iFactory ships as a complete bundle: a pre-configured NVIDIA AI server, racked and ready, with the analytics and AI models pre-loaded. Rack it, plug in power and Ethernet, and the AI is live on your network — plant data stays inside the station. Our team handles cabling, network setup, read-only connections to your DCS, historian, PLC and SCADA systems, operator training and 24×7 remote monitoring. For a scoped proposal, book a deployment call.
Ship, network and data
Server delivered and racked. DCS and historian connected. Two years of operating data and the outage log loaded. Lost hours coded with your engineers.
Model training and pilot
Models trained on the unit's own history. Early warning live on the top-ranked equipment, with alerts reviewed weekly against what the plant found.
Go-live and training
Coverage extended across the unit. Shift, maintenance and planning teams trained. Loss tree and alert review handed over to your operations group.
Frequently Asked Questions
What is a good availability for a coal-fired unit?
It depends on age, duty and how the unit is cycled. In India the tariff norm for thermal stations is 85%, and well-run units report above 90%. The wider trend is against ageing fleets: NERC reported a 14.1% equivalent forced outage rate for North American coal units in 2025, citing units over 40 years old that were not designed for regular cycling.
What is the difference between availability and plant load factor?
Availability measures whether the unit was ready to generate. Plant load factor measures what it actually generated, which also depends on dispatch, demand and fuel. A unit can have high availability and low load factor if the grid does not schedule it.
What is usually the biggest cause of lost availability?
On coal-fired units, boiler tube failures are most often at the top, followed by auxiliaries such as fans, mills and pumps. But the answer for your unit is in your own outage log, which is why coding every lost hour comes first.
Can availability really improve without major capital spend?
A large part of the gap usually can, because it comes from repeat failures, late detection, partial restrictions and outage overruns. Some causes do need capital, such as a pressure-part section at end of life. The loss tree separates the two so that capital goes only where practice cannot fix the problem.
How does AI help, and what does it not do?
It watches operating data continuously and flags equipment that is behaving differently from its own normal pattern, early enough to plan the work. It does not repair anything and does not replace engineering judgement. Its value is the time it gives the plant to choose when to act.
Does it work with our existing DCS and historian?
iFactory reads data from control systems and historians over standard industrial interfaces, on a read-only basis, and does not write to the control system. The exact connection method is confirmed for your equipment during scoping.
How long does deployment take, and what do we need to provide?
A typical unit is live in 6–12 weeks. You provide rack space, power, an Ethernet connection, read access to the DCS or historian, the outage and restriction log for the last two years, and an operations lead for the pilot. iFactory supplies the pre-configured NVIDIA AI server, software, integration and training. To scope your station, contact our project team.
Recover the Hours Before You Buy the Hardware
One turnkey system — NVIDIA AI server, analytics, integration and training — delivered and live inside 12 weeks. Start with the unit that has the longest forced outage log.
- 1Planned, forced and partial-loss hours for two years
- 2The forced outage log, with causes
- 3Boiler tube failure history by location
- 4The trip list, with root causes where known
- 5Last overhaul: planned against actual duration