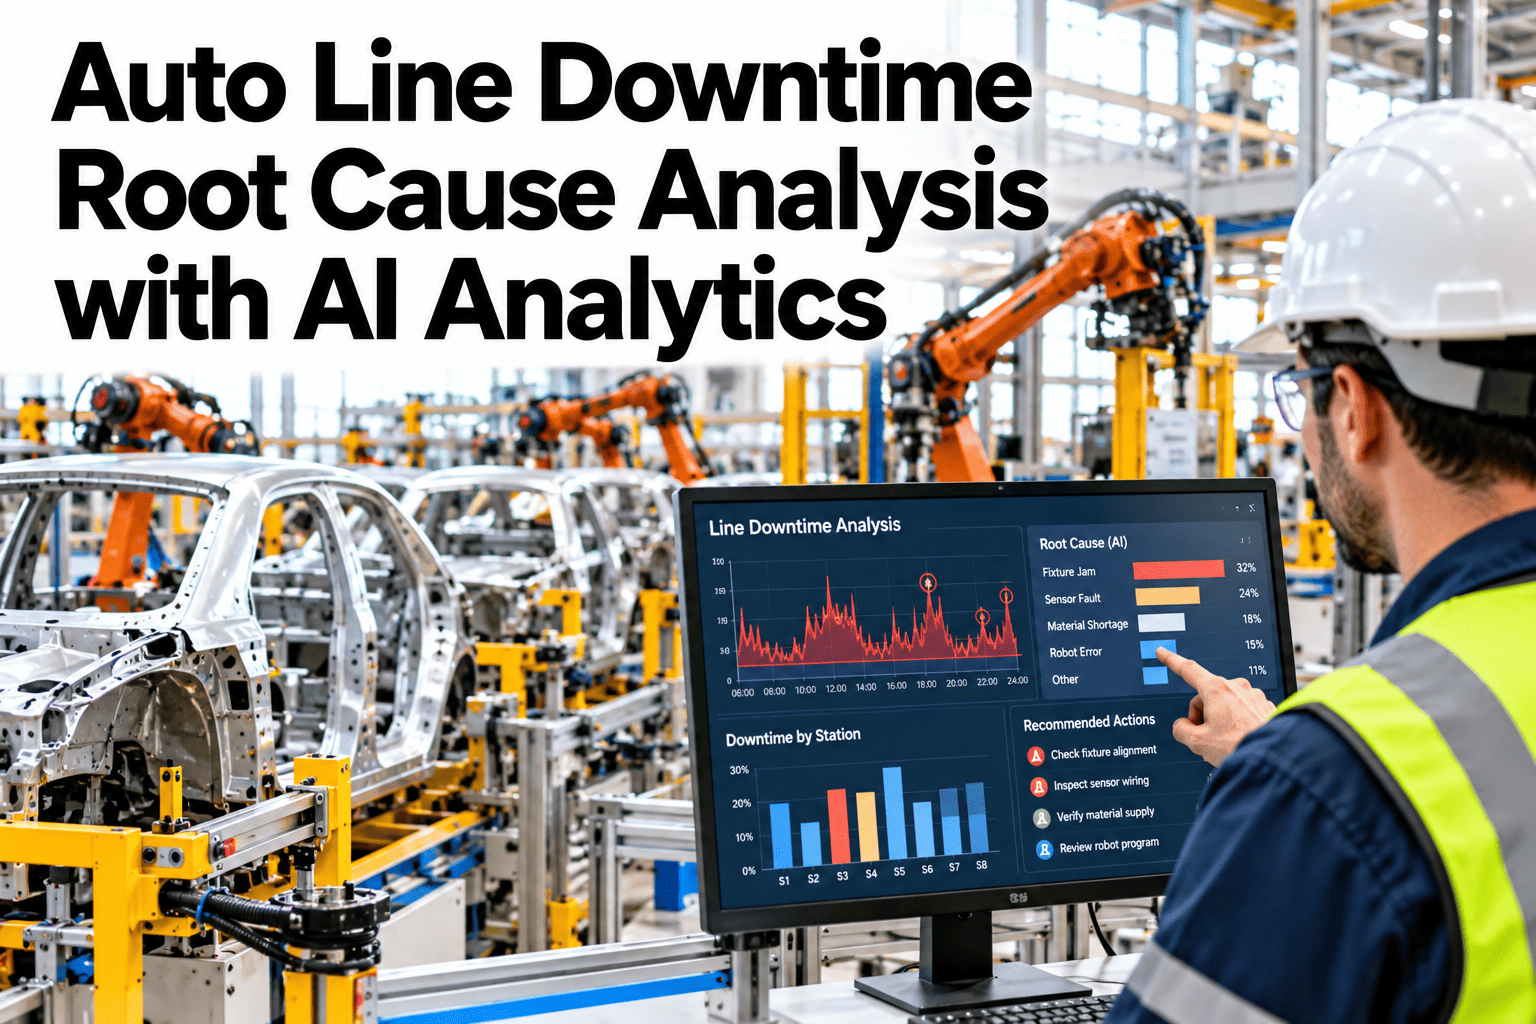
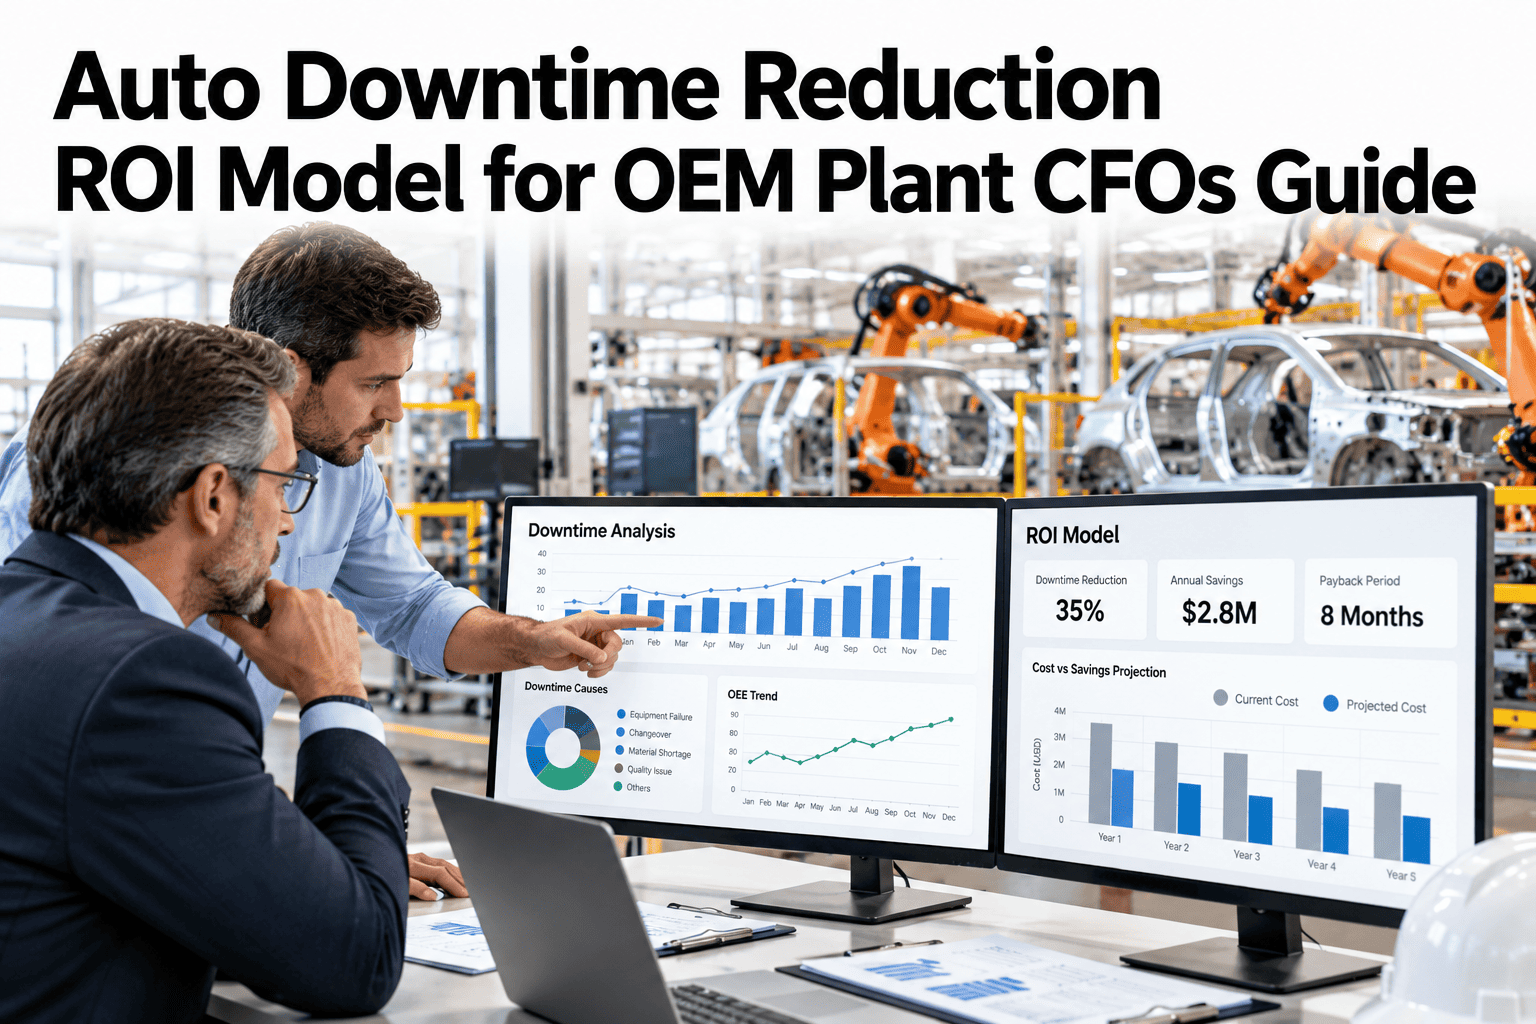
Most assembly line downtime reviews focus on the handful of catastrophic failures that shut a line down for hours, because those are the easiest to notice and the easiest to justify a project around. The real cost usually sits somewhere else, in dozens of short unplanned stops spread across a shift, each only a few minutes long but collectively eating more production time than the rare big failure ever does. A structured playbook built around identifying your actual critical few causes, tracking MTBF by station, and training operators to respond fast typically cuts unplanned downtime by a meaningful margin within a single quarter. If you want to see this playbook mapped against your own line's downtime log, you can walk through a downtime review with our team.
Downtime reduction playbook, 2026
A Practical Playbook for Cutting Unplanned Assembly Line Downtime
Identify your critical six failure causes, track MTBF by station, and train operators for rapid response, the three moves behind most of the downtime reduction auto plants see in 2026.
Typical results from applying this playbook
Unplanned downtime reduction25-40%
Share of downtime from micro-stopsOften 50%+
Causes behind most lost timeUsually just 6
Time to first measurable gainOne quarter
Why big failures aren't the real target
Why Micro-Stops Cost More Than the Dramatic Shutdowns
A single four-hour breakdown feels like the obvious problem to fix, but a line losing two minutes thirty times a shift to small unplanned stops is bleeding more total production time and barely shows up on anyone's radar.
Invisible in summaries
Micro-stops rarely trigger a formal incident report, so they never make it into the usual downtime review.
Normalized by operators
A short stop that clears itself quickly gets treated as routine rather than logged as a real event.
Compounding across stations
A two-minute stop at one station ripples downstream, creating starvation or blocking at the next station too.
No root pattern visible
Without aggregating micro-stops by cause, the same recurring issue looks like unrelated noise each time.
Step one
Checklist: Finding Your Critical Six Downtime Causes
Before any fix makes sense, the first step is identifying which six or so causes actually account for most of your lost time. Work through this checklist against your own downtime log.
✓
Pull every logged stop event, including micro-stops under five minutes, for the last full quarter.
✓
Group stops by station and by root cause category rather than treating each event individually.
✓
Rank causes by total accumulated minutes lost, not by number of occurrences alone.
✓
Confirm the top causes account for the majority of total lost time before committing resources.
✓
Check whether any top cause clusters around a specific shift, operator, or equipment age.
✓
Separate causes that are mechanical from ones that are process or training related.
✓
Assign a clear owner to each of the top six causes before moving to the fix stage.
✓
Set a baseline MTBF figure for each critical cause so improvement can actually be measured later.
✓
Confirm whether each cause is new this quarter or has appeared in a previous critical six ranking.
✓
Check if any critical cause correlates with a specific product variant or changeover sequence.
✓
Verify that stop-time data is pulled from the same source consistently across all stations being ranked.
✓
Share the ranked list with station supervisors before finalizing it, since floor context often sharpens the ranking.
Step four
Checklist: Confirming Rapid-Response Readiness
Once response cards and training are in place, this checklist confirms the readiness is actually holding up on the floor rather than just existing on paper.
✓
Every operator on a station can locate the response card for that station's top causes without searching.
✓
Response cards are current with the latest critical six ranking, not an outdated version from a prior quarter.
✓
A timed drill has been run on each top cause within the current quarter, not just at initial rollout.
✓
Average stop duration by cause is reviewed monthly, with any upward drift flagged for a refresher.
✓
New hires receive response card training before their first unsupervised shift on a critical-cause station.
✓
A clear escalation path exists for any stop that a response card does not resolve within its expected time.
Step two
MTBF Improvement Tactics by Failure Type
Once the critical six are identified, the right improvement tactic depends heavily on whether the cause is mechanical, process-driven, or tied to training.
| Cause type | Typical MTBF pattern | Primary tactic | Expected impact |
| Sensor misalignment |
Gradual decline between calibrations |
Shorten calibration interval on flagged stations |
Meaningful MTBF gain within weeks |
| Fastener or tooling wear |
Sudden drop after a wear threshold |
Condition-based replacement instead of fixed schedule |
Fewer surprise stops, more predictable spares use |
| Material jam or feed issue |
Clustered around specific material batches |
Tighten incoming material spec checks |
Reduced clustering of micro-stops |
| Operator response delay |
Stop duration longer than the fault itself needs |
Rapid-response training on the specific fault type |
Shorter stop duration even if frequency is unchanged |
Notice that two of these four tactics do not require any new equipment at all, which is why the critical six exercise so often pays off faster than teams expect.
Identify Your Own Critical Six This Quarter
Share a recent quarter of downtime logs and we will help rank your actual top causes by total lost time.
Step three
Building Rapid-Response Training Around the Top Causes
Once the critical six and their tactics are set, the fastest remaining win is cutting how long each stop actually lasts once it happens.
1
Build a short response card for each critical cause, covering the first three checks to run.
2
Train operators on the response card for the causes most common at their specific station.
3
Run a timed drill on each cause type so response speed is measured, not assumed.
4
Track average stop duration by cause monthly to confirm the training is actually shortening response time.
Score yourself
Where Does Your Line Stand on This Playbook Today
Use this quick self-check to see which stage of the playbook is most worth tackling first on your own line.
Critical six identified
If your top causes by total lost minutes are not currently ranked and owned, this is your starting point.
MTBF tracked by cause
If MTBF is only tracked plant-wide rather than by specific failure type, tactics cannot be properly targeted.
Response cards in place
If operators are improvising their response to common faults, stop duration is longer than it needs to be.
Monthly review cadence
If downtime causes are reviewed only annually, drift between reviews goes uncorrected for too long.
Expert review
What iFactory Automotive Specialists See Across Assembly Lines
iFactory automotive specialists who have reviewed downtime logs across multiple assembly plants consistently find that the critical six causes shift slightly from plant to plant, but operator response delay on a known fault type is almost always one of them, which makes rapid-response training one of the highest-return tactics available.
They also note that plants seeing the strongest results from this playbook are the ones that revisit their critical six quarterly rather than once, since fixing the top causes naturally promotes a new set of causes into that top position over time.
Frequently asked questions
What Plant Managers Ask Before Running This Playbook
How much historical downtime data do we need before starting the critical six exercise?
A full quarter of logged stops, including micro-stops, is usually enough to rank causes reliably, though a full season gives a more stable picture if seasonal production mix varies.
Discuss your data starting point with our team.
Do micro-stops under a minute need to be logged for this to work?
Capturing stops down to even thirty seconds meaningfully improves the ranking, since very short stops are often the most frequent and most collectively costly category.
Ask about micro-stop logging setup for your current equipment.
How often should the critical six list actually be revisited?
A quarterly review is the common cadence, since fixing the current top causes typically promotes new ones into the ranking faster than an annual review would catch.
Set a review cadence that fits your production calendar.
Can this playbook work without automated downtime tracking already in place?
Yes, a manual logging process can produce a usable critical six ranking, though automated tracking captures micro-stops far more reliably than manual entry typically does.
Ask about tracking options for your current setup.
What is a realistic timeline to see the 25 to 40 percent reduction mentioned?
Plants that work through all three stages, identification, MTBF tactics, and rapid-response training, typically see measurable reduction within a single quarter, with the full range achieved over two to three quarters.
Discuss a realistic timeline for your line.
Stop losing shifts to small, repeated stops
Run the Full Downtime Reduction Playbook on Your Line
Book a session with iFactory AI to identify your critical six causes, set MTBF tactics, and build rapid-response training for your assembly line.