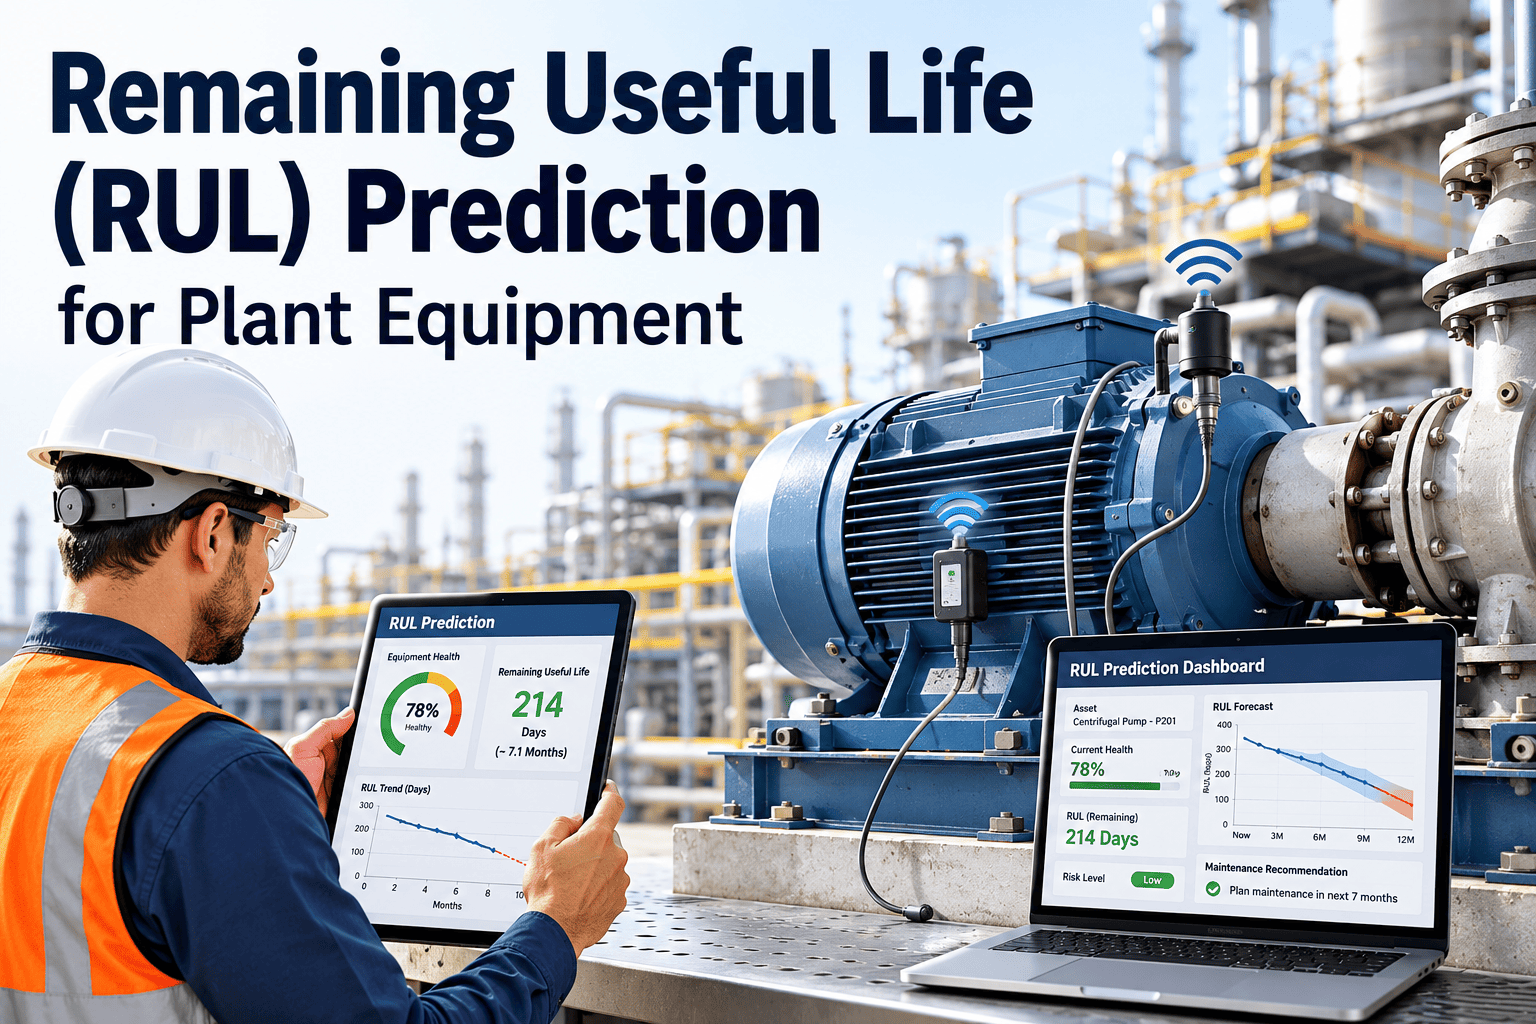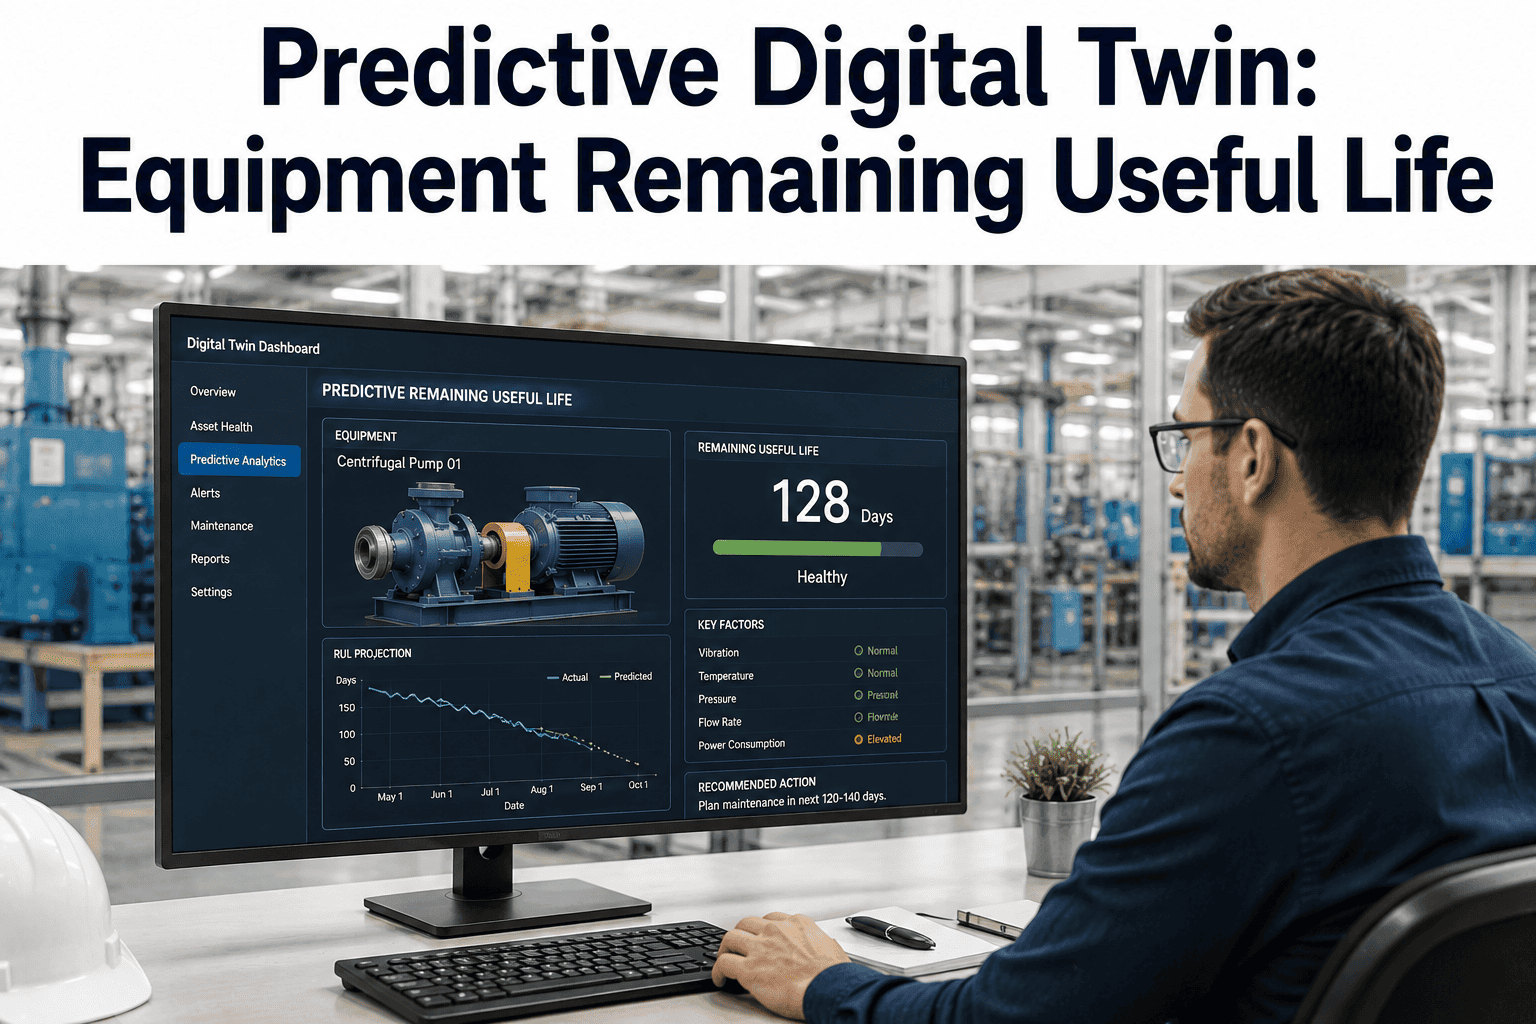
Remaining useful life estimation is the single most financially impactful capability a predictive digital twin can deliver to a manufacturing facility, because it converts the abstract concept of equipment health into a concrete number that maintenance planners, procurement teams, and operations managers can act on. Unlike condition monitoring that tells you something is wrong right now, RUL prediction tells you how long you have before it matters, which transforms maintenance from a reactive scramble or a conservative calendar-based overspend into a precisely timed intervention that maximizes asset utilization while minimizing both failure risk and unnecessary downtime. The gap between facilities that estimate remaining useful life with a digital twin and those that do not is not marginal, it typically represents a 30 to 45 percent reduction in maintenance costs for the covered assets, driven almost entirely by eliminating both the failures that occur between scheduled maintenance intervals and the premature replacements that consume budget and capacity on equipment that still had useful life remaining. Book a demo to see how iFactory builds predictive digital twins that deliver actionable RUL estimates for your critical equipment.
Knowing How Long Your Equipment Has Left Changes Every Maintenance Decision You Make
A predictive digital twin does not just monitor your equipment, it models the degradation happening inside it, estimates how many operating hours or cycles remain before a critical threshold is reached, and tells you exactly when to schedule maintenance to get maximum life from every asset without risking an unplanned failure.
Three Maintenance Strategies, Three Completely Different Cost Curves
The evolution from reactive to preventive to predictive maintenance is well documented, but the financial difference between these strategies is often underestimated because the costs are distributed across so many budget categories that the total is invisible to any single department. The comparison below shows what a typical facility spending one million dollars annually on maintenance for a fleet of rotating equipment experiences under each strategy, with costs broken into the four categories that matter most: unplanned failure costs, scheduled maintenance labor, spare parts consumption, and lost production capacity.
The 35 percent cost reduction from reactive to predictive is not achieved by spending less on maintenance in total but by spending it on the right equipment at the right time. The predictive approach still spends significant money on scheduled labor and parts, but every dollar is directed at equipment that actually needs intervention rather than equipment that happens to be on the schedule regardless of its condition. The unplanned failure reduction alone, from $520,000 to $52,000 in this example, typically pays for the entire predictive twin implementation within the first year of deployment on a fleet of this size.
What Remaining Useful Life Actually Looks Like Inside Your Equipment
Remaining useful life is not a single number pulled from a lookup table, it is the output of a degradation model that tracks how a specific failure mode progresses from healthy to failed over time. The visual below represents the typical degradation curve for a rotating equipment asset like a pump, motor, or fan, showing how health declines as operating hours accumulate and how the predictive twin uses that curve to estimate the remaining window before the failure threshold is crossed.
The most important insight from this curve is not the shape but the fact that the exact position of the degradation onset point, the slope of the decline, and the location of the failure threshold are all different for every individual piece of equipment, even equipment of the same make and model operating in the same facility. This is why fleet-level averages are inadequate for maintenance scheduling and why a digital twin that models each asset individually produces dramatically better RUL estimates than any generic degradation curve can provide.
How a Predictive Digital Twin Estimates Remaining Useful Life Step by Step
The RUL estimation process is a pipeline that starts with raw sensor data and ends with a maintenance recommendation backed by a confidence interval that tells the planner how much trust to place in the estimate. Each step in the pipeline adds value and reduces uncertainty, and skipping any step significantly degrades the quality of the final RUL number.
Stop Replacing Equipment on a Schedule That Has No Relationship to Its Actual Condition
iFactory builds predictive digital twins that track degradation in real time, estimate remaining useful life with quantified confidence, and tell your maintenance team exactly when to act on each asset in your fleet.
Four Degradation Modeling Methods and When Each One Is the Right Choice
Not all equipment degrades in ways that can be captured by a single modeling approach. The choice of degradation model depends on what you know about the failure mechanism, what data you can collect, and how the asset is operated. The four methods below represent the spectrum from physics-heavy to data-heavy, with most practical implementations using a combination rather than relying on a single method in isolation.
| Method | How It Works | Best For | Data Needed | Limitation |
|---|---|---|---|---|
| Physics-Based Degradation | Models the physical wear mechanism such as fatigue crack growth, bearing spall propagation, or erosion using known equations with calibrated parameters | Well-understood failure modes where the governing physics are established and the key parameters can be measured or estimated | Material properties, operating loads, environmental conditions, and initial flaw sizes if applicable | Cannot account for unknown degradation mechanisms or interactions between multiple simultaneous failure modes |
| Data-Driven Degradation | Trains a machine learning model on historical run-to-failure data to learn the statistical pattern of health decline without modeling the underlying physics | Complex systems where the physics are poorly understood but abundant run-to-failure data exists from similar assets in the fleet | Multiple run-to-failure histories with consistent sensor coverage across the degradation trajectory | Cannot predict behavior for operating conditions or failure modes not represented in the training data |
| Stochastic Process Models | Represents degradation as a random process with a drift component and a noise component, updating the RUL distribution as new measurements arrive | Assets where degradation progresses with significant randomness between individual units even under similar operating conditions | Inspection or sensor measurements at discrete intervals showing the degradation trend for the specific asset | Requires enough measurements to estimate the stochastic process parameters, which may not be available early in the asset's life |
| Hybrid Degradation Model | Uses physics to define the degradation structure and data-driven methods to calibrate parameters and correct model residuals in real time | Most practical manufacturing applications where some physics is known but the model needs data-driven correction for accuracy | Partial physics knowledge plus operational sensor data, does not require full run-to-failure histories | More complex to build and validate than single-method models, requires careful integration of the two components |
In practice, the hybrid approach is becoming the default for manufacturing RUL applications because it balances the strengths and weaknesses of the other three methods. The physics component ensures the model produces physically reasonable degradation trajectories even when data is sparse, while the data-driven component corrects for the simplifications and uncertainties in the physics model that would otherwise limit accuracy. For facilities just starting with predictive RUL, beginning with a physics-based or stochastic model on the highest-criticality assets and adding data-driven corrections as operational data accumulates is the most pragmatic path to value.
Failure Probability Rises Non-Linearly as Equipment Approaches End of Life
One of the most common mistakes in maintenance planning is treating failure probability as a linear function of remaining life, assuming that an asset with 20 percent of its estimated life remaining is roughly five times more likely to fail than one with 100 percent remaining. In reality, failure probability for most mechanical degradation modes follows a curve that stays low for most of the asset's life and then rises sharply as the failure threshold approaches, which means the risk profile changes dramatically in the final portion of the RUL window and maintenance timing decisions in that narrow band have an outsized impact on both safety and cost.
The non-linear shape of this curve is precisely why RUL estimates with confidence intervals matter more than point estimates. A point estimate that says an asset has 500 hours of remaining life is dangerous without knowing whether the confidence band is plus or minus 50 hours or plus or minus 400 hours, because the failure probability at 100 hours remaining is dramatically higher than at 500 hours remaining. The predictive twin's value is not just in the central estimate but in the uncertainty quantification that tells the maintenance planner how much scheduling margin they actually have before the failure probability enters the unacceptable range for that specific asset's criticality rating.
The Maintenance Window: Too Early Costs Money, Too Late Costs Production
The concept of a maintenance window is simple in theory but difficult to optimize in practice because it requires balancing three competing objectives that pull in opposite directions. Maintaining too early wastes remaining useful life and increases parts and labor costs. Maintaining too late risks an unplanned failure that costs far more than the maintenance would have. Maintaining at exactly the right time requires a RUL estimate accurate enough to identify that narrow optimal window, which is exactly what the predictive digital twin provides.
The asymmetry in cost consequences is what makes the predictive twin so valuable. Being slightly early costs a modest premium in wasted life, while being slightly late can cost multiples of the original maintenance expense. This asymmetry means the twin does not need to be perfectly accurate to deliver enormous value, it just needs to be accurate enough to keep you out of the late zone and reasonably close to the optimal zone, which is a much lower bar than most people assume when they dismiss RUL prediction as too uncertain to be useful.
What You Actually Need to Build a Predictive RUL Twin That Works
The barrier to building a predictive digital twin for RUL estimation is lower than most facilities assume, but it is not zero. The requirements fall into four categories, and gaps in any single category will degrade the twin's accuracy or delay its deployment. The checklist below is designed to help you assess your readiness before starting a project, so you can address gaps proactively rather than discovering them mid-development when the cost of correction is highest.
Facilities that assess these four categories honestly before starting a predictive RUL project consistently have better outcomes than those that assume the technology will compensate for gaps in data or process. The most common failure mode for RUL twin projects is not technical inadequacy but organizational unpreparedness, specifically a maintenance organization that says it wants condition-based maintenance but continues to plan and budget exclusively on calendar intervals, leaving the twin's recommendations unacted upon regardless of their accuracy.
Common Questions About Predictive Digital Twins for Remaining Useful Life
How accurate are RUL estimates from a predictive digital twin in real manufacturing conditions?
RUL estimate accuracy depends heavily on how far into the degradation trajectory the asset is when the estimate is made, the quality of the sensor data feeding the model, and how well the degradation model matches the actual failure mechanism. Early in the degradation process when the trend is just becoming detectable, confidence intervals are typically wide, often plus or minus 30 to 50 percent of the point estimate, because there is limited data to distinguish between different possible degradation rates. As more degradation data accumulates and the trend becomes clearer, the confidence interval narrows significantly, often to plus or minus 10 to 20 percent in the final third of the RUL window, which is precisely when the accuracy matters most for maintenance scheduling decisions. Book a demo to see how iFactory reports RUL with confidence intervals for real assets.
Can a predictive twin estimate RUL for equipment that has never experienced a failure in our facility?
Yes, but the approach must rely more heavily on physics-based or stochastic degradation models rather than data-driven methods that require run-to-failure histories. If the failure mechanism is well-understood from industry literature or manufacturer data, a physics-based model can be built from material properties, operating conditions, and known degradation equations, then calibrated against the available sensor data even if no failure has been observed yet. The RUL estimates will have wider confidence intervals initially but will narrow as the asset accumulates operating hours and the model validates its degradation trajectory against actual sensor trends. Facilities with limited failure history often start with physics-based models on their most critical assets and transition to hybrid models as data accumulates. Contact support to discuss RUL modeling options for assets without failure history.
What happens to the RUL estimate when operating conditions change, for example a pump running at a higher load than usual?
A properly built predictive twin accounts for operating condition changes by adjusting the degradation rate in real time based on the current load, speed, temperature, and other stress factors that influence how fast the failure mode progresses. If a pump that normally runs at 60 percent load is shifted to 90 percent load, the twin does not continue projecting the same RUL it calculated at the lower load, it recalculates the degradation rate for the new condition and produces a revised RUL estimate that reflects the accelerated wear. This is one of the key advantages of a digital twin over a simple statistical model, because the twin understands the relationship between operating conditions and degradation rate rather than assuming the future will look like the past. Book a demo to see how operating condition changes update RUL in real time.
How many assets can a single predictive digital twin platform handle simultaneously?
Modern predictive twin platforms are designed to scale to hundreds or thousands of assets depending on the computational complexity of the degradation model for each asset type. Simple stochastic or data-driven models with low-dimensional feature sets can run on thousands of assets with modest computing resources, while high-fidelity physics-based models that solve differential equations at each time step may be limited to dozens or hundreds of the most critical assets unless the physics models are pre-computed or reduced to faster surrogate forms. The practical constraint is usually not computing power but data infrastructure, because each asset requires reliable sensor data ingestion, storage, and feature extraction pipelines that must be maintained alongside the models themselves. Contact support to discuss scaling RUL twins across your asset fleet.
How do we validate that the RUL estimates are accurate enough to trust for maintenance scheduling?
RUL validation follows a retrospective testing protocol where the model is run on historical data from assets that have already reached end of life, and the RUL predictions made at various points in the degradation trajectory are compared against the actual remaining life that was observed. This retrospective validation produces accuracy metrics across different prediction horizons, showing how well the model performs when it has 80 percent of life remaining versus 30 percent remaining, which is exactly the information needed to define when the estimate is accurate enough to act on. Most facilities implement a phased trust approach where the twin's recommendations are tracked but not acted on for the first few prediction cycles, building confidence through observed accuracy before transitioning to automated maintenance scheduling. Book a demo to learn about iFactory's RUL validation methodology.
Every Day You Wait to Predict Remaining Useful Life Is a Day Your Maintenance Budget Is Being Spent on the Wrong Equipment at the Wrong Time
iFactory deploys predictive digital twins that model degradation in real time, estimate remaining useful life with quantified confidence, and convert those estimates into maintenance schedules that maximize asset life while minimizing failure risk across your entire fleet.