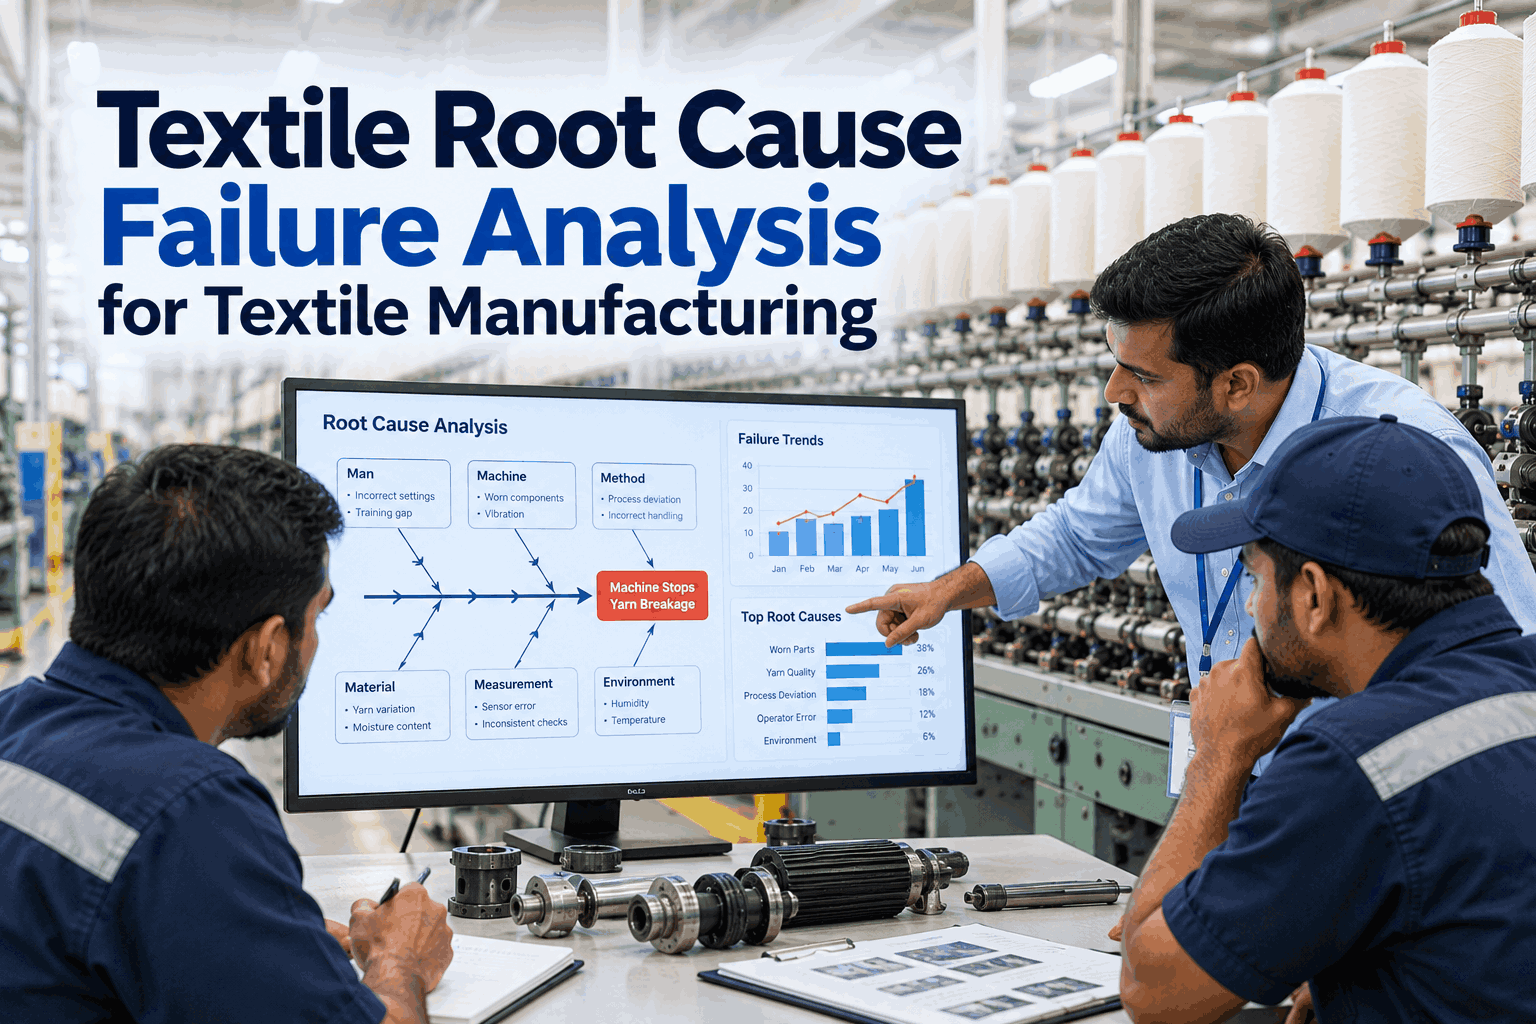
When the same carding cylinder bearing fails for the third time in a year, or a group of looms keeps breaking rapier tapes, replacing the part again is the expensive answer. Root cause failure analysis asks why the failure happened, why it was allowed to happen and what in the system let it repeat, so the fix sticks. This guide covers how to run it for textile machines, and you can see the digital workflow in a short live demo.
Find Out Why Textile Machines Keep Failing, and Stop It Happening Again
iFactory brings failure history, condition data and production records together for each investigation. It guides the team from physical cause to the system gap behind it, and tracks the corrective actions until the failure stops repeating.
Bearing wear from lubricant breakdown
Re-oil interval stretched during a peak season
No PM trigger tied to spindle hours, so the change went unnoticed
Fixing the Part Isn't the Same as Fixing the Problem
Most breakdowns end with the failed part replaced and the machine running again, which is the right first response. But when the same failure keeps coming back, the repair has treated the symptom and left the cause in place. Root cause failure analysis is a structured investigation of equipment failures that goes beyond the broken part to the conditions, decisions and system gaps that allowed it. Our reliability team can help you decide where RCFA will pay off first.
- Replace the failed bearing, tape or belt
- Restart the machine as fast as possible
- Note "bearing failed" on the work order
- Same failure returns in weeks or months
- Cost repeats with every failure
- Repair, but preserve the failed part and evidence
- Establish the physical failure mechanism
- Find the human and system causes behind it
- Change the system so it can't recur
- Verify the failure has stopped
Five Triggers for a Full Root Cause Failure Analysis
RCFA takes time and people, so it shouldn't be run on every breakdown. A mill with hundreds of machines might see dozens of breakdowns a week, and only a handful will justify a full investigation. Clear triggers make the decision consistent and stop teams investigating trivial events while chronic problems go unexamined. You can see trigger rules applied to your failure history in a working session.
Six Steps From Failure to Verified Fix
Most RCFA methods share the same shape. Preserve evidence, describe the failure, find the physical mechanism, trace the human and system causes, act on them, then check that the failure has stopped. Skipping the first or last step is the most common reason investigations fail. Our reliability specialists can help you build the process into your maintenance system.
Keep the failed part, take photos before cleaning, and save the condition data, settings and production record from around the failure.
What failed, where, when, on which machines and under what operating conditions, including count, style and speed.
Determine the mechanism, such as fatigue, wear, overheating, contamination or misalignment, from the evidence.
Ask what decisions or actions led to the condition, and what system, procedure or design allowed them.
Change procedures, PM triggers, designs, specifications or training, not just the part.
Track the failure rate on the affected machines for a set period, and reopen the case if it returns.
Common Failures, Their Usual Causes and the Evidence to Collect
Each textile machine group has its own recurring failure modes, shaped by speed, lint, humidity and the materials being processed. Knowing the usual causes speeds up the investigation, but the evidence still has to confirm which one applies. The matrix below is a starting reference. You can see it built from your own work order history in a short demo.
Start Every Investigation With the Data Already Gathered
iFactory pulls the failure history, condition trends, settings and production records for the affected machines into the RCFA case, so the team starts analyzing instead of searching.
Physical, Human and Latent: Why Stopping at the Part Isn't Enough
A thorough RCFA separates three levels of cause. Physical causes explain how the part failed. Human causes explain what someone did or didn't do that led to the condition. Latent causes are the system gaps, such as procedures, triggers, training or design, that made the human cause likely. Fixing only the physical cause means waiting for the next failure. Fixing the latent cause often prevents failures on machines that haven't failed yet, which is where the biggest savings come from. Our support team can help your team practice the three levels.
Lubricant broke down under higher speed and the bearing wore. This is confirmed by bearing inspection and the oil condition.
The re-oil interval stayed the same after the count change because nobody recalculated it.
The PM system used calendar triggers only, and count changes didn't prompt a maintenance review.
Repeat Spindle Bearing Failures on Five Ring Frames
Here is how the six steps played out on a typical case. The details are illustrative, but the pattern is common: a production change that nobody connected to maintenance. Notice how the comparison with unaffected frames, rather than the failed parts alone, points to the latent cause. You can see a case like this assembled from your own data in a working session.
Six failed spindle bearings were bagged and labelled with frame and position, and oil samples were taken from neighbouring spindles.
Failures were limited to frames RF-10 to RF-14 and started in July. Other frames running the same oil and interval had none.
Inspection showed wear consistent with lubricant breakdown, and the oil samples were degraded.
Production records showed those five frames moved to a finer count in April, which raised spindle speed and running hours.
Oiling moved to a spindle-hour trigger, and count changes now prompt a maintenance review.
Bearing failures on the five frames were tracked for 60 days after the change, with no repeats.
The Strongest Actions Change the System, Not the People
Corrective actions vary a lot in how well they prevent recurrence. Reminding people or retraining helps, but it fades. Changing a trigger, a design or a specification keeps working regardless of who is on shift. Choose the strongest practical action for each latent cause, and pair weaker actions such as training with at least one stronger one. You can see actions tracked to effectiveness in a guided demo.
Four Ways Root Cause Failure Analysis Goes Wrong
RCFA programs often start well and then lose credibility. These four pitfalls are the usual reasons, and each one is avoidable with a clear process. Our reliability specialists can review your recent investigations against them.
RCFA Workflow, Data Connections and AI Server in One Package
iFactory delivers the RCFA workflow as a turnkey bundle. A pre-configured NVIDIA AI server ships racked and ready with the software pre-loaded. You rack it, plug in power and Ethernet, and the AI is live. To scope it for your mill, request a turnkey quote.
- Pre-configured NVIDIA AI edge server, racked and ready
- Connectors for CMMS, machine and condition data
- RCFA case templates with trigger rules
- Cabling and plant network setup
- Action tracking and effectiveness monitoring
- Training for engineers, supervisors and technicians
- 24×7 remote monitoring
Server installed, failure history and machine data connected, failure codes cleaned.
Two or three chronic failures investigated with the new workflow.
Trigger rules on, team trained, effectiveness reviews scheduled.
Root Cause Failure Analysis Built Into Maintenance
iFactory connects failures, evidence, causes and actions so investigations are faster and their results last. Our support team can review your current approach before a pilot.
What Textile Reliability Teams Ask About RCFA
Stop Paying for the Same Failure Twice
Trigger investigations automatically, start every case with the evidence gathered, trace failures to their system causes and confirm the fix holds. The full system is delivered turnkey and goes live in 6 to 12 weeks.