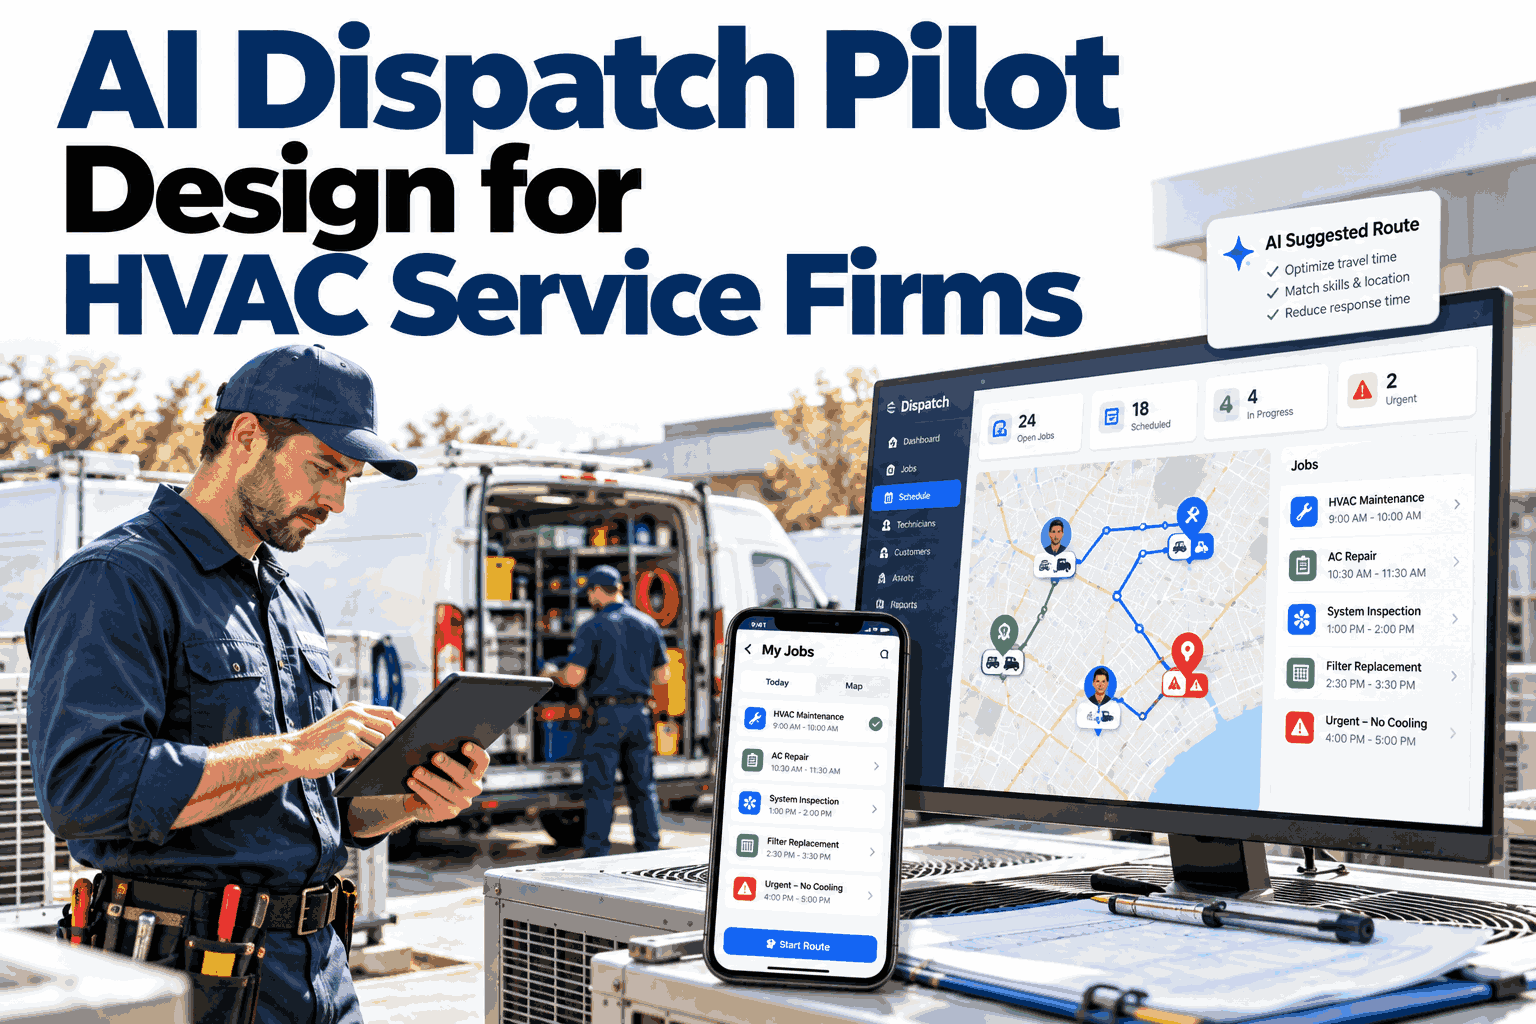
Most AI dispatch pilots fail for a reason that has nothing to do with the AI: nobody defined what "working" meant before it started. A dispatcher reverts to gut feel on a busy day, and ninety days later the only evidence is a feeling that things improved. HVAC firms need a pilot built like an experiment, not a demo. Talk through a pilot design with the iFactory AI team before the next busy season.
Design a 90-Day AI Dispatch Pilot HVAC Leadership Will Actually Trust
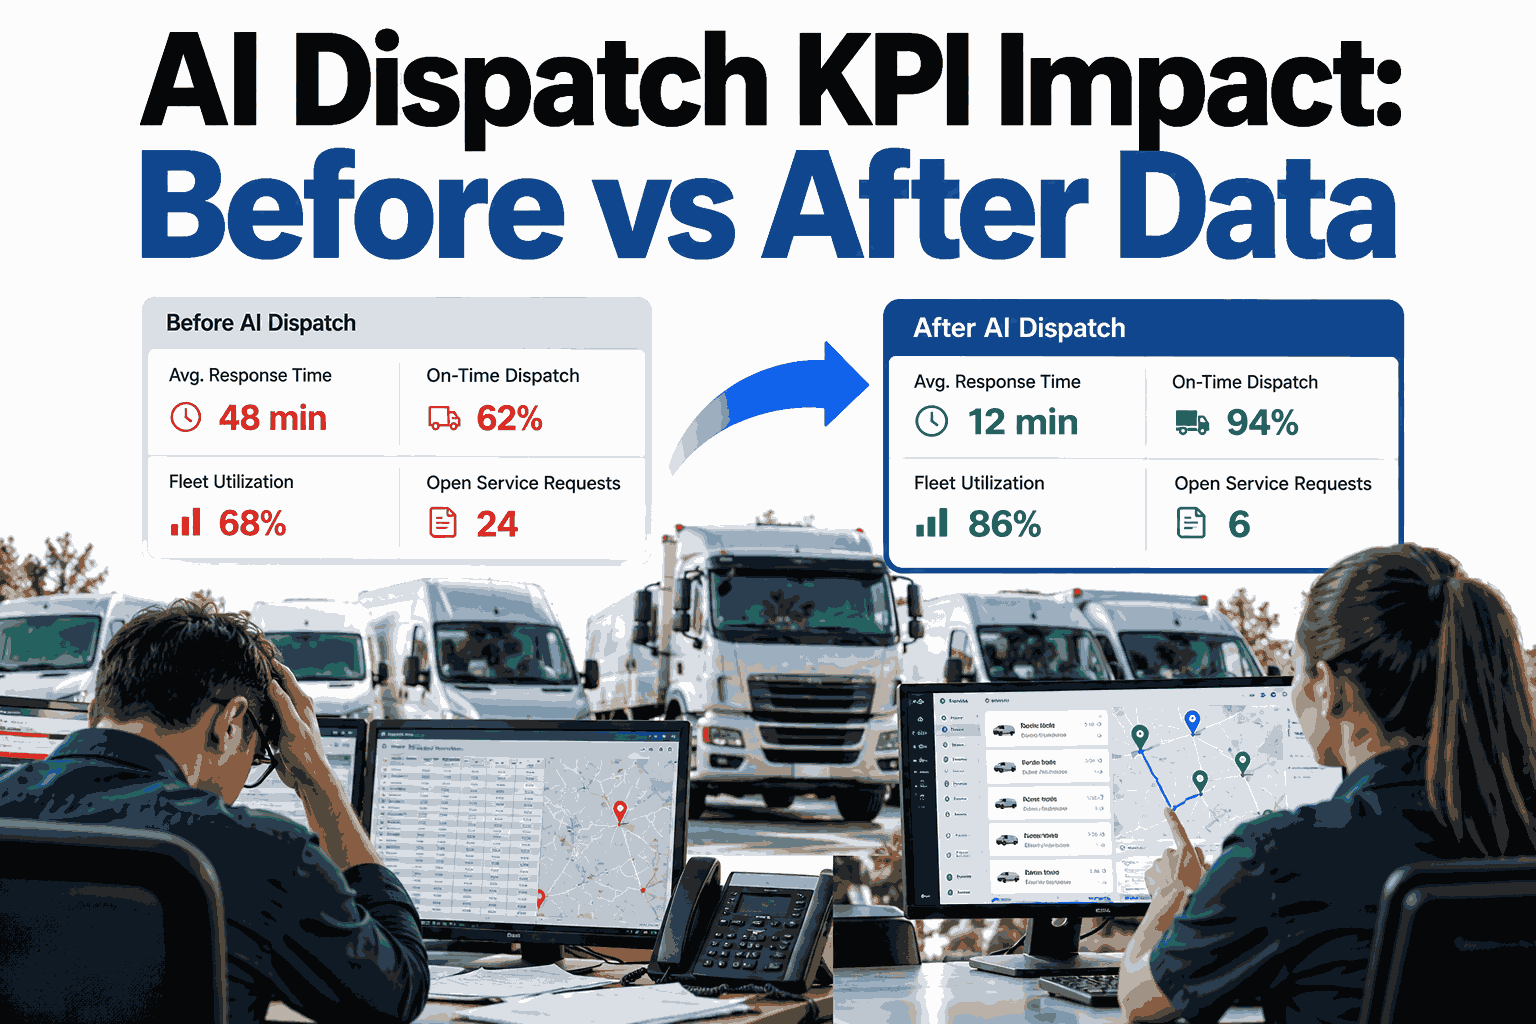
A defensible pilot has a control group, a locked scope, named success metrics, and gating criteria agreed before day one — not a dashboard built after the fact to justify a decision already made.
Why Most Dispatch Pilots Produce an Opinion, Not an Answer
A pilot that only watches the new way of working, with nothing to compare it against, cannot tell a real improvement from a normal good week. Four gaps turn a pilot into theater.
No Control Group
Every truck switches to AI dispatch on day one, so there is no baseline running in parallel. Any seasonal dip or spike gets credited to or blamed on the software.
Metrics Defined After the Fact
Leadership asks "did it work?" ninety days in, and whichever number looks best becomes the headline. A pilot without a pre-agreed scorecard invites this.
No Named Gate to Scale
Nobody decided in advance what result would justify rolling out fleet-wide, so the decision to expand becomes political rather than evidential.
Dispatcher Override Goes Untracked
Technicians and dispatchers quietly revert to manual routing when the AI suggestion looks wrong, and nobody is counting how often that happens or why.
A pilot built like an experiment survives the question "how do you know?" A pilot built like a demo does not.
Step 1: Scope the Pilot Before You Scope the Software
Scope is the most skipped step because it feels like paperwork. It is the difference between a pilot that answers a question and one that just generates activity.
Write the scope down and have operations and the AI vendor sign off on it together. A scope that only lives in someone's head gets redrawn after the results come in, which is exactly the problem a pilot is supposed to prevent. Walk through scope options with the iFactory AI team.
Step 2: Build a Real Control Group
Field service rarely has the luxury of a lab, but a workable control is still possible, and it is what separates a pilot from a rollout with a dashboard attached.
Split by Truck or Zone
Run AI dispatch on half the trucks or one service zone, and keep the other half on the existing manual or legacy-software process for the same ninety days.
Split by Week
Alternate weeks between AI-assisted and manual dispatch across the same trucks, which controls for truck-specific or technician-specific variation.
Historical Baseline Plus Live Control
Where a true parallel split is not operationally possible, pair last year's same-season data with a smaller live control group to catch anything the historical data would miss.
Whichever split is chosen, keep the comparison apples-to-apples: same job mix, same geography, same technician skill level on both sides, so any gap between groups is attributable to dispatch method and not to who got the easier day.
See a Control-Group Pilot Structure Built Around Your Fleet
Bring your truck count, service area, and call mix to a 30-minute session and leave with a scoped pilot plan, not a sales pitch.
Step 3: Pick a Scorecard, Not a Vibe Check
A short list of metrics, agreed in writing before the pilot starts, keeps the ninety-day review from turning into an argument about which number counts.
| Metric | What It Actually Measures | Why It Belongs on the Scorecard |
|---|---|---|
| First-Time Fix Rate | Jobs closed without a return visit for the same issue | Catches whether better-matched technician skill assignment is actually reducing repeat trips, not just moving trucks faster |
| Drive Time Per Job | Minutes spent traveling between jobs, not on site | The most direct routing metric, and the easiest to compare cleanly against a control group |
| Jobs Completed Per Technician Per Day | Throughput per truck, adjusted for job type mix | Surfaces capacity gains, but only means something if the job mix between test and control is genuinely comparable |
| Dispatcher Override Rate | How often a human changes the AI-suggested assignment or route | A high override rate is an early warning the model does not yet trust local conditions dispatchers know |
| Customer Promised-Window Accuracy | Share of jobs where the technician arrived inside the window given to the customer | Connects dispatch quality to the number customers and call center staff actually feel |
Five metrics is enough. A scorecard with twenty line items guarantees that something will look good no matter what happened, and that defeats the point of running a control group in the first place.
Step 4: Set the Gates Before You Need Them
A gate is a pre-agreed threshold that triggers a decision. Setting gates after seeing the results is not gating, it is rationalizing.
Technical Stability
The system must stay connected to live routes and technician status without manual re-sync for two consecutive weeks before any performance number is trusted.
Override Rate Below Threshold
Dispatcher overrides should trend downward and settle under an agreed ceiling, showing the team is adopting the suggestions rather than working around them.
Scorecard Beats Control
The test group must outperform the control group on at least three of the five agreed metrics, not just one favorable headline number.
Field Team Sign-Off
Technicians and dispatchers who actually used the system for ninety days get a real vote on whether it is ready to scale, not just a survey nobody reads.
Clearing all four gates is the trigger to expand. Missing two or more is the trigger to extend the pilot or revisit the configuration, not to abandon the idea outright.
The 90-Day Pilot Timeline
A pilot without a calendar drifts. Each phase has a clear exit condition before the next one starts.
Weeks 1-2: Scope, Split, and Baseline
Lock the fleet slice, confirm the control-group split, and pull ninety days of historical data to sanity-check that test and control groups look comparable before anything goes live.
Weeks 3-4: Connect and Configure
Wire the AI dispatch layer to live technician locations, skills, and job queues for the test group only. The control group keeps running exactly as before.
Weeks 5-10: Run and Track Weekly
Both groups run in parallel. The five-metric scorecard is pulled weekly, not just at the end, so a problem shows up in week six instead of week thirteen.
Weeks 11-12: Gate Review and Decision
Compare the full scorecard against the control group, check all four gates, and make one of three calls: scale, extend, or stop.
Ninety days is long enough to average out a few bad weeks, and short enough that a stalled pilot does not quietly become permanent. Teams can map this timeline onto their own fleet and season before committing a date.
Three Ways Pilots Get Quietly Rigged
None of these require bad intent. They happen because a pilot is being run by people who also want it to succeed, and small choices tilt the outcome without anyone noticing.
Best Technicians in the Test Group
If the strongest, most senior technicians end up on the AI-assisted side, the improvement reflects their skill, not the software. Assign groups by truck or zone, not by hand-picking people.
Easy Jobs Routed to the Test Group
A dispatcher who wants the pilot to look good may unconsciously steer simpler, higher-margin jobs toward the AI-assisted trucks. Job assignment should be randomized or rule-based, not discretionary.
Metrics Swapped Mid-Pilot
If first-time fix rate is lagging in week six, swapping it out for a metric that looks better defeats the purpose of agreeing on a scorecard in advance. Lock the metrics and report all of them, good or bad.
A pilot that cannot survive scrutiny from a skeptical ops VP is not ready to justify a fleet-wide rollout.
What iFactory AI Brings to a Dispatch Pilot
iFactory AI is smart manufacturing and industrial software, and the same auto scheduling and routing engine that runs plant-floor work orders applies directly to field dispatch: rule-based assignment, live routing, and a full audit trail of every suggestion and every override.
iFactory AI arrives pre-configured on an NVIDIA server that ships racked and ready with the dispatch and routing module pre-loaded. Rack it, connect power and Ethernet, and pilot configuration begins. Scope covers cabling, network, field-service software integration, team training, and 24x7 remote monitoring.
Pilot Readiness Self-Check
Use these ten checks before committing a launch date. Each unchecked box is a gap that will surface during the ninety days, not before.
A pilot that passes all ten checks before launch is far more likely to produce a result leadership will actually act on.
Frequently Asked Questions
How many trucks does a credible pilot actually need?
There is no fixed number, but enough trucks on each side to smooth out single bad days — most HVAC firms running a defensible split use somewhere between six and twenty trucks per group, depending on total fleet size. Size a pilot against your own fleet in a short session rather than guessing.
What if we genuinely cannot run a parallel control group?
A historical baseline paired with a smaller live control is the fallback, and it is still far stronger than no comparison at all. Match the historical period to the same season and job mix so weather and demand do not distort the comparison.
Should emergency no-cool calls be included in the pilot?
Most firms exclude same-day emergency dispatch from the initial pilot and add it once the routine-maintenance and scheduled-service workflow has cleared its gates. Emergency calls carry enough variance on their own to muddy an early comparison.
What happens if the pilot misses a gate?
Missing one gate is usually a signal to extend the pilot a few weeks and address the specific gap, such as a high override rate, rather than treating it as a failed experiment. Missing most or all four gates is the signal to revisit configuration before trying again.
How is dispatcher override rate actually tracked?
Every time a dispatcher accepts, edits, or rejects an AI-suggested assignment, that action and the stated reason are logged against the job record. Ask how override logging is configured for a specific dispatch workflow.
Start a Pilot Built to Survive Scrutiny
iFactory AI configures the split groups, tracks the scorecard weekly, and logs every override, so the gate review runs on agreed numbers instead of an argument. Book a session using your own fleet and service area.