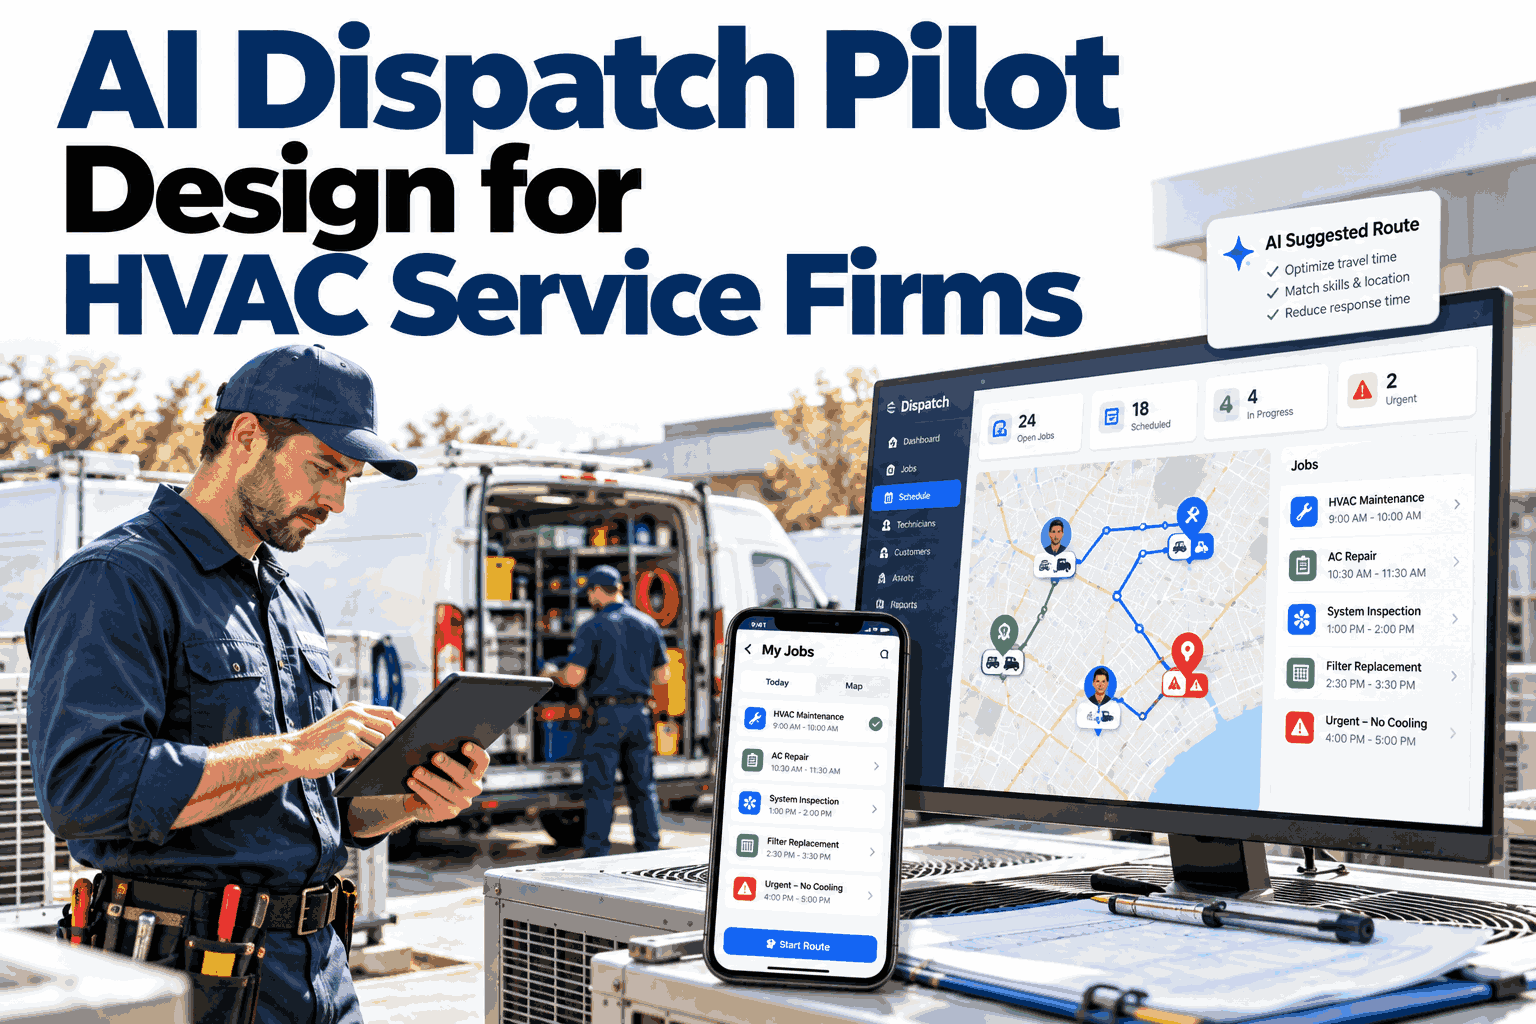
Running AI dispatch on live HVAC calls without a structured pilot is the fastest way to get a number no one believes. When a scheduler says the AI is cutting drive time and a field manager says the crews seem busier, the debate stays a debate until someone designs it out. A 90-day pilot with a defined control group, agreed metrics and pre-written gate criteria converts that argument into evidence the whole business can act on. If you want to see how iFactory AI structures that proof before committing to a full rollout, schedule a pilot scoping session with the dispatch team.
AI Dispatch · 90-Day Pilot Design
Design Your HVAC AI Dispatch Pilot So the Results Are Defensible
iFactory AI gives HVAC service firms the pilot framework, control group logic and gate criteria to run a proof of concept that stands up to scrutiny — and scales when it passes.
Week 8 of 12 — Live pilot view
Active
Control Group
Manual dispatch — existing process
Avg drive time per call
38 min
First-time fix rate
61%
Jobs completed per tech/day
4.1
SLA breach rate
14%
Overtime hours / week
22 h
Treatment Group
AI-assisted dispatch — pilot cohort
Avg drive time per call
24 min
First-time fix rate
74%
Jobs completed per tech/day
5.3
SLA breach rate
6%
Overtime hours / week
9 h
Figures shown are illustrative pilot outputs. Actual results depend on dispatch volume, territory geography and call-type mix.
Why most HVAC AI trials fail to convince
The Proof of Concept Problem in Field Service
Most HVAC service firms that try AI dispatch tools do not run out of technology. They run out of evidence. A pilot that goes live without a control group produces a number, but no comparison. A pilot that tracks the wrong metrics produces a comparison, but one that nobody in the business cares about.
No baseline measurement
Starting the pilot without recording what current performance actually looks like. Post-pilot results have nothing to be compared against, so improvement is estimated, not measured.
No control group
Applying AI dispatch to everyone at once. If a seasonal uptick also happens that month, there is no way to separate the AI effect from the calendar effect.
Wrong success metric
Measuring what is easy to export, such as number of suggestions made, rather than what the business is actually trying to improve, such as drive time or overtime cost.
No go/no-go criteria
Ending the pilot with a list of observations instead of a pre-agreed threshold. When that threshold was never set, whoever is skeptical can always argue the result is not good enough.
A well-structured pilot eliminates all four problems before day one. The design work is done in the weeks before go-live, not in the debrief meeting at the end.
Pilot scope
How to Define the Right Scope for a 90-Day HVAC Dispatch POC
Scope decisions made before the pilot starts determine how clean the evidence is when it ends. The goal is a representative test, not an easy one.
Call volume
Aim for at least 400 to 600 dispatched calls across the pilot period. Below that, individual-week variation can swamp the signal. Above 2,000, the pilot is effectively the full operation already.
Technician cohort
Select 8 to 14 technicians for the treatment group and a comparable number for control. Match them by average call mix, territory overlap and tenure so the groups start on even ground.
Call type mix
Include both reactive service calls and planned maintenance visits. An AI dispatch system that only looks good on reactive calls may not hold up when planned route density changes.
Geography
Keep the pilot within one or two dispatch regions so traffic and territory structures are comparable. Mixing dense urban and sparse rural in the same test adds noise without adding insight.
Seasonality window
Start the pilot at the beginning of a recognisable demand cycle, not in the middle. Both groups should face the same seasonal load across the 90 days.
Dispatcher involvement
In the treatment group, dispatchers review and accept AI suggestions rather than being bypassed. The pilot tests human-plus-AI performance, not autonomous scheduling, which is a later-stage decision.
Scope that is too small makes the pilot inconclusive. Scope that is too large makes it disruptive. The 90-day timeline and the 8-to-14 technician band sit in the window where most HVAC service firms get clean results without affecting customer service levels.
Control group design
Building a Control Group That Makes the AI Result Mean Something
The control group is the single most important structural decision in a field service pilot. Without it, any improvement could be attributed to seasonal demand, new-hire additions, natural learning curves or better weather for driving.
Control group construction checklist
Match by territory, not by region
If your treatment group covers the north suburbs, your control group should also cover the north suburbs, not a different metro. Territory geography is the biggest driver of drive-time variation.
Match by call-type ratio
If 60% of the treatment group's calls are reactive and 40% are planned, the control group should be within five percentage points of that split. A control group heavy on planned maintenance will look faster on drive time for reasons that have nothing to do with dispatch.
Match by technician tenure band
Senior technicians have memorised routes and client locations. If your treatment group is predominantly junior and your control group is mostly senior, the AI group will look worse on first-time fix rate regardless of the dispatch quality.
Keep the control group on the same dispatch platform
If the control group switches software mid-pilot, any change in their metrics is contaminated. Both groups run the same underlying platform; only the dispatch logic differs.
Prevent cross-contamination
If dispatchers who see AI suggestions for the treatment group also informally apply those routing ideas to the control group, the control is no longer a control. Assign separate dispatchers or create a process firewall.
Record the baseline for both groups before day one
Pull 90 days of pre-pilot data for every technician in both groups, covering the same metrics you plan to track. This becomes the anchor that tells you where each group started, not where they ended up.
A structurally sound control group does not need to be perfect. It needs to be honest. Small imbalances can be noted in the debrief. Undisclosed imbalances destroy the credibility of the result.
Design Your Control Group Before You Go Live
The iFactory AI team works with HVAC dispatch managers to define cohort structure, pre-pilot baselines and contamination controls before the pilot clock starts.
Success metrics
The Eight Metrics That Make an HVAC AI Dispatch Pilot Measurable
Choosing metrics before the pilot starts is not bureaucracy. It is the only way to prevent the retrospective argument that the metrics that showed improvement were not the important ones.
Primary
Average drive time per job
This is what AI routing directly controls. A 15 to 25% reduction is the most common first-pilot result for firms with dense urban call volumes.
Measured in minutes from departure to arrival, pulled from GPS or field app timestamps.
Primary
First-time fix rate
AI dispatch improves fix rates when it matches call type to technician skill and part load. A five to twelve point gain is meaningful and measurable within 90 days.
Measured as percentage of jobs closed without a return visit within five business days.
Primary
Jobs completed per technician per day
Throughput is the capacity story. If drive time drops but job count stays flat, the time savings went somewhere other than additional work. This metric shows where it went.
Measured as total closed work orders divided by technician-days worked.
Secondary
SLA compliance rate
For firms with contractual response windows, SLA performance is the number customers actually see. Improvement here translates directly to contract retention.
Measured as percentage of jobs where first response falls within the agreed window.
Secondary
Overtime hours per week
If the AI is routing efficiently, more jobs should complete within the standard shift. Overtime burn rate is a labour cost metric that finance understands immediately.
Measured from payroll records for treatment and control groups separately.
Secondary
Dispatcher decisions overridden
This measures adoption, not performance. If dispatchers override more than 40% of suggestions, the AI is not yet calibrated to local routing logic and the pilot should pause for retraining.
Measured as percentage of AI suggestions accepted versus modified or rejected.
Guard rail
Customer satisfaction score
No operational improvement justifies a drop in customer experience. If CSAT for the treatment group falls below the control group at any check-in, the pilot review should happen immediately rather than at week twelve.
Measured via post-job survey or NPS, with results broken out by pilot cohort.
Guard rail
Technician workload balance
AI routing can quietly concentrate heavy call loads on the technicians closest to demand clusters. A Gini-style spread check across daily job counts prevents the pilot from burning out a subset of the team.
Measured as standard deviation of daily job counts across technicians in the treatment group.
Primary metrics determine whether the pilot passes. Secondary metrics explain what drove the change. Guard rail metrics determine whether the pilot should be paused. Define all eight before day one, assign an owner to each, and confirm the data source and pull method so there are no surprises at the midpoint review.
Pilot timeline
A Week-by-Week Structure for the 90-Day Proof of Concept
A 90-day HVAC dispatch pilot divides cleanly into four phases. Each phase has a defined output, so the team knows what they are producing before each week starts.
Weeks 1 to 2 — Design and baseline
Finalise the control group structure. Pull 90 days of pre-pilot data for both cohorts. Confirm baseline values for every metric and record them in a shared document that all stakeholders have signed off. Set the go/no-go thresholds in writing.
Output: signed baseline document and gate thresholds
Weeks 3 to 4 — Soft launch
Go live with AI dispatch suggestions for the treatment group. Dispatchers are in review mode, accepting or modifying every recommendation. The focus in these two weeks is override rate and system stability, not outcome metrics. A high override rate triggers a recalibration conversation rather than a pause.
Output: override rate report and recalibration notes if needed
Weeks 5 to 10 — Full measurement window
The primary evidence-collection period. Weekly data pulls are compared against the control group on all eight metrics. A midpoint review at week seven checks guard rail metrics and allows the scope to be adjusted if a systemic problem appears — not to change the success criteria, only to catch a safety issue early.
Output: weekly comparison tables and midpoint memo
Weeks 11 to 12 — Analysis and gate decision
Aggregate the full measurement window. Run the gate criteria. Present results against the pre-agreed thresholds. Document the assumptions, any confounding factors and the recommended next step — whether that is a full rollout, an extended pilot or a reconfiguration. The gate decision belongs to the stakeholders, not the technology vendor.
Output: final pilot report and gate decision memo
The phased structure keeps the analysis honest because the midpoint review cannot change what a pass looks like. Any change to success thresholds after data collection starts is a result adjustment, not a pilot adjustment, and it invalidates the proof.
| Phase |
Weeks |
Key activity |
Who owns it |
Output |
| Design and baseline |
1–2 |
Cohort matching, pre-pilot data pull, threshold sign-off |
Dispatch manager + iFactory AI team |
Baseline document |
| Soft launch |
3–4 |
AI suggestions live, override rate monitored, recalibration if needed |
Dispatchers + AI team |
Override rate report |
| Full measurement |
5–10 |
Weekly data comparison, midpoint guard rail review |
Ops analytics + dispatch manager |
Weekly tables, midpoint memo |
| Analysis and gate |
11–12 |
Aggregate results, apply gate criteria, recommend next step |
Senior ops leadership |
Final report and gate memo |
Gate criteria
The Pre-Written Go/No-Go Decision That Removes Subjectivity From the Outcome
Gate criteria answer one question: what would the results have to show for this pilot to justify a full rollout? Writing that answer before the data exists is what makes the decision defensible.
Pass thresholds
Average drive time
Treatment group at least 15% lower than control group over weeks 5 to 10
First-time fix rate
Treatment group at least 5 percentage points above control group
Jobs per technician
Treatment group at least 0.5 additional jobs per day versus control
Override rate
Dispatcher acceptance above 65% by week 8
Automatic pause triggers
CSAT gap
Treatment group CSAT drops more than 8 points below control group at any two consecutive weekly reads
Workload concentration
Standard deviation of daily job counts in treatment group exceeds 2.5 times the pre-pilot baseline
SLA breach
SLA breach rate in treatment group exceeds the control group by more than 5 percentage points for three consecutive weeks
Data quality
More than 15% of treatment group records missing GPS or timestamp data in any two-week window
The pause triggers are not failures. They are safeguards. A pause allows the team to investigate whether the AI configuration, the control group design or an external factor is responsible before the measurement window is wasted on contaminated data.
Thresholds shown here are starting-point examples. The right numbers depend on your baseline performance, call-type mix and service agreements. Setting them requires a scoping conversation, not a template.
Common mistakes
Six Pilot Design Errors That Make HVAC AI Results Impossible to Use
Each of the following is recoverable before the pilot starts and much harder to fix once data collection is underway.
01
Running the pilot during peak demand season without noting it
Peak season inflates job counts regardless of dispatch quality. If your control group is running in off-peak and your treatment group is in peak, the throughput comparison is invalid before anyone looks at an AI suggestion. Document the demand context for every week of the pilot in the final report.
02
Using a different data source for treatment and control
If treatment group drive times come from a GPS platform and control group drive times come from dispatcher call logs, the measurement error is probably larger than the improvement you are trying to detect. Both groups need the same source and the same extraction method.
03
Letting dispatchers know which group is which
If dispatchers know the control group is the comparison, they may unconsciously give it more manual attention to make the comparison fair. That produces a flatter result than the AI deserves. Where possible, the data pull should be blinded until the analysis phase.
04
Measuring only what the software dashboard shows
AI dispatch platforms will surface the metrics they perform well on by default. A complete pilot pulls primary metrics from your own systems, not just from the vendor dashboard, so the numbers are independently verifiable and the vendor cannot define what a success is.
05
Adding technicians to the treatment group mid-pilot
Once a technician enters the treatment group, their data before entry is excluded from the measurement window. Adding people mid-pilot changes the group composition and makes the week-over-week trend unreliable. Fix the cohort size before week three and do not change it.
06
Treating a positive pilot result as proof of scale
A 90-day pilot on 10 technicians in one region is evidence of local viability, not enterprise-wide outcome. The pilot report should explicitly state what assumptions need to hold at scale and which variables to re-test when the rollout expands to new regions or call-type mixes.
None of these mistakes is unusual. They appear in pilot designs across every industry where field operations are complex. The fix is the same in each case: document the design decision before the pilot starts, not the result after it ends. Teams that want to pressure-test their pilot design against this list can walk through it with iFactory AI before going live.
Readiness check
What Your HVAC Dispatch Operation Needs Before a Pilot Can Start
A pilot can begin when these conditions are in place. Missing any one of them does not mean you cannot proceed — it means the first task is to fill the gap, not to start measuring.
Data readiness
GPS or mobile app timestamps available for both control and treatment groups
Job closure records tagged by technician and call type for the past 90 days
SLA window and compliance records exportable from your current platform
CSAT collection in place and linked to individual job IDs
Operational readiness
At least 8 technicians available for treatment group who will not change territory during the pilot
Dispatch team willing to review and log AI suggestions rather than bypass them
No major staffing changes planned in either cohort for the 12-week window
Seasonal demand context documented so it can be noted in the final report
Stakeholder readiness
A named pilot owner in dispatch operations who can call the pause if a trigger fires
Finance or ops leadership aware of the pilot and committed to the pre-written gate thresholds
IT aligned on data extraction method and frequency of pulls
Field supervisor briefed so technicians understand the pilot is on their cohort, not evaluating their individual performance
Most HVAC service firms with 20 or more technicians and an existing field service platform can meet these conditions within two to three weeks of deciding to run a pilot.
Frequently asked questions
What HVAC Dispatch Managers Ask About Designing an AI POC
How do we stop the control group from becoming a disadvantaged group?
The control group continues with the current dispatch process, which means it receives the same quality of dispatch management it has always received. Nothing is deliberately withheld. The concern about a disadvantaged control group usually reflects a worry that the current process is already underperforming, which is precisely the baseline the pilot is designed to measure.
Discuss control group ethics with the iFactory AI support team before your design is finalised.
What if our dispatch volume is too low for a statistically meaningful result?
Firms with fewer than 200 calls per month can still run a pilot, but the result needs to be described as directional evidence rather than a statistically confident finding. The practical standard for a small operation is a consistent pattern over the full measurement window rather than a single average that might reflect a good or bad week. Extending the pilot to 120 or 150 days increases the sample enough to draw clearer conclusions.
Walk through your call volume with us to determine the right window length.
Can we run the pilot alongside our existing FSM platform?
Yes. iFactory AI is designed to layer over your existing field service management platform rather than replace it. Dispatch suggestions appear in the dispatcher interface and are accepted, modified or overridden there. The platform that holds your job records, technician profiles and scheduling rules stays in place throughout the pilot, which also means your control group is untouched.
Ask the support team about integration with your specific platform.
How do we handle technician resistance to AI-suggested routing?
Resistance is most common when technicians believe the AI does not know their territory or customer relationships as well as they do. In the first two weeks, dispatchers should be in active dialogue with the field about which suggestions seem off and why. That feedback directly improves the routing model. The override rate metric tracks this: a falling override rate week over week is the best evidence that trust is building. Framing the pilot as a tool review rather than a performance review reduces defensive reactions significantly.
See how the dispatcher review screen works in a live walkthrough.
What happens after the pilot passes the gate?
The gate decision memo becomes the rollout brief. It documents the conditions under which the AI performed well, the metrics that should continue to be tracked at scale, the regional or call-type assumptions that need validation in the next cohort, and the reconfiguration steps if any guard rail triggered during the pilot. A passed gate does not mean a blanket deployment. It means the evidence justifies expanding the test to the next region or technician group under the same measurement discipline.
Ask about the scale-up process for HVAC dispatch portfolios.
From proof of concept to full fleet
Start Your 90-Day HVAC AI Dispatch Pilot With a Design That Holds Up
iFactory AI works with HVAC service operations teams to design pilots that produce evidence their leadership will act on — with control group structure, gate criteria and rollout planning built in from the start.